Automation and AI-Powered Prediction in Chromatographic Separation
英文原文与中文译文逐段对照 · English original with Chinese translation
Chengchun Liu and Fanyang Mo*
刘丞军和莫凡洋*
CONSPECTUS: Chromatography remains one of the most versatile separation technologies in chemistry, spanning thin-layer chromatography (TLC) for rapid analysis, column chromatography (CC) for purification, gas chromatography (GC) for volatile analytes, and high-performance liquid chromatography (HPLC) for precise and enantioselective separations. Despite its centrality, the development of chromatographic methods has long relied on empirical trial-and-error and tacit practitioner knowledge, making reproducibility and systematic optimization difficult. The convergence of laboratory automation and artificial intelligence (AI) is now reshaping this landscape. Automated platforms generate large-scale, standardized data sets, while machine-learning models
概述:色谱法仍然是化学领域中用途最广泛的分离技术之一,涵盖用于快速分析的薄层色谱法(TLC)、用于纯化的柱色谱法(CC)、用于挥发性分析物的气相色谱法(GC)以及用于精确和对映体选择性分离的高效液相色谱法(HPLC)。尽管其处于核心地位,但色谱方法的发展长期以来一直依赖于经验性的反复试验和从业者的隐性知识,这使得重现性和系统优化变得困难。实验室自动化和人工智能(AI)的融合正在重塑这一局面。自动化平台生成大规模、标准化的数据集,而机器学习模型
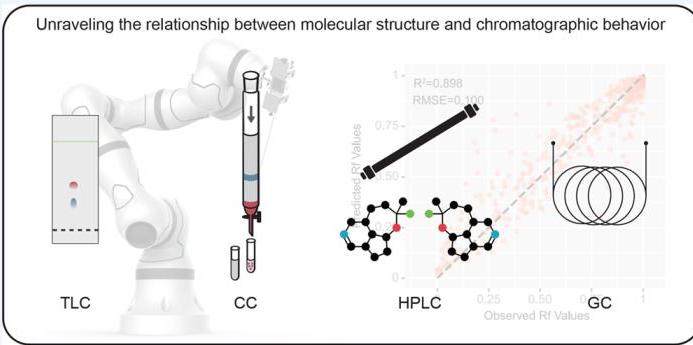
capture quantitative relationships between molecular structures, chromatographic conditions, and retention outcomes. Crucially, by embedding mechanistic constraints-such as polarity-driven adsorption, programmed heating effects, or stereochemical recognition-models transcend black-box prediction and deliver interpretable insights into separation mechanisms. Our research illustrates how chromatography can be transformed into a predictive science through the integration of automation, machine learning, and cross-method transfer. Robotic TLC and CC systems provide reproducible polarity data that inform predictive models and even transferable equations linking TLC ${R}_{f}$ values to CC retention volumes. Multimodal frameworks extend these principles to GC, combining molecular features with heating programs to predict retention under dynamic conditions. For HPLC enantioseparation, chirality-aware graph neural networks capture subtle stereochemical differences and, when coupled with uncertainty quantification, yield separation probabilities that mirror experimental decision-making. This Account focuses on the development of a unified framework for AI-assisted chromatography, highlighting advances in data acquisition, feature engineering, algorithmic design, and cross-scale modeling. Together, these developments chart a path toward universal chromatographic predictors-tools that are accurate, interpretable, and transferable across methods. By closing the loop with automated experimentation, they lay the foundation for predictive and programmable chromatography capable of accelerating discovery and enhancing reproducibility across the chemical sciences.
捕捉分子结构、色谱条件和保留结果之间的定量关系。至关重要的是,通过嵌入诸如极性驱动吸附、程序升温效应或立体化学识别等机理约束,模型超越了黑箱预测,并提供了对分离机制的可解释见解。我们的研究说明了如何通过自动化、机器学习和跨方法转移的整合将色谱法转变为一门预测科学。机器人TLC和CC系统提供可重现的极性数据,这些数据为预测模型提供信息,甚至提供将TLC ${R}_{f}$值与CC保留体积联系起来的可转移方程。多模态框架将这些原理扩展到GC,将分子特征与升温程序相结合以预测动态条件下的保留情况。对于HPLC对映体分离,具有手性感知的图神经网络捕捉细微的立体化学差异,并与不确定性量化相结合时,产生反映实验决策的分离概率。本综述重点关注用于人工智能辅助色谱法的统一框架的发展,突出了数据采集、特征工程、算法设计和跨尺度建模方面的进展。这些发展共同描绘了一条通向通用色谱预测器的道路——这些工具准确、可解释且可跨方法转移。通过与自动化实验形成闭环,它们为能够加速发现并提高整个化学科学领域重现性的预测性和可编程色谱法奠定了基础。
KEY REFERENCES
关键参考文献
Xu, H.; Lin, J.; Liu, Q.; Chen, Y.; Zhang, J.; Yang, Y.; Young, M. C.; Xu, Y.; Zhang, D.; Mo, F. High-throughput discovery of chemical structure-polarity relationships combining automation and machine learning. Chem 2022, 8, 3202. ${}^{1}$ This study integrates automated TLC experiments with machine learning to reveal structure-polarity relationships, enabling predictive chromatography and accelerating data-driven chemical discovery.
徐,H.;林,J.;刘,Q.;陈,Y.;张,J.;杨,Y.;杨,M. C.;徐,Y.;张,D.;莫,F. 结合自动化和机器学习的化学结构 - 极性关系的高通量发现。《化学》2022年,第8卷,第3202页。${}^{1}$ 本研究将自动薄层色谱实验与机器学习相结合,以揭示结构 - 极性关系,实现预测性色谱分析并加速数据驱动的化学发现。
Wu, W.; Xu, H.; Xu, Y.; Luo, P.; Zeng, Q.; Chen, Y.; Xu, Y.; Zhang, D.; Mo, F. Intelligent column chromatography prediction model based on automation and machine learning. Chem 2025, 11, 102598. ${}^{2}$ This work develops an intelligent model integrating automated data collection and machine learning to predict column-chromatography behavior, enhancing purification efficiency and reducing empirical trial-and-error.
吴,W.;徐,H.;徐,Y.;罗,P.;曾,Q.;陈,Y.;徐,Y.;张,D.;莫,F. 基于自动化和机器学习的智能柱色谱预测模型。《化学》2025年,第11卷,第102598页。${}^{2}$ 这项工作开发了一个集成自动数据收集和机器学习的智能模型,以预测柱色谱行为,提高纯化效率并减少经验性试错。
Xu, H.; Wu, W.; Chen, Y.; Zhang, D.; Mo, F. Explicit relation between thin-layer chromatography and column
徐,H.;吴,W.;陈,Y.;张,D.;莫,F. 薄层色谱与柱之间的明确关系
ACS Publications
美国化学会出版物
chromatography from statistics and machine learning. Nat. Commun. 2025, 16, 832. ${}^{3}$ This study derives explicit equations linking TLC Rf values to CC retention volumes using automated experiments and interpretable machine learning, providing a quantitative rationale for selecting chromatographic conditions.
来自统计学和机器学习的色谱法。《自然·通讯》,2025年,第16卷,第832页。${}^{3}$ 本研究通过自动化实验和可解释的机器学习得出了将薄层色谱Rf值与柱色谱保留体积联系起来的显式方程,为选择色谱条件提供了定量依据。
Lin, J.; Song, L.; Chen, Y.; Liu, C.; Chen, S.; Mo, F. Multimodal learning for gas chromatography retention prediction and isomer separation. Digit. Discov. 2025, 4, ${2465.}^{4}$ This work introduces a multimodal learning framework that integrates structural and temperature-program data to predict GC retention times and optimize isomer separations with high efficiency.
林,J;宋,L;陈,Y;刘,C;陈,S;莫,F。用于气相色谱保留预测和异构体分离的多模态学习。《数字发现》,2025年,第4卷,${2465.}^{4}$ 这项工作引入了一个多模态学习框架,该框架整合了结构和程序升温数据,以预测气相色谱保留时间并高效优化异构体分离。
Received: October 2, 2025
收到日期:2025年10月2日
Revised: November 24, 2025
修订日期:2025年11月24日
Accepted: December 2, 2025
接受日期:2025年12月2日
Published: December 22, 2025
发表日期:2025年12月22日
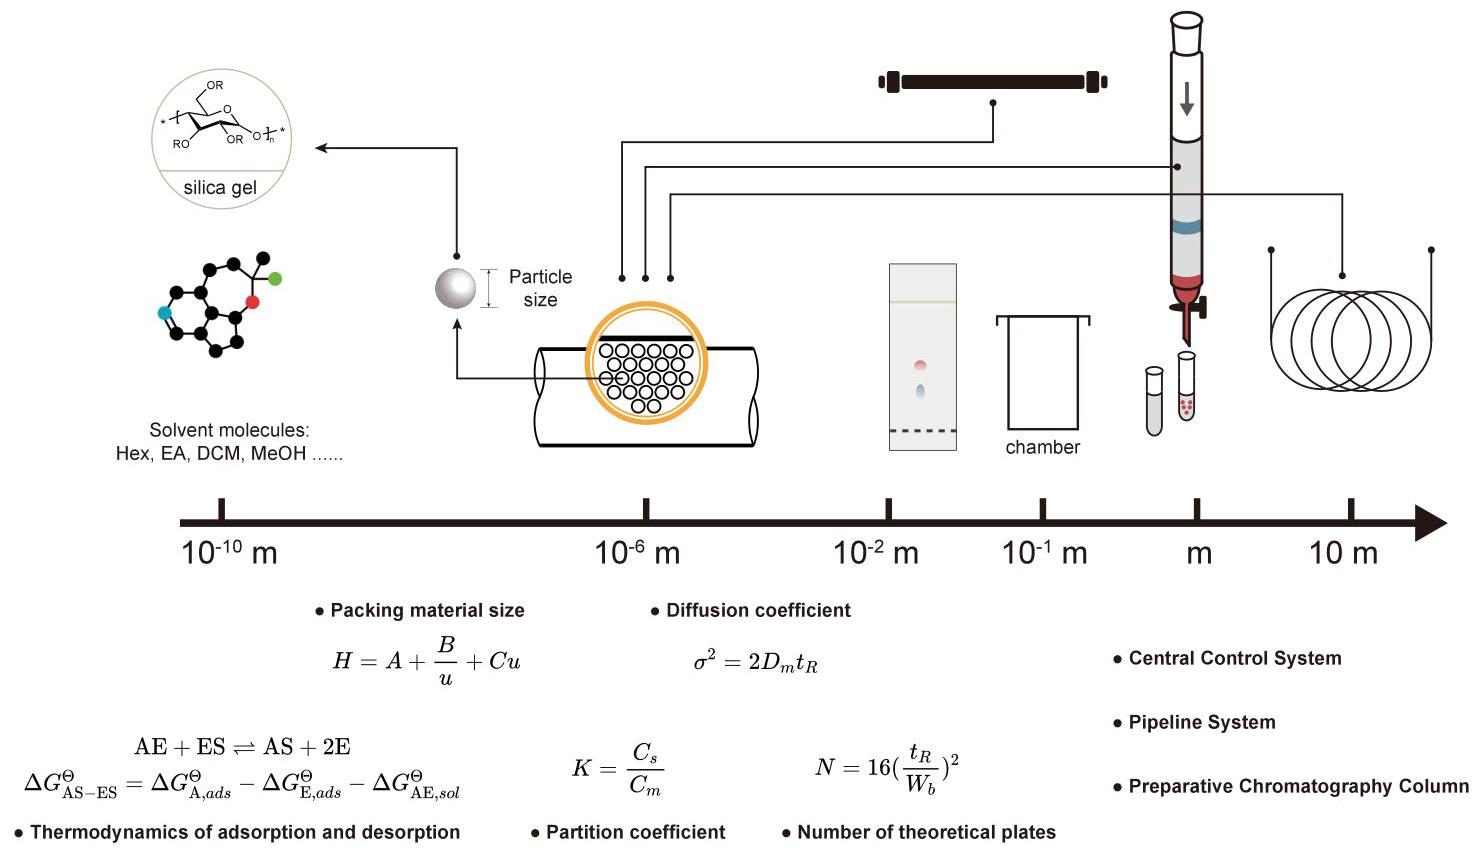
Figure 1. Cross-scale physical principles of chromatography. Processes span molecular thermodynamics, packing material diffusion, device-level transport, and system-scale operation, together shaping retention and resolution.
图1. 色谱的跨尺度物理原理。过程涵盖分子热力学、填充材料扩散、设备级传输和系统级操作,共同塑造保留和分离度。
Xu, H.; Lin, J.; Zhang, D.; Mo, F. Retention time prediction for chromatographic enantioseparation using quantile geometry-enhanced graph neural networks. Nat. Commun. 2023, 14, 3095. ${}^{5}$ This work presents a quantile geometry-enhanced graph neural network to predict enantioseparation retention times with uncertainty awareness, enabling machine-learning-guided optimization of chiral chromatography.
徐,H;林,J;张,D;莫,F。使用分位数几何增强图神经网络预测色谱对映体分离的保留时间。《自然·通讯》,2023年,第14卷,第3095页。${}^{5}$ 这项工作提出了一种分位数几何增强图神经网络,用于在具有不确定性意识的情况下预测对映体分离保留时间,实现机器学习指导的手性色谱优化。
1. INTRODUCTION
1. 引言
Chromatography has been indispensable to chemical research for more than a century, providing chemists with the means to analyze mixtures, purify products, and resolve complex stereochemical systems. ${}^{6 - {13}}$ Yet, method development remains one of its least systematic aspects. Condition selection-whether solvent ratios in thin-layer chromatography (TLC) and column chromatography (CC), heating programs in gas chromatography (GC), or stationary-phase choice in high-performance liquid chromatography (HPLC)-is still guided primarily by accumulated laboratory intuition. This reliance on empirical heuristics hampers reproducibility, slows discovery, and constrains knowledge transfer across laboratories. At a deeper level, chromatographic behavior arises from inherently multi-scale phenomena encompassing molecular interactions, transport processes, and device-level parameters, making rational prediction particularly challenging. As illustrated in Figure 1, these tightly coupled processes span molecular, mesoscale, device, and system levels, generating cross-scale dependencies that simple molecular or empirical models cannot fully capture. Building on these challenges, the strength of artificial intelligence (AI) lies in its ability to integrate heterogeneous information across scales; therefore, we explore data-driven and mechanistically guided models that hold promise for reconciling molecular, mesoscale, device, and system-level contributions to chromatographic retention.
一个多世纪以来,色谱法在化学研究中一直不可或缺,为化学家提供了分析混合物、纯化产物以及解析复杂立体化学体系的手段。${}^{6 - {13}}$ 然而,方法开发仍是其最缺乏系统性的方面之一。条件选择——无论是薄层色谱(TLC)和柱色谱(CC)中的溶剂比例、气相色谱(GC)中的加热程序,还是高效液相色谱(HPLC)中的固定相选择——仍然主要由积累的实验室经验指导。这种对经验启发法的依赖阻碍了可重复性,减缓了发现速度,并限制了跨实验室的知识转移。在更深层次上,色谱行为源于本质上的多尺度现象,包括分子相互作用、传输过程和设备级参数,这使得合理预测尤其具有挑战性。如图1所示,这些紧密耦合的过程跨越分子、介观尺度、设备和系统层面,产生了简单分子模型或经验模型无法完全捕捉的跨尺度依赖性。基于这些挑战,人工智能(AI)的优势在于其整合跨尺度异构信息的能力;因此,我们探索数据驱动和机理引导的模型,这些模型有望协调分子、介观尺度、设备和系统层面因素对色谱保留的贡献。
More broadly, the convergence of high-throughput automation, robotics, and machine learning is reshaping experimental chemistry. ${}^{{14} - {34}}$ Standardized data collection, algorithmic extraction of metadata, and model-driven planning are enabling closed-loop “self-driving” workflows that compress design-make-measure cycles. ${}^{{35} - {41}}$ Within this landscape, separation science is a natural next frontier for predictive and programmable methods.
更广泛地说,高通量自动化、机器人技术和机器学习的融合正在重塑实验化学。${}^{{14} - {34}}$ 标准化的数据收集、元数据的算法提取以及模型驱动的规划正在实现闭环“自动驾驶”工作流程,压缩设计-制造-测量周期。${}^{{35} - {41}}$ 在这种背景下,分离科学是预测性和可编程方法的自然下一个前沿领域。
Within this broader shift, chromatography can be reimagined as a predictive science. Robotic systems can execute experiments with reproducible precision, while machine-learning models provide quantitative links between molecular structure, experimental parameters, and retention outcomes. When designed with mechanistic awareness, such models do more than predict-they reveal interpretable connections between molecular properties and chromatographic behavior. ${}^{1 - 5}$
在这一更大的转变中,色谱法可以被重新想象为一门预测性科学。机器人系统可以以可重复的精度执行实验,而机器学习模型提供分子结构、实验参数和保留结果之间的定量联系。当设计时具有机理意识,这样的模型不仅仅是预测——它们揭示了分子性质和色谱行为之间可解释的联系。${}^{1 - 5}$
In this Account, we highlight our efforts to establish a unified framework for AI-assisted chromatography. We begin by describing how automation and algorithmic pipelines enable the construction of large, metadata-rich data sets across TLC, ${}^{1,{42}}$ CC, ${}^{2}\mathrm{{GC}},{}^{4}$ and HPLC. ${}^{5}\mathrm{{We}}$ then discuss strategies for feature engineering that embed polarity, size, and stereochemical descriptors, ensuring that models reflect the governing chemistry of separation. Building on this foundation, we examine algorithmic frameworks tailored to different chromatographic modes, from ensemble learners for polarity-driven systems to multimodal neural networks for programmed separations and chirality-aware graph models for enantiosepara-tion. Finally, we consider the challenges of connecting molecular-scale descriptors with device- and system-level variability, outlining how transfer learning and interpretable machine learning enable cross-scale generalization.
在本综述中,我们重点介绍了我们为建立人工智能辅助色谱法统一框架所做的努力。我们首先描述了自动化和算法管道如何能够构建跨越薄层色谱法(TLC)、${}^{1,{42}}$柱色谱法(CC)、${}^{2}\mathrm{{GC}},{}^{4}$和高效液相色谱法(HPLC)的大型、富含元数据的数据集。${}^{5}\mathrm{{We}}$然后讨论特征工程的策略,这些策略嵌入了极性、大小和立体化学描述符,确保模型反映分离的主导化学过程。在此基础上,我们研究了针对不同色谱模式量身定制的算法框架,从极性驱动系统的集成学习器到程序分离的多模态神经网络,以及对映体分离的手性感知图模型。最后,我们考虑了将分子尺度描述符与设备和系统级变异性联系起来的挑战,概述了迁移学习和可解释机器学习如何实现跨尺度泛化。
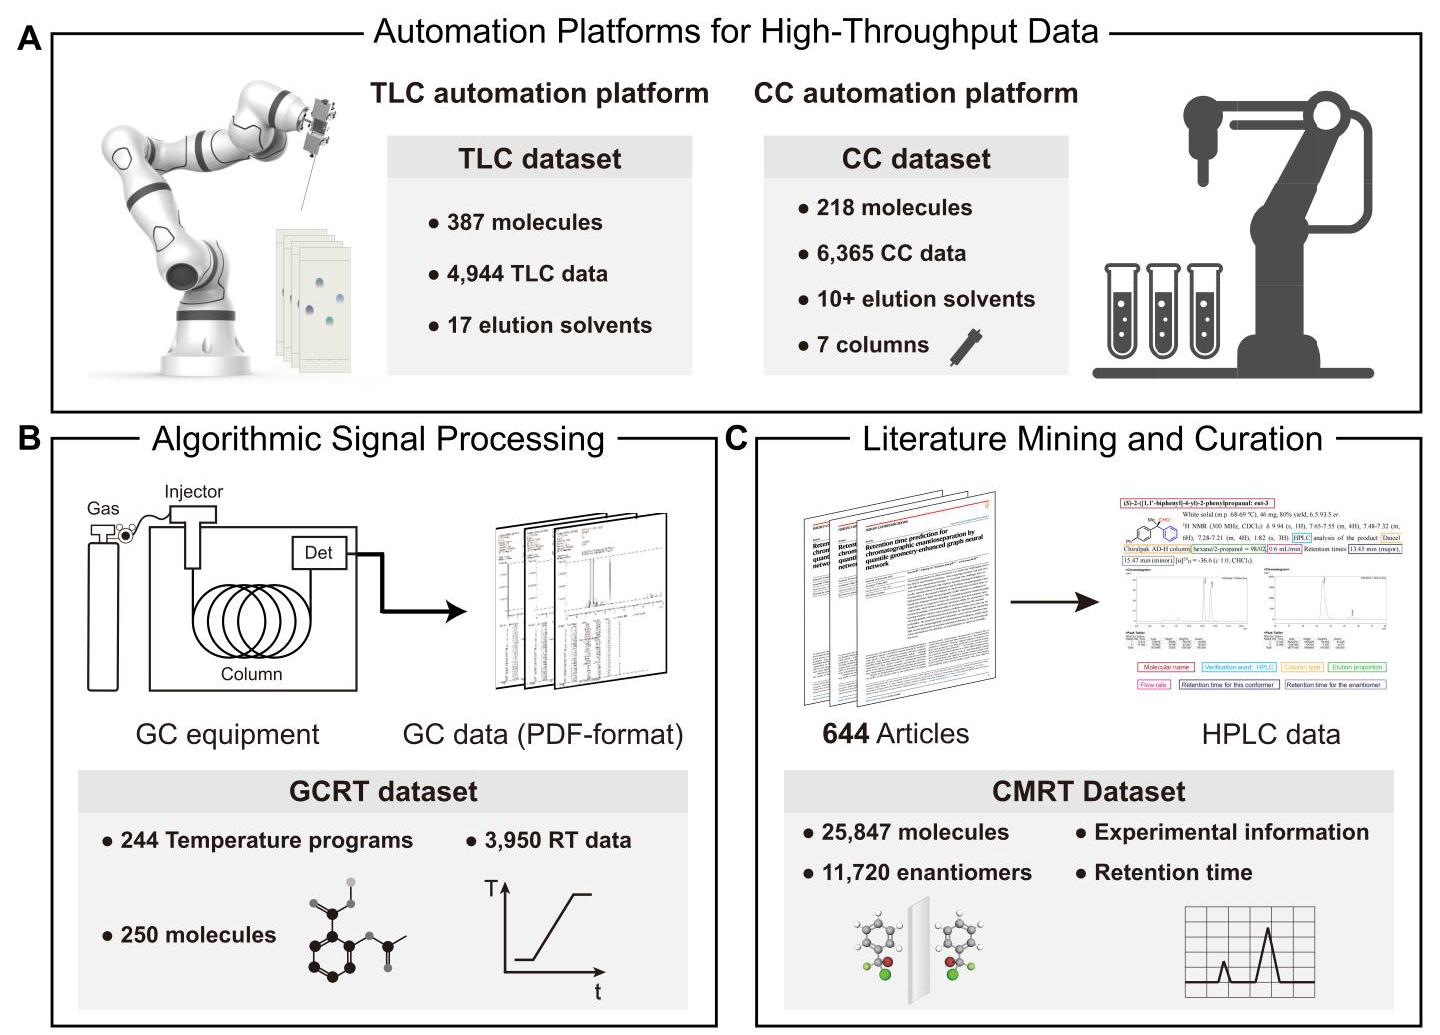
Figure 2. Data acquisition pipelines for chromatography. (A) Automation platforms for high-throughput TLC (left) and CC (right). (B) Algorithmic signal processing for GC. (C) Literature mining and curation for HPLC.
图2. 色谱法的数据采集管道。(A)高通量TLC(左)和CC(右)的自动化平台。(B)GC的算法信号处理。(C)HPLC的文献挖掘和整理。
Through this integration of standardized data generation, mechanistically informed modeling, and cross-scale transferability, we argue that chromatography can evolve from an empirical art into a predictive, programmable, and universally reproducible discipline.
通过这种标准化数据生成、机理知情建模和跨尺度可转移性的整合,我们认为色谱法可以从一门经验性技艺演变为一门预测性、可编程且普遍可重复的学科。
2. DATA ACQUISITION
2. 数据采集
Transforming chromatography from heuristic practice to predictive science hinges on large, standardized, and metadata-rich data sets. To this end, we employed four complementary strategies: (i) robotic automation for high-throughput experiments, (ii) algorithmic extraction of retention parameters from raw signals, (iii) literature mining and manual curation of legacy data, and (iv) systematic design of condition grids and compound coverage. Together, these methods ensure reproducibility, scalability, and transferability across chromatographic modalities.
将色谱法从启发式实践转变为预测性科学,关键在于大型、标准化且富含元数据的数据集。为此,我们采用了四种互补策略:(i) 用于高通量实验的机器人自动化,(ii) 从原始信号中算法提取保留参数,(iii) 文献挖掘和传统数据的人工整理,以及 (iv) 条件网格和化合物覆盖范围的系统设计。这些方法共同确保了跨色谱模式的可重复性、可扩展性和可转移性。
2.1. Automation Platforms for High-Throughput Data
2.1. 用于高通量数据的自动化平台
We developed dedicated robotic systems for TLC and CC, see Figure 2A. For TLC, a benchtop platform equipped with two collaborative robotic arms automates spotting, plate development, and UV imaging. This system produced 4,944 standardized ${R}_{f}$ values from 387 compounds under 17 solvent compositions. ${}^{1,{42}}$ For CC, an automated device integrating pumps, injector, detector, and controller executed injections, eluent mixing, and real-time signal capture. Across 7 column formats and 10+ eluent systems, we collected 6,365 runs from 218 compounds. ${}^{2}$ These robotic platforms transform TLC and CC from operator-dependent techniques into scalable data sources.
我们开发了用于薄层色谱(TLC)和柱色谱(CC)的专用机器人系统,见图2A。对于薄层色谱,一个配备两个协作机器人手臂的台式平台可自动进行点样、展开和紫外成像。该系统在17种溶剂组成下从387种化合物中产生了4944个标准化的${R}_{f}$值。${}^{1,{42}}$ 对于柱色谱,一个集成了泵、进样器、检测器和控制器的自动化设备可执行进样、洗脱液混合和实时信号捕获。在7种柱型和10多种洗脱液系统中,我们从218种化合物中收集了6365次运行数据。${}^{2}$ 这些机器人平台将薄层色谱和柱色谱从依赖操作人员的技术转变为可扩展的数据源。
2.2. Algorithmic Signal Processing
2.2. 算法信号处理
Gas chromatography (GC) posed a different challenge: chromatograms are typically embedded in vendor-specific PDF reports. We developed a Gas Chromatography Peak Information Extraction Algorithm to convert these files into structured tables. Parameters such as retention time, peak area, and height were parsed automatically, while temperature programs were discretized into time-series inputs. ${}^{4}$ This pipeline enabled the construction of the Gas Chromatography Retention Time (GCRT) data set containing 3,950 records for 250 compounds under 244 temperature programs (Figure 2B).
气相色谱(GC)带来了不同的挑战:色谱图通常嵌入在特定供应商的PDF报告中。我们开发了一种气相色谱峰信息提取算法,将这些文件转换为结构化表格。保留时间、峰面积和峰高等参数会自动解析,而温度程序则被离散化为时间序列输入。${}^{4}$ 此流程促成了气相色谱保留时间(GCRT)数据集的构建,该数据集包含在244个温度程序下250种化合物的3950条记录(图2B)。
2.3. Literature Mining and Curation
2.3. 文献挖掘与整理
For high-performance liquid chromatography (HPLC) enantio-separation, systematic experimentation is impractical due to the wide diversity of chiral stationary phases. Instead, we established the Chiral Molecule Retention Time (CMRT) data set by extracting retention times from published reports. ${}^{5}$ Records were standardized for column type, mobile phase composition, flow rate, and retention time, yielding a data set sufficiently broad to support predictive modeling of both retention and enantioseparation probability (Figure 2C). In addition, chemical structures were normalized and encoded as SMILES, ensuring consistent and machine-readable representations across all entries.
对于高效液相色谱 (HPLC) 对映体分离,由于手性固定相种类繁多,系统实验并不实际可行。相反,我们通过从已发表的报告中提取保留时间,建立了手性分子保留时间 (CMRT) 数据集。${}^{5}$ 记录针对柱类型、流动相组成、流速和保留时间进行了标准化,得到了一个足够广泛的数据集,以支持对保留和对映体分离概率的预测建模(图2C)。此外,化学结构被标准化并编码为SMILES,确保所有条目的表示一致且机器可读。
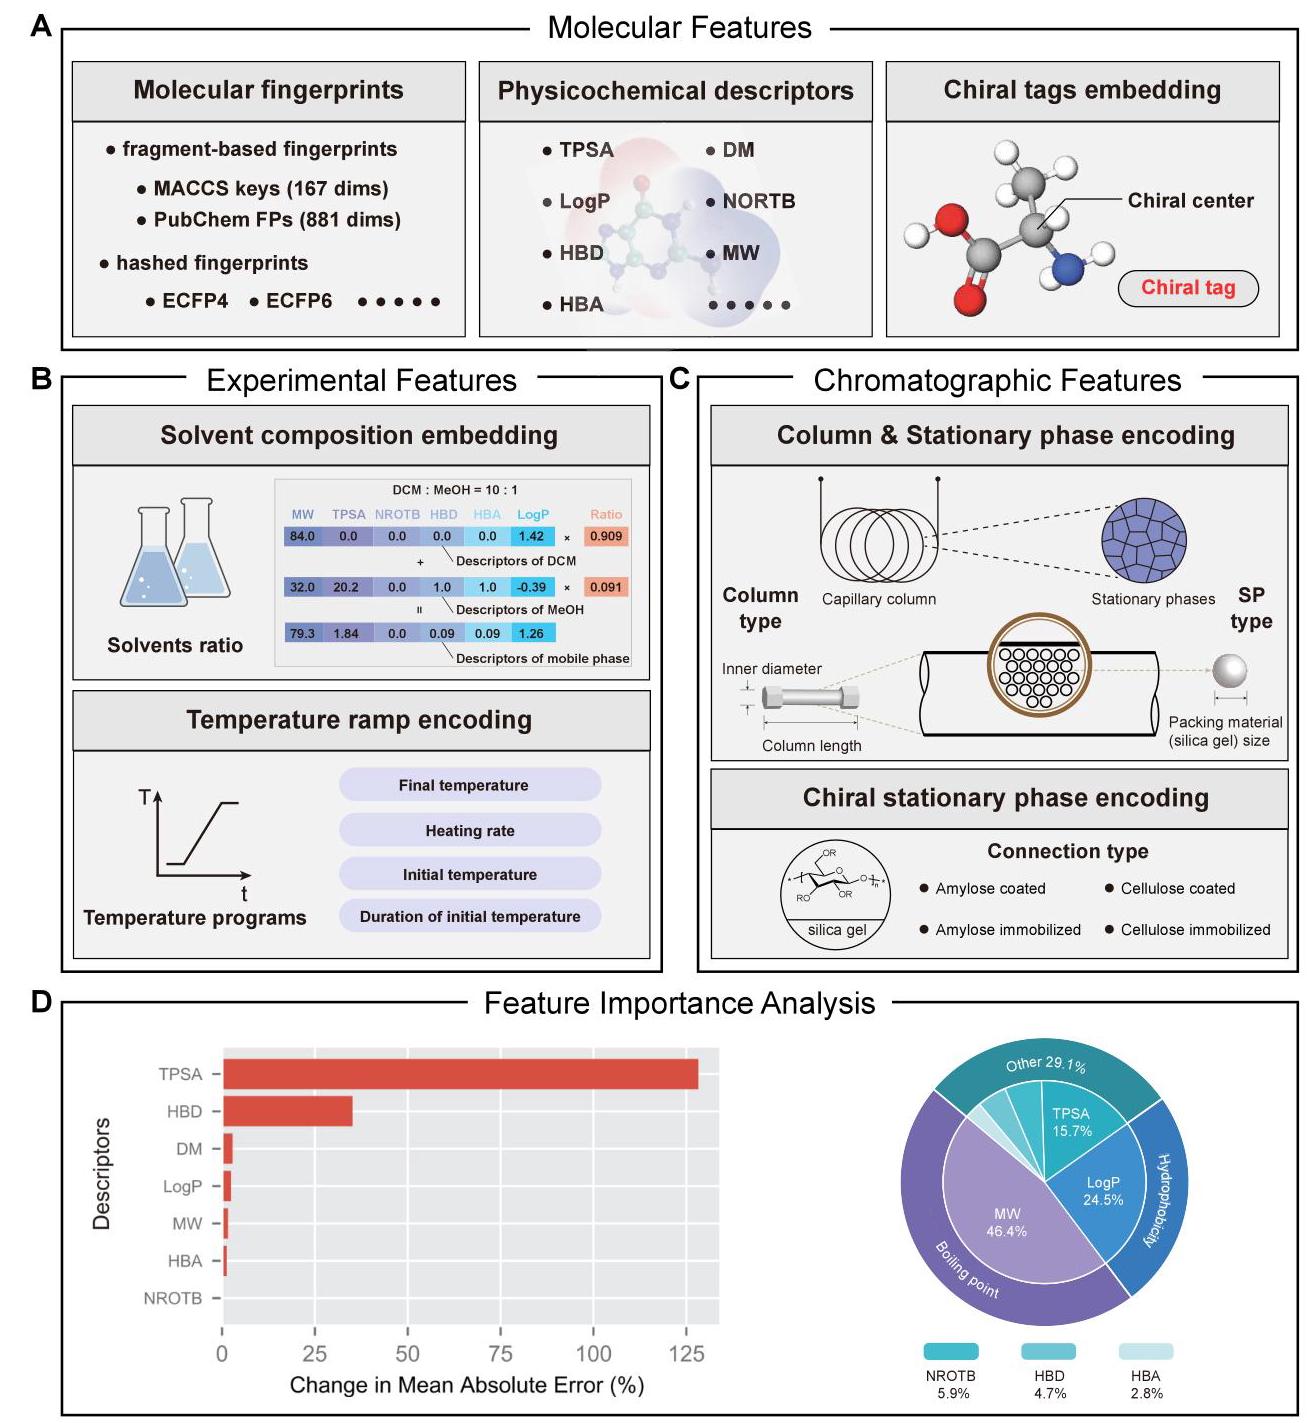
Figure 3. Feature engineering strategies and importance analysis for chromatographic prediction. (A) Molecular features: fragment-based fingerprints, physicochemical descriptors, and stereochemical annotations via chiral tags. (B) Experimental features: solvent composition embeddings derived from weighted solvent descriptors and temperature ramp encoding to capture heating programs. (C) Chromatographic features: column geometry and stationary-phase descriptors and chiral stationary phase encoding. (D) Feature importance analysis: ablation studies in TLC (left) and SHAP analysis in GC (right).
图3. 色谱预测的特征工程策略和重要性分析。(A) 分子特征:基于片段的指纹、物理化学描述符以及通过手性标签进行的立体化学注释。(B) 实验特征:从加权溶剂描述符导出的溶剂组成嵌入以及用于捕获升温程序的温度梯度编码。(C) 色谱特征:柱几何形状和固定相描述符以及手性固定相编码。(D) 特征重要性分析:TLC中的消融研究(左)和GC中的SHAP分析(右)。
2.4. Data Set Design Principles
2.4. 数据集设计原则
Across all modalities, data set construction adhered to common design rules:
在所有模式下,数据集构建均遵循通用设计规则:
Reproducibility: robotic control or algorithmic parsing minimizes operator variance and human bias.
可重复性:机器人控制或算法解析可最大程度减少操作员差异和人为偏差。
Rich metadata: solvent composition, flow conditions, temperature programs, and detector settings are consistently recorded to enable covariate-aware modeling.
丰富的元数据:始终记录溶剂组成、流动条件、温度程序和检测器设置,以实现协变量感知建模。
Coverage: condition grids (e.g., solvent ratios, loadings, temperature profiles) and compound-class diversity ensure robustness and enable transfer learning across chromatographic methods.
覆盖范围:条件网格(例如,溶剂比例、负载量、温度曲线)和化合物类别多样性可确保稳健性,并支持跨色谱方法的迁移学习。
3. FEATURE ENGINEERING STRATEGIES
3. 特征工程策略
Feature engineering in chromatography is not merely a technical step of descriptor selection but a way of embedding mechanistic priors about molecular interactions with stationary and mobile phases. The central aim is to design representations that balance general structural information with chemically meaningful drivers of retention, ensuring that predictive models remain interpretable as well as accurate. These features can be broadly grouped into three categories: molecular features, experimental features, and chromatographic features (Figure 3).
色谱中的特征工程不仅仅是描述符选择的技术步骤,而是一种将关于分子与固定相和流动相相互作用的机理先验知识嵌入其中的方式。其核心目标是设计出能在一般结构信息与具有化学意义的保留驱动因素之间取得平衡的表示形式,确保预测模型既准确又可解释。这些特征大致可分为三类:分子特征、实验特征和色谱特征(图3)。
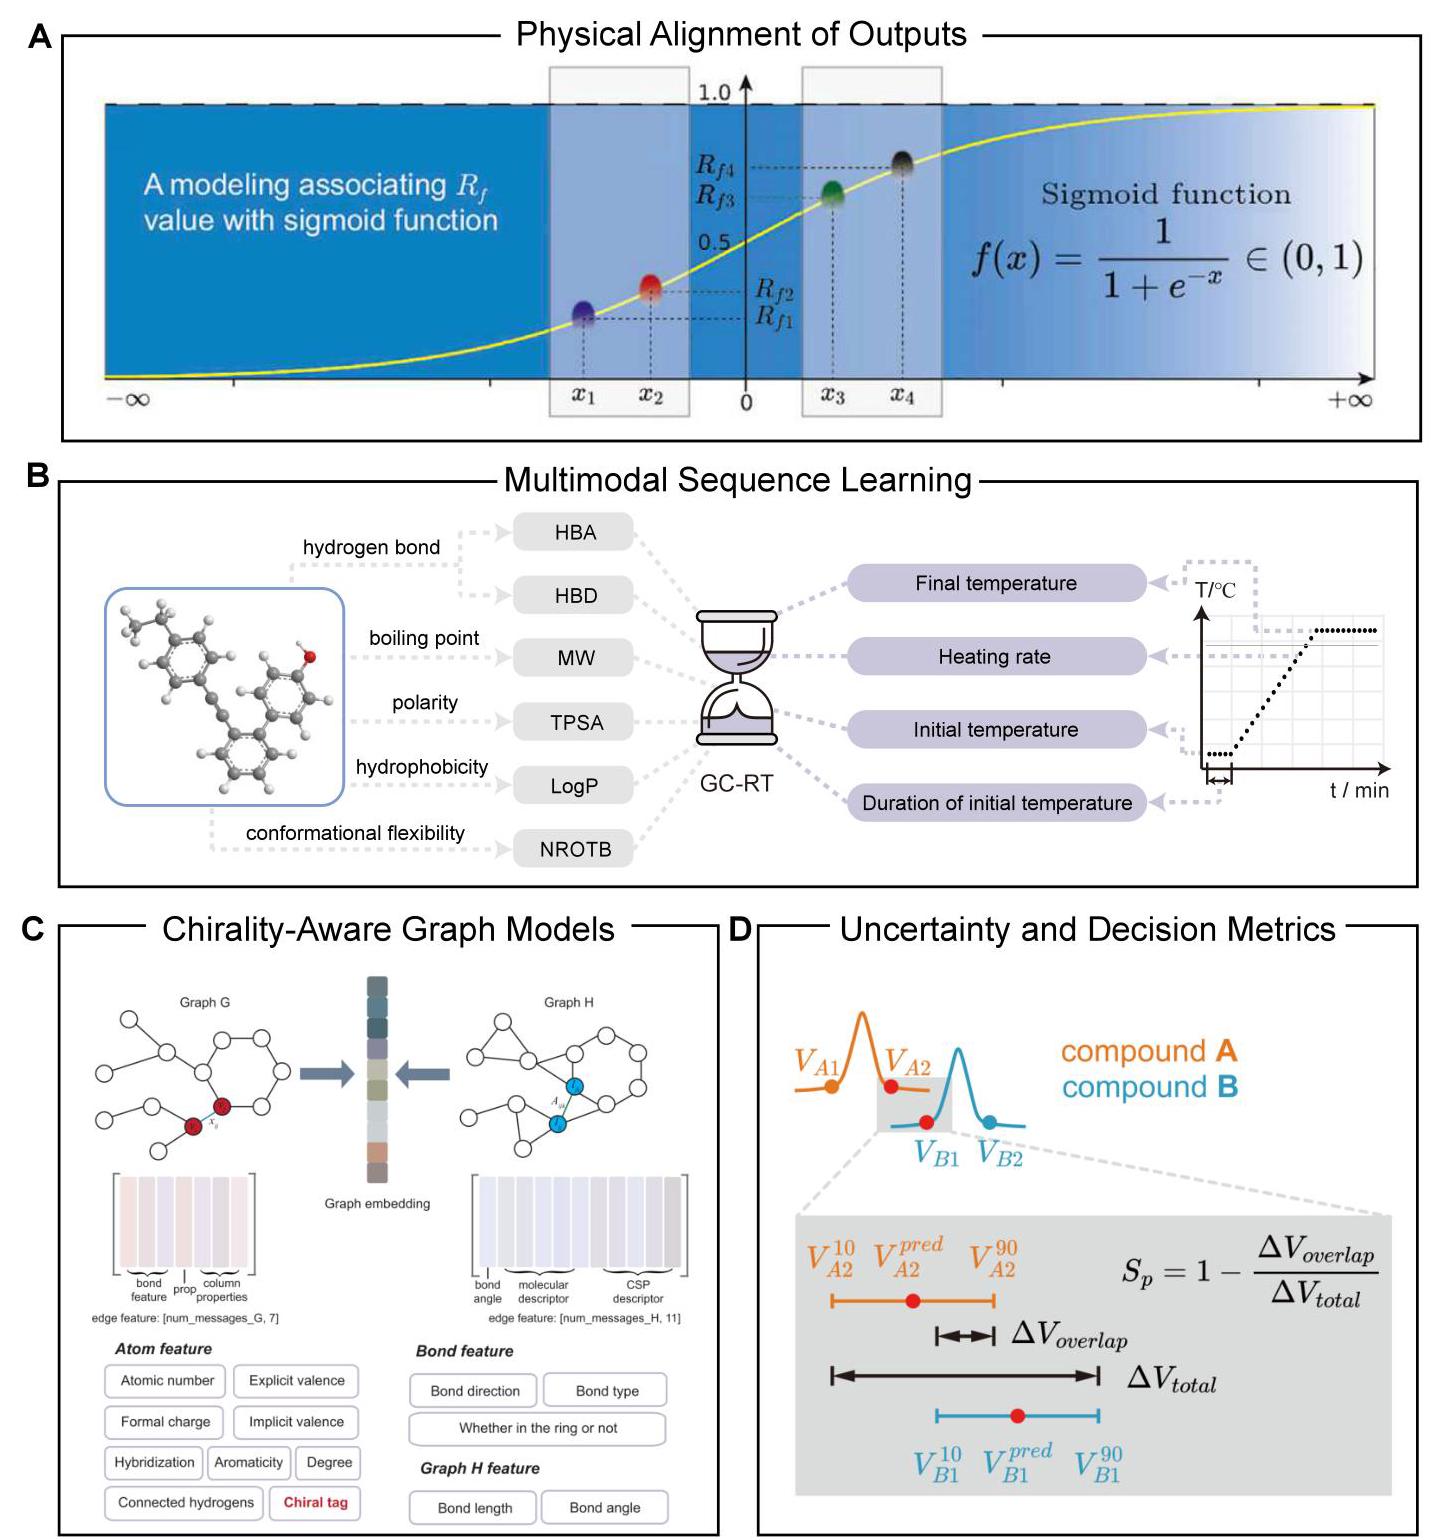
Figure 4. Algorithmic frameworks for chromatographic prediction. (A) Physical alignment of outputs: sigmoid mapping ensures ${R}_{f} \in \left( {0,1}\right)$ and encodes monotonicity constraints. (B) Multimodal sequence learning: GC retention modeled by combining molecular descriptors with heating-program sequences. (C) Chirality-aware graph models: enantioseparation prediction using stereochemical tags and CSP descriptors. (D) Uncertainty and decision metrics: quantile learning provides predictive intervals and defines the separation probability ${S}_{p}$ for robust decision-making.
图4. 色谱预测的算法框架。(A) 输出的物理对齐:Sigmoid映射确保${R}_{f} \in \left( {0,1}\right)$并编码单调性约束。(B) 多模态序列学习:通过将分子描述符与升温程序序列相结合来模拟气相色谱保留。(C) 手性感知图模型:使用立体化学标签和CSP描述符进行对映体分离预测。(D) 不确定性和决策指标:分位数学习提供预测区间并定义用于稳健决策的分离概率${S}_{p}$。
3.1. Molecular Features
3.1. 分子特征
Molecular features capture intrinsic properties of solutes that govern their interactions with chromatographic media (Figure 3A). Generic fingerprints such as MACCS keys or ECFP encode connectivity patterns, offering a fast but coarse representation. In contrast, physicochemical descriptors-molecular weight, topological polar surface area (TPSA), hydrogen-bond donor/ acceptor counts, dipole moment-directly quantify polarity, size, and hydrogen-bonding capacity. These descriptors correspond to key chromatographic behaviors: compounds with larger TPSA or stronger hydrogen-bonding ability interact more strongly with silica surfaces in TLC or CC, resulting in lower ${R}_{f}$ values or delayed elution. ${}^{1,2}$ For enantioseparation in HPLC, conventional descriptors collapse enantiomers into identical vectors, erasing the stereochemical differences that drive resolution. ${}^{5}$ To recover this information, stereocenter annotations, chiral tags, and geometry-aware graph embeddings are introduced. These explicitly preserve the asymmetric environments that govern chiral recognition, mirroring how experimentalists consider the configuration at stereocenters when predicting interactions with chiral stationary phases.
分子特征捕获溶质的内在性质,这些性质决定了它们与色谱介质的相互作用(图3A)。通用指纹,如MACCS键或ECFP,编码连接模式,提供快速但粗略的表示。相比之下,物理化学描述符——分子量、拓扑极性表面积(TPSA)、氢键供体/受体计数、偶极矩——直接量化极性、大小和氢键能力。这些描述符对应于关键的色谱行为:TPSA较大或氢键能力较强的化合物在TLC或CC中与硅胶表面的相互作用更强,导致${R}_{f}$值更低或洗脱延迟。${}^{1,2}$对于HPLC中的对映体分离,传统描述符将对映体合并为相同的向量,消除了驱动拆分的立体化学差异。${}^{5}$为了恢复这些信息,引入了立体中心注释、手性标签和几何感知图嵌入。这些明确保留了控制手性识别的不对称环境,反映了实验人员在预测与手性固定相的相互作用时如何考虑立体中心的构型。
3.2. Experimental Features
3.2. 实验特征
Experimental conditions define the external context in which separations occur (Figure 3B). For liquid-phase methods, solvent descriptors (e.g., dielectric constant, hydrogen-bonding ability, polarity index) are combined in proportion to solvent ratios to form embeddings that represent mobile phase composition. This allows models to capture molecule-solvent interactions in a data-driven manner rather than relying on heuristic polarity scales. For example, mixing dichloromethane (low polarity) and methanol (high polarity, hydrogen-bond donor) produces a mobile phase whose effective properties can be computed as a weighted combination of descriptors, reflecting how experimentalists rationalize solvent strength. In GC, the retention of analytes is influenced by both molecular properties and the applied temperature program. ${}^{4}$ Discretizing heating ramps into sequences of initial temperature, hold duration, heating rate, and final temperature allows sequence encoders to learn how volatility and boiling points interact with kinetic desorption processes. This mirrors the chemical intuition that small, volatile molecules elute early at low temperatures, while larger or more polar analytes require higher thermal energy to desorb from the stationary phase.
实验条件定义了分离发生的外部环境(图3B)。对于液相方法,溶剂描述符(例如介电常数、氢键能力、极性指数)按溶剂比例组合,以形成代表流动相组成的嵌入向量。这使得模型能够以数据驱动的方式捕捉分子与溶剂之间的相互作用,而不是依赖于启发式的极性标度。例如,将二氯甲烷(低极性)和甲醇(高极性,氢键供体)混合会产生一种流动相,其有效性质可以通过描述符的加权组合来计算,这反映了实验人员如何解释溶剂强度。在气相色谱中,分析物的保留受到分子性质和所应用的温度程序的影响。${}^{4}$ 将升温梯度离散为初始温度、保持时间、升温速率和最终温度的序列,使序列编码器能够了解挥发性和沸点如何与动力学解吸过程相互作用。这反映了化学直觉,即小的挥发性分子在低温下较早洗脱,而较大或极性更强的分析物需要更高的热能才能从固定相上解吸。
3.3. Chromatographic Features
3.3. 色谱特征
Chromatographic features describe the properties of columns and stationary phases that directly shape retention and resolution (Figure 3C). In GC, stationary phase polarity, film thickness, and capillary dimensions (inner diameter, length) govern analyte-phase interactions and diffusion paths, thereby determining selectivity and efficiency. ${}^{4}$ In HPLC, descriptors of particle size, pore diameter, and stationary-phase chemistry encode how mass transfer and surface chemistry affect separation performance. ${}^{5}$ For chiral stationary phases (CSPs), encoding whether polysaccharides are coated or immobilized, and whether amylose or cellulose is used, reflects critical chemical determinants of enantioselectivity. Such descriptors capture the fact that immobilized CSPs often provide greater robustness but different selectivity compared to coated variants. Embedding these chromatographic descriptors ensures that models remain portable across laboratories, instruments, and column designs, reflecting the experimental practice of transferring methods by matching stationary-phase and column specifications.
色谱特征描述了直接影响保留和分离度的色谱柱和固定相的性质(图3C)。在气相色谱中,固定相极性、膜厚和毛细管尺寸(内径、长度)决定了分析物与固定相之间的相互作用以及扩散路径,从而决定了选择性和分离效率。${}^{4}$ 在高效液相色谱中,粒径、孔径和固定相化学性质的描述符编码了传质和表面化学如何影响分离性能。${}^{5}$ 对于手性固定相(CSP),编码多糖是被涂覆还是被固定,以及使用的是直链淀粉还是纤维素,反映了对映体选择性的关键化学决定因素。这些描述符体现了这样一个事实,即与涂覆型变体相比,固定化CSP通常具有更高的稳定性,但选择性不同。嵌入这些色谱描述符可确保模型在不同实验室、仪器和色谱柱设计之间保持通用性,这反映了通过匹配固定相和色谱柱规格来转移方法的实验实践。
3.4. Qualitative Insights
3.4. 定性见解
Feature attribution analyses consistently recover chemically intuitive drivers of retention (Figure 3D). In TLC, TPSA and HBD/HBA dominate, reflecting adsorption on silica Si-OH sites: stronger polarity lowers $\Delta {G}_{\text{ ads }}$ , raises the distribution coefficient $K = {C}_{s}/{C}_{m}$ , and through ${R}_{f} \approx 1/\left( {1 + k}\right)$ decreases ${R}_{f}$ . Protic eluents disrupt these interactions, explaining shifts toward higher ${R}_{f}$ at fixed polarity. In GC, retention is governed mainly by molecular weight and hydrophobicity. Heavier analytes, with higher vaporization enthalpies, and hydrophobic ones, dissolving more readily in polysiloxane films, show longer residence times; modeling heating ramps as sequences captures the $T\left( t\right)$ - dependent modulation of these effects. For HPLC enantiosepa-ration, predictive power hinges on explicit stereochemical encoding: resolution arises from small free-energy differences $\left( {\Delta \Delta G}\right)$ in solute-CSP complexes, mediated by directional H-bonding, $\pi - \pi$ stacking, and steric fit near stereocenters. Together, these patterns mirror established mechanistic expectations-polarity-driven adsorption for TLC, volatility and phase affinity for GC, and stereochemical recognition for HPLC-showing that machine-learning models can compress heterogeneous data into quantitative, interpretable structure-condition-retention relationships.
特征归因分析始终能找出符合化学直觉的保留驱动因素(图3D)。在薄层色谱中,总极表面积(TPSA)和氢键供体/受体数量(HBD/HBA)起主导作用,反映了在硅胶Si-OH位点上的吸附:更强的极性会降低$\Delta {G}_{\text{ ads }}$,提高分配系数$K = {C}_{s}/{C}_{m}$,并通过${R}_{f} \approx 1/\left( {1 + k}\right)$降低${R}_{f}$。质子性洗脱剂会破坏这些相互作用,这解释了在固定极性下向更高${R}_{f}$的转变。在气相色谱中,保留主要由分子量和疏水性决定。较重的分析物,具有更高的汽化焓,以及疏水性分析物,更容易溶解在聚硅氧烷薄膜中,显示出更长的保留时间;将升温程序建模为序列可以捕捉这些效应的$T\left( t\right)$依赖性调制。对于高效液相色谱手性分离,预测能力取决于明确的立体化学编码:分离度源于溶质 - 手性固定相(CSP)复合物中的小自由能差异$\left( {\Delta \Delta G}\right)$,由定向氢键、$\pi - \pi$堆积以及立体中心附近的空间适配介导。总之,这些模式反映了既定的机理预期——薄层色谱中极性驱动的吸附、气相色谱中挥发性和相亲和力以及高效液相色谱中的立体化学识别——表明机器学习模型可以将异构数据压缩为定量的、可解释的结构 - 条件 - 保留关系。
4. ALGORITHMIC FRAMEWORKS
4. 算法框架
The design of chromatographic prediction models must balance numerical accuracy, physical validity, and chemical interpretability. Guided by these principles, we organize algorithmic strategies into four complementary layers (Figure 4).
色谱预测模型的设计必须在数值准确性、物理有效性和化学可解释性之间取得平衡。在这些原则的指导下,我们将算法策略组织成四个互补的层次(图4)。
4.1. Physical Alignment of Outputs
4.1. 输出的物理对齐
Chromatographic targets must respect their intrinsic domains. For thin-layer chromatography, ${R}_{f}$ values are bounded between 0 and 1; this constraint can be enforced through a sigmoid activation that naturally maps regression outputs into the valid interval (Figure 4A). Chemically, this reflects the fact that solute mobility on silica cannot exceed the solvent front and cannot be negative. By introducing a sigmoid mapping, the model formalizes the bounded diffusion-adsorption equilibrium that governs ${R}_{f}$ values. ${}^{1}$ For column chromatography, monotonicity with solvent polarity and adsorption strength is encoded to avoid unphysical extrapolation. This mirrors the chemical intuition that stronger hydrogen-bond donors or larger polar surface areas consistently slow elution under polar stationary phases. Embedding these constraints thus prevents the model from predicting inversions that contradict known chromatographic mechanisms.
色谱目标必须符合其固有范围。对于薄层色谱,${R}_{f}$值介于0和1之间;可以通过sigmoid激活来强制执行此约束,该激活自然地将回归输出映射到有效区间(图4A)。从化学角度来看,这反映了溶质在硅胶上的迁移率不能超过溶剂前沿且不能为负的事实。通过引入sigmoid映射,模型将控制${R}_{f}$值的有界扩散-吸附平衡形式化。${}^{1}$对于柱色谱,编码了与溶剂极性和吸附强度的单调性,以避免非物理外推。这反映了化学直觉,即更强的氢键供体或更大的极性表面积在极性固定相下会持续减慢洗脱速度。因此,嵌入这些约束可防止模型预测与已知色谱机制相矛盾颠倒情况。
4.2. Multimodal Sequence Learning
4.2. 多模态序列学习
Gas chromatography retention depends jointly on intrinsic molecular descriptors (e.g., polarity, hydrophobicity, boiling point, conformational flexibility) and external heating programs. To capture this interplay, multimodal architectures combine graph-based encoders of molecular structure with recurrent or attention-based encoders of temporal sequences such as initial temperature, heating rate, and final temperature (Figure 4B). From a chemical perspective, retention in GC reflects vapor-liquid partitioning equilibria that evolve dynamically with temperature. ${}^{4}$ Small, volatile molecules desorb rapidly, whereas larger or more polar compounds require higher energy to elute. By embedding heating ramps as temporal sequences, the model learns how volatility profiles interact with kinetic desorption, an effect that classical descriptors alone cannot capture. This mechanistic encoding allows predictions to generalize across nonlinear heating gradients and provides a transferable framework for temperature-programmed separations.
气相色谱保留同时取决于内在分子描述符(例如极性、疏水性、沸点、构象灵活性)和外部加热程序。为了捕捉这种相互作用,多模态架构将基于图的分子结构编码器与基于循环或注意力的时间序列编码器(如初始温度、升温速率和最终温度)相结合(图4B)。从化学角度来看,气相色谱中的保留反映了气液分配平衡,该平衡随温度动态变化。${}^{4}$ 小的挥发性分子快速解吸,而较大或极性更强的化合物需要更高的能量才能洗脱。通过将加热梯度嵌入为时间序列,该模型了解挥发性分布如何与动力学解吸相互作用,这是仅靠经典描述符无法捕捉的效应。这种机理编码使预测能够推广到非线性加热梯度,并为程序升温分离提供了一个可转移的框架。
4.3. Chirality-Aware Graph Models
4.3. 手性感知图模型
High-performance liquid chromatography for enantioseparation poses the challenge of distinguishing constitutionally identical enantiomers. Chirality-aware graph neural networks explicitly tag stereocenters and encode local three-dimensional environments (Figure 4C). This reflects the chemical reality that enantiomer separation arises from asymmetric interactions between solutes and the chiral stationary phase (CSP). ${}^{5}$ Hydrogen bonding, stacking, and steric fit differ subtly between mirror-image configurations, and these differences are often localized near stereogenic centers. By encoding stereocenters and CSP descriptors into the model, the framework captures the same interaction motifs that experimentalists exploit when screening columns. Thus, the algorithm does not merely predict retention but also highlights which stereochemical environments are most influential for enantioselectivity.
用于对映体分离的高效液相色谱面临着区分结构相同的对映体的挑战。手性感知图神经网络明确标记立体中心并编码局部三维环境(图4C)。这反映了化学现实,即对映体分离源于溶质与手性固定相(CSP)之间的不对称相互作用。${}^{5}$ 氢键、堆积和空间适配在镜像构型之间存在细微差异,这些差异通常位于立体中心附近。通过将立体中心和CSP描述符编码到模型中,该框架捕捉到了实验人员在筛选色谱柱时所利用的相同相互作用模式。因此,该算法不仅预测保留时间,还突出显示哪些立体化学环境对对映选择性最有影响。
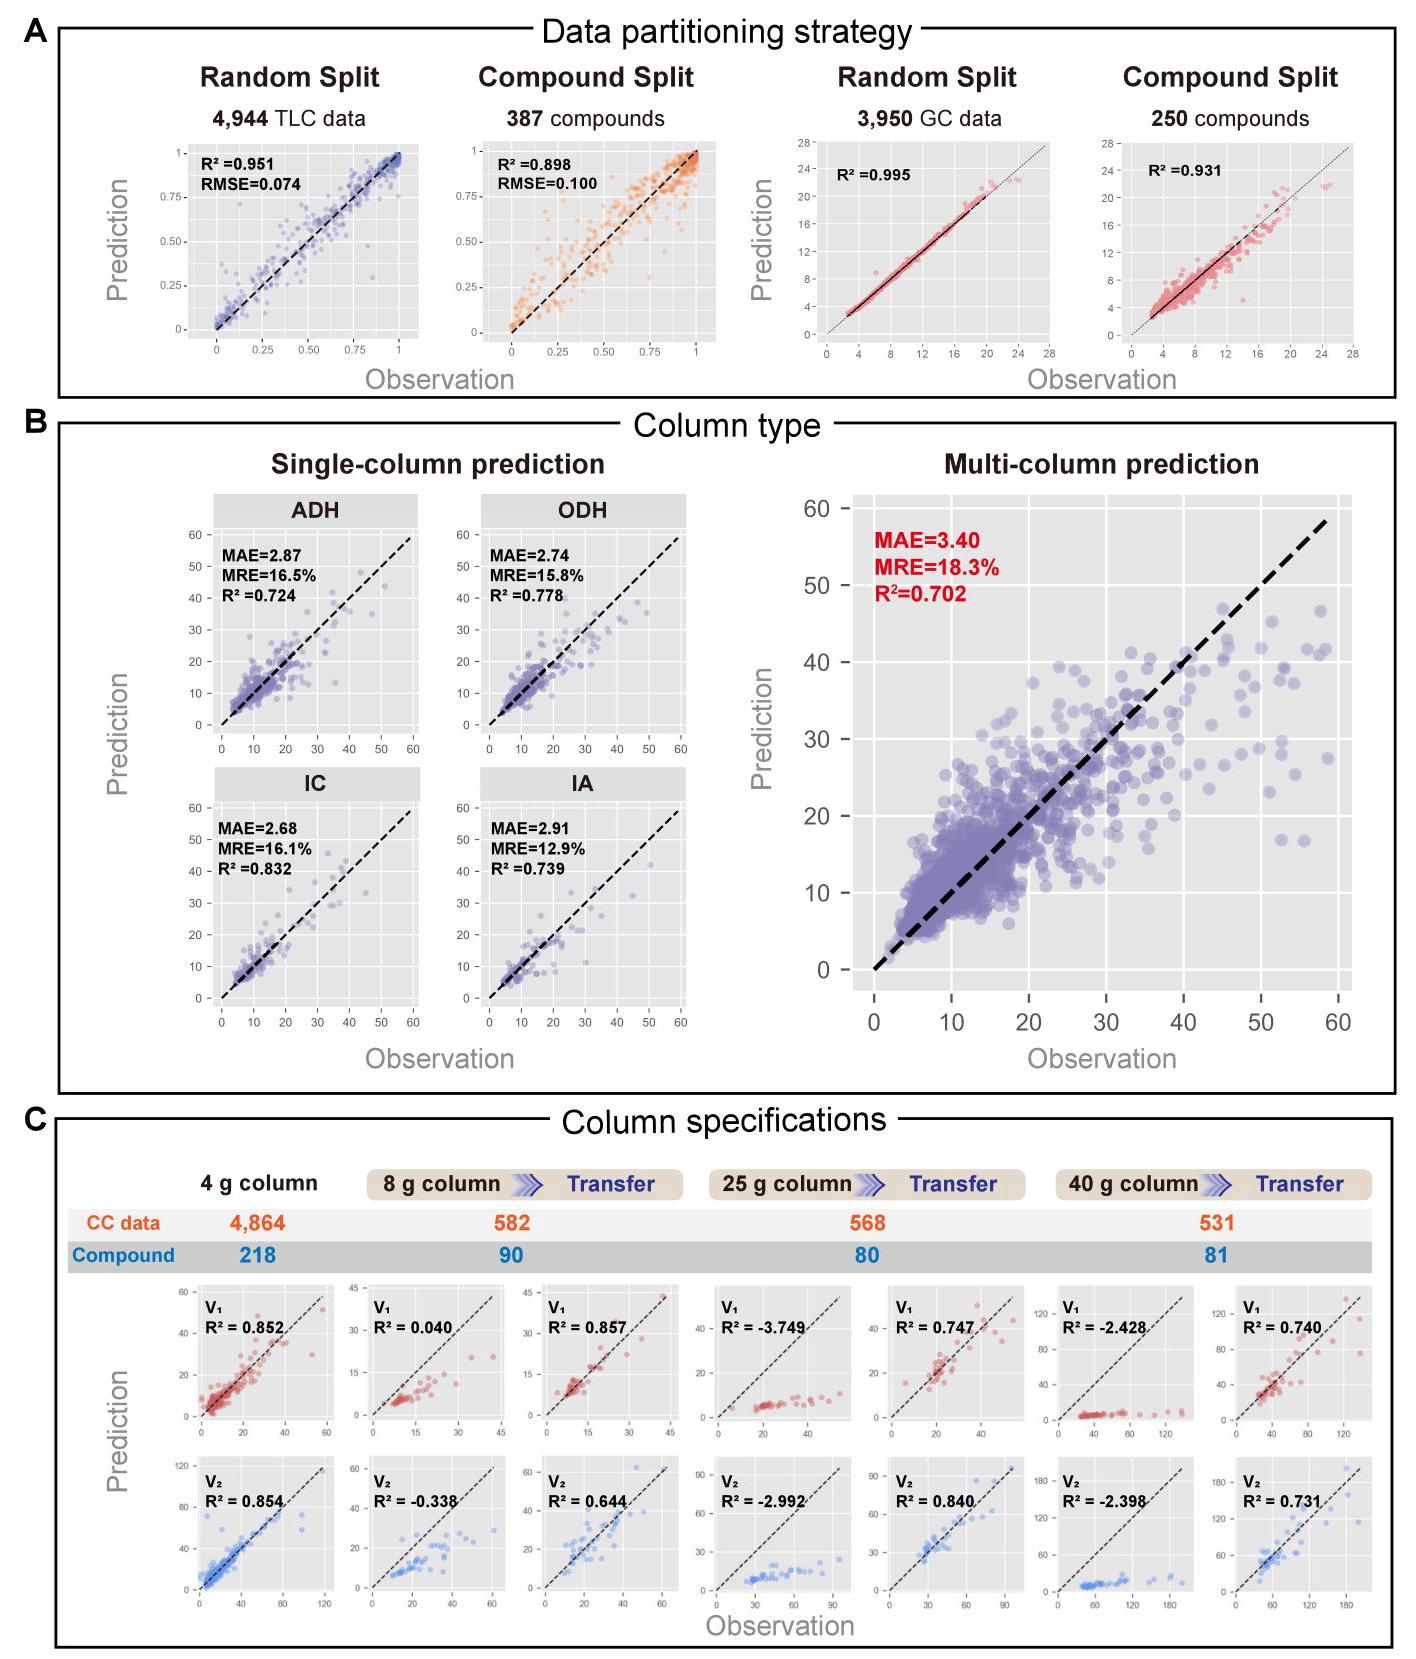
Figure 5. Model performance and generalization across chromatographic settings. (A) Data partitioning: evaluation under random and compound-level splits. (B) Column type: assessment of HPLC enantioseparation across different chiral stationary phases. (C) Column specifications: assessment of CC performance across cartridges of different sizes with transfer learning.
图5. 模型在不同色谱设置下的性能和泛化能力。(A) 数据划分:在随机和化合物级拆分下的评估。(B) 色谱柱类型:评估不同手性固定相上的HPLC对映体分离。(C) 色谱柱规格:通过迁移学习评估不同尺寸柱芯上的CC性能。
4.4. Uncertainty and Decision Metrics
4.4. 不确定性与决策指标
Accurate prediction alone is insufficient for experimental decision-making when separations hinge on narrow thresholds (e.g., $\Delta {t}_{R} \sim {0.3}\mathrm{\;{min}}$ ). We therefore use quantile learning to produce distributional predictions and convert them into a single, chemically interpretable metric: the separation probability ${S}_{p}$ (Figure 4D). ${}^{2}$
当分离取决于狭窄的阈值(例如,$\Delta {t}_{R} \sim {0.3}\mathrm{\;{min}}$)时,仅靠准确的预测对于实验决策是不够的。因此,我们使用分位数学习来生成分布预测,并将其转换为一个单一的、具有化学可解释性的指标:分离概率${S}_{p}$(图4D)。${}^{2}$
Assuming compound A elutes before B (so that ${V}_{2}$ of A precedes ${V}_{1}$ of B), let ${V}_{\mathrm{A}2}^{90}$ denote the 90th percentile of the end elution volume of $\mathrm{A}$ and ${V}_{\mathrm{B}1}^{10}$ the 10th percentile of the start elution volume of $\mathrm{B}$ ; likewise define ${V}_{\mathrm{A}2}^{10}$ and ${V}_{\mathrm{B}1}^{90}$ . We then quantify the overlap between A’s late tail and B’s early front and normalize it by the uncertainty span between A’s early tail and B’s late front:
假设化合物A在B之前洗脱(即${V}_{2}$的A先于${V}_{1}$的B),令${V}_{\mathrm{A}2}^{90}$表示$\mathrm{A}$最终洗脱体积的第90百分位数,${V}_{\mathrm{B}1}^{10}$表示$\mathrm{B}$起始洗脱体积的第10百分位数;同样地定义${V}_{\mathrm{A}2}^{10}$和${V}_{\mathrm{B}1}^{90}$。然后,我们量化A的晚期尾部与B的早期前沿之间的重叠,并通过A的早期尾部与B的晚期前沿之间的不确定性跨度对其进行归一化:
$$ {S}_{p} = 1 - \frac{\max \left( {0,{V}_{\mathrm{A}2}^{90} - {V}_{\mathrm{B}1}^{10}}\right) }{{V}_{\mathrm{B}1}^{90} - {V}_{\mathrm{A}2}^{10}} \tag{1} $$Here ${S}_{p} = 1$ when ${V}_{\mathrm{A}2}^{90} \leq {V}_{\mathrm{B}1}^{10}$ (no overlap), and ${S}_{p}$ decreases toward 0 as the overlap grows within the span $\left\lbrack {{V}_{\mathrm{A}2}^{10},{V}_{\mathrm{B}1}^{90}}\right\rbrack$ . For the reverse elution order, swap the roles of $\mathrm{A}$ and $\mathrm{B}$ (notation: ${V}_{1}/{V}_{2}$ correspond to start/end elution volumes, i.e., ${V}_{\mathrm{S}}/{V}_{\mathrm{E}}$ ).
当${V}_{\mathrm{A}2}^{90} \leq {V}_{\mathrm{B}1}^{10}$时,此处${S}_{p} = 1$(无重叠),并且随着重叠在$\left\lbrack {{V}_{\mathrm{A}2}^{10},{V}_{\mathrm{B}1}^{90}}\right\rbrack$范围内增加,${S}_{p}$向0减小。对于相反的洗脱顺序,交换$\mathrm{A}$和$\mathrm{B}$的角色(符号:${V}_{1}/{V}_{2}$对应于起始/最终洗脱体积,即${V}_{\mathrm{S}}/{V}_{\mathrm{E}}$)。
The choice of the 10th/90th percentiles is not arbitrary. Intervals such as the 25th/75th percentiles are too narrow to reflect real chromatographic variability, whereas the 5th/95th percentiles are overly influenced by outliers. The 10th/90th interval provides a practical balance: it captures the dominant experimental uncertainty while excluding extreme predictions, and it aligns with how practitioners evaluate retention windows in routine CC/HPLC operation.
第10/90百分位数的选择并非随意。诸如第25/75百分位数这样的区间太窄以至于无法反映实际的色谱变异性,而第5/95百分位数则受到异常值的过度影响。第10/90区间提供了一种实际的平衡:它捕获了主要的实验不确定性,同时排除了极端预测,并且它与从业者在常规CC/HPLC操作中评估保留窗口的方式一致。
This quantile-overlap rule is distribution-free, aligns with chromatographic intuition (larger mean gap and narrower predictive intervals increase ${S}_{p}$ ), and turns predictive uncertainty into an actionable decision for solvent choice in CC or column-solvent selection in HPLC.
这种分位数重叠规则是无分布的,符合色谱直觉(平均差距越大且预测区间越窄,${S}_{p}$越大),并将预测不确定性转化为CC中溶剂选择或HPLC中柱 - 溶剂选择的可操作决策。
5. MODEL PERFORMANCE AND GENERALIZATION
5. 模型性能与泛化能力
The predictive performance of chromatographic models is governed less by data set size than by the extent to which underlying physicochemical mechanisms are appropriately embedded. To evaluate model robustness, we systematically examined three representative dimensions: data partitioning strategy, column type, and column specifications (Figure 5).
色谱模型的预测性能更多地取决于潜在物理化学机制的适当嵌入程度,而非数据集大小。为评估模型稳健性,我们系统地考察了三个具有代表性的维度:数据划分策略、色谱柱类型和色谱柱规格(图5)。
5.1. Data Partitioning Strategy
5.1. 数据划分策略
Data partitioning provides a direct measure of extrapolative capability. For TLC, ensemble learners trained on 4,944 records achieved ${R}^{2} = {0.951}$ under random splits and ${R}^{2} = {0.898}$ under compound-level splits (Figure 5A, left). ${}^{1}$ The modest decline reflects the chemical generality of descriptors such as TPSA and HBD, which encode adsorption tendencies on silica. Molecules with larger polar surface areas or stronger hydrogen-bond donating ability consistently exhibit lower ${R}_{f}$ values, enabling generalization to previously unseen compounds. In GC, multimodal models trained on 3,950 runs attained ${R}^{2} = {0.995}$ under random splits and retained ${R}^{2} = {0.931}$ under compound-level splits (Figure 5A, right). ${}^{4}$ This stability arises from the dominant role of volatility (molecular weight, boiling point) and hydrophobic interactions with the stationary phase, coupled with explicit encoding of heating ramps. By representing temperature programs as temporal sequences, the models capture vapor-liquid partition dynamics, yielding robust extrapolation to novel analytes.
数据划分提供了一种直接衡量外推能力的方法。对于薄层色谱(TLC),在4944条记录上训练的集成学习器在随机划分下达到了${R}^{2} = {0.951}$,在化合物级划分下达到了${R}^{2} = {0.898}$(图5A,左)。${}^{1}$ 这种适度下降反映了诸如拓扑极性表面积(TPSA)和氢键供体数(HBD)等描述符的化学通用性,这些描述符编码了在硅胶上的吸附倾向。具有较大极性表面积或较强氢键供体能力的分子始终表现出较低的${R}_{f}$值,从而能够推广到以前未见过的化合物。在气相色谱(GC)中,在3950次运行上训练的多峰模型在随机划分下达到了${R}^{2} = {0.995}$,在化合物级划分下保持了${R}^{2} = {0.931}$(图5A,右)。${}^{4}$ 这种稳定性源于挥发性(分子量、沸点)和与固定相的疏水相互作用的主导作用,以及加热梯度的显式编码。通过将温度程序表示为时间序列,模型捕获了气液分配动态,从而能够对新型分析物进行稳健的外推。
5.2. Column Type: Chiral Stationary Phases
5.2. 色谱柱类型:手性固定相
Enantioseparation in HPLC presents a more stringent challenge, as enantiomers are constitutionally identical and separation depends on asymmetric interactions with the chiral stationary phase (CSP). When trained on individual CSPs (ADH, ODH, IC, IA), QGeoGNNs achieved ${R}^{2} = {0.724} - {0.832}$ with mean absolute errors of 2.7-2.9 min (Figure 5B, left), indicating that stereochemical recognition-mediated by directional hydrogen bonding, $\pi - \pi$ stacking, and steric complementarity-can be reliably encoded within a fixed CSP environment. ${}^{5}$ In contrast, pooling multiple CSPs reduced performance to ${R}^{2} = {0.702}$ with MAE = 3.40 min and MRE = 18.3% (Figure 5B, right). This decline is chemically meaningful: amylose- and cellulose-derived CSPs differ in helical chirality and hydrogen-bond topology, while coated versus immobilized phases exhibit distinct conformational rigidity. Without explicit descriptors of CSP chemistry, the model conflates distinct recognition mechanisms, underscoring the necessity of condition-aware encoding or targeted transfer learning for cross-column generalization.
高效液相色谱中的对映体分离面临更严峻的挑战,因为对映体在结构上是相同的,分离取决于与手性固定相(CSP)的不对称相互作用。当在单个CSP(ADH、ODH、IC、IA)上进行训练时,QGeoGNNs实现了${R}^{2} = {0.724} - {0.832}$,平均绝对误差为2.7 - 2.9分钟(图5B,左),这表明由定向氢键、$\pi - \pi$堆积和空间互补性介导的立体化学识别可以在固定的CSP环境中可靠地编码。${}^{5}$ 相比之下,汇集多个CSP会将性能降低到${R}^{2} = {0.702}$,MAE = 3.40分钟,MRE = 18.3%(图5B,右)。这种下降在化学上是有意义的:直链淀粉和纤维素衍生的CSP在螺旋手性和氢键拓扑结构上有所不同,而涂覆相和固定相表现出不同的构象刚性。如果没有CSP化学的明确描述符,模型会混淆不同的识别机制,这突出了条件感知编码或有针对性的迁移学习对于跨柱泛化的必要性。
5.3. Column Specifications: Transfer across Cartridge Formats
5.3. 色谱柱规格:不同柱套形式间的迁移
Variations in column specifications primarily affect hydrodynamic behavior rather than chemical selectivity. For the $4\mathrm{\;g}$ cartridge (4,864 runs, 218 compounds), predictive performance was high, with ${R}^{2} = {0.852}$ for ${V}_{1}$ and ${R}^{2} = {0.854}$ for ${V}_{2}$ (Figure 5C, left). Direct application of this baseline model to larger cartridges, however, yielded substantial degradation, with negative ${R}^{2}$ values for $8\mathrm{\;g},{25}\mathrm{\;g}$ , and ${40}\mathrm{\;g}$ formats. These results indicate systematic offsets in elution volumes arising from increased void volume and band broadening rather than stochastic noise. ${}^{2}$ Application of transfer learning with limited calibration experiments restored accuracy, yielding ${R}^{2} = {0.857}/ \; {0.644}\left( {8\mathrm{\;g}}\right) ,{0.747}/{0.840}\left( {{25}\mathrm{\;g}}\right)$ , and ${0.740}/{0.731}\left( {{40}\mathrm{\;g}}\right)$ . The comparatively greater sensitivity of ${V}_{2}$ reflects its dependence on peak width and dispersion effects, which are more susceptible to hydrodynamic scaling. These findings demonstrate that adsorption equilibria generalize across formats, while column-specific transport phenomena require explicit recalibration.
色谱柱规格的变化主要影响流体动力学行为,而非化学选择性。对于$4\mathrm{\;g}$柱套(4864次运行,218种化合物),预测性能很高,${V}_{1}$的${R}^{2} = {0.852}$为${R}^{2} = {0.854}$,${V}_{2}$的为${V}_{2}$(图5C,左)。然而,将此基线模型直接应用于更大的柱套时,性能大幅下降,$8\mathrm{\;g},{25}\mathrm{\;g}$和${40}\mathrm{\;g}$形式的${R}^{2}$值为负。这些结果表明,洗脱体积的系统偏移是由空隙体积增加和谱带展宽引起的,而非随机噪声。${}^{2}$通过有限的校准实验应用迁移学习恢复了准确性,得到了${R}^{2} = {0.857}/ \; {0.644}\left( {8\mathrm{\;g}}\right) ,{0.747}/{0.840}\left( {{25}\mathrm{\;g}}\right)$和${0.740}/{0.731}\left( {{40}\mathrm{\;g}}\right)$。${V}_{2}$相对更高的灵敏度反映了其对峰宽和分散效应的依赖性,而峰宽和分散效应更容易受到流体动力学缩放的影响。这些发现表明,吸附平衡在不同形式间具有通用性,而特定于色谱柱的传输现象需要进行明确的重新校准。
5.4. Small Data, Big Task
5.4. 小数据,大任务
Across these evaluations, a consistent principle emerges: accurate and interpretable chromatographic predictions can be achieved with relatively modest data sets, provided that mechanistic priors are embedded within the model. In TLC and CC, polarity-adsorption relationships support generalization under compound-level splits with only a few thousand training points. In GC, fewer than 4,000 records suffice to capture volatility-temperature coupling across diverse heating ramps. In CC, transfer learning with tens of calibration runs enables adaptation to cartridges differing by an order of magnitude in size. These observations exemplify a “small data, big task” paradigm: the incorporation of physical priors-adsorption equilibria, volatility-driven desorption, stereochemical recognition, and hydrodynamic dispersion-allows models to generalize effectively across compounds, chromatographic modes, and hardware formats. This principle highlights the central role of mechanistically informed AI in achieving extrapolative accuracy and practical applicability in chromatographic prediction.
在这些评估中,出现了一个一致的原则:只要模型中嵌入了机理先验知识,使用相对适度的数据集就可以实现准确且可解释的色谱预测。在薄层色谱(TLC)和柱色谱(CC)中,极性-吸附关系支持在仅几千个训练点的化合物级拆分下进行泛化。在气相色谱(GC)中,少于4000条记录就足以捕获不同升温速率下的挥发性-温度耦合。在柱色谱中,通过数十次校准运行进行迁移学习能够适应尺寸相差一个数量级的柱管。这些观察结果例证了一种“小数据,大任务”范式:纳入物理先验知识——吸附平衡、挥发性驱动的解吸、立体化学识别和流体动力学分散——使模型能够有效地跨化合物、色谱模式和硬件格式进行泛化。这一原则突出了机理驱动的人工智能在实现色谱预测的外推准确性和实际适用性方面的核心作用。
Moreover, the computational cost of training these models is modest. All models in this Account were trained on a single NVIDIA RTX 4090 GPU. For TLC, model training typically requires only ${10} - {20}\mathrm{\;{min}}$ . The CC model, trained for up to 1,000 epochs with early stopping, usually converges within 40-50 min, while transfer-learning adaptations to new cartridge formats require only an additional 10-15 min. For HPLC, full model training completes within approximately 4-5 h, and GC models converge around ${700} - {800}$ epochs, with a complete 1,500-epoch schedule taking about 5-6 h. These timings indicate that the proposed frameworks are computationally efficient and readily trainable or fine-tunable on standard workstation hardware, facilitating practical deployment in both academic and industrial laboratories.
此外,训练这些模型的计算成本适中。本综述中的所有模型均在单个NVIDIA RTX 4090 GPU上进行训练。对于薄层色谱,模型训练通常仅需${10} - {20}\mathrm{\;{min}}$ 。柱色谱模型在使用早期停止策略训练多达1000个轮次时,通常在40 - 50分钟内收敛,而对新柱管格式的迁移学习调整仅需额外10 - 15分钟。对于高效液相色谱(HPLC),完整的模型训练在大约4 - 5小时内完成,气相色谱模型在${700} - {800}$ 轮次左右收敛,完整的1500轮次训练计划大约需要5 - 6小时。这些时间表明,所提出的框架在计算上是高效的,并且可以在标准工作站硬件上轻松训练或微调,便于在学术和工业实验室中实际部署。
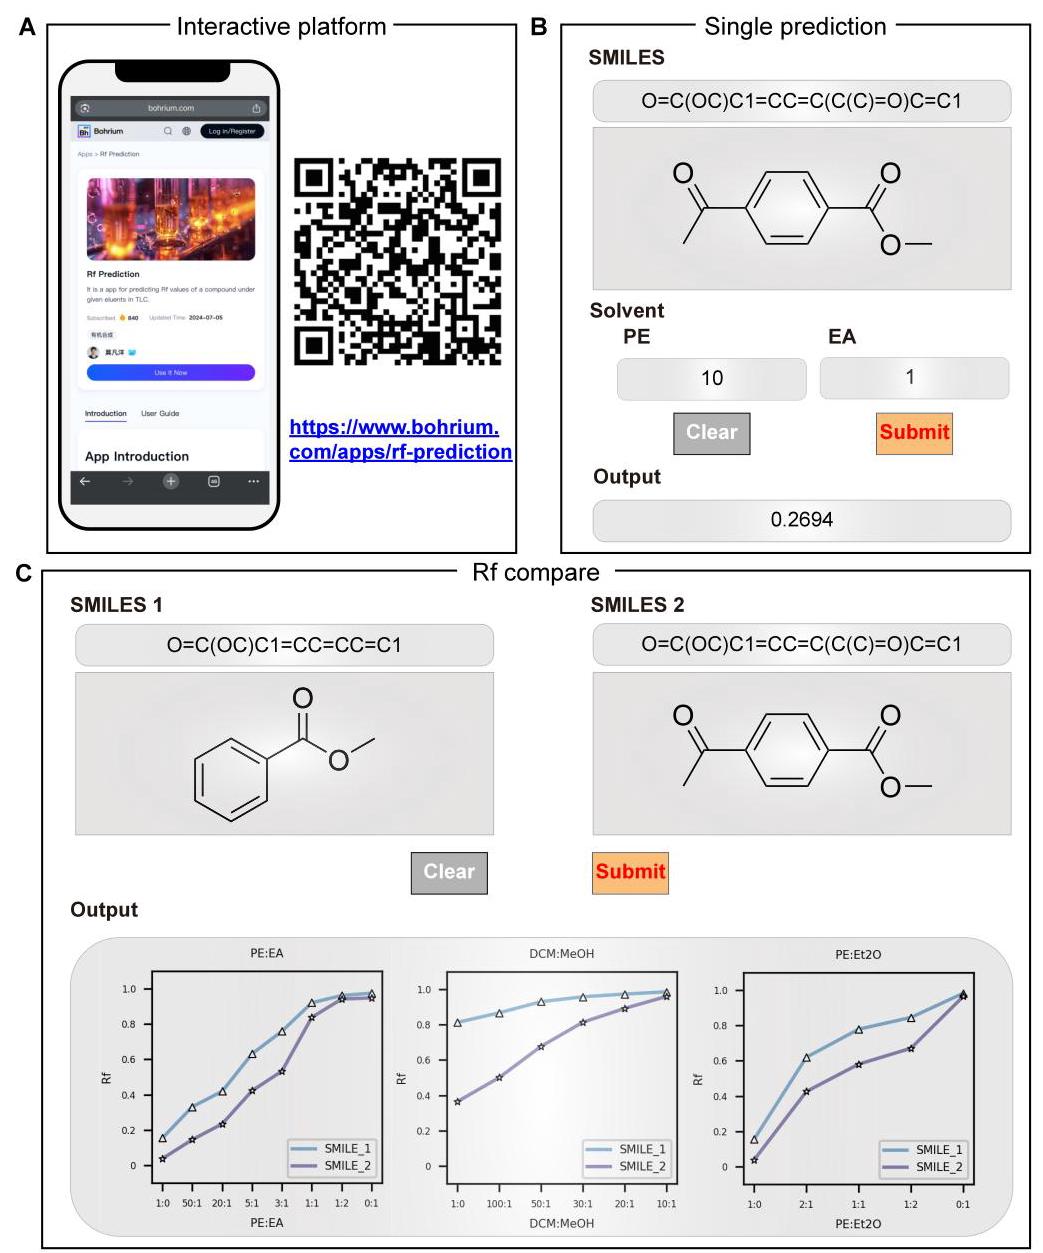
Figure 6. User-facing deployment of TLC ${R}_{f}$ prediction models. (A) Interactive platform interface with mobile and QR-code access. (B) Single prediction from SMILES and user-defined solvent composition. (C) Comparison of solvent-dependent ${R}_{f}$ values for two molecules across eluent systems.
图6. 面向用户部署的薄层色谱${R}_{f}$预测模型。(A) 具有移动和二维码访问功能的交互式平台界面。(B) 根据SMILES和用户定义的溶剂组成进行的单次预测。(C) 两种分子在不同洗脱系统中溶剂依赖性${R}_{f}$值的比较。
6. MODEL DEPLOYMENT AND PRACTICAL INTEGRATION
6. 模型部署与实际整合
The ultimate value of predictive modeling lies in how seamlessly it integrates with chemical practice. In chromatography, deployment spans three complementary levels: user-facing tools, closed-loop automation, and scalability across heterogeneous laboratory setups.
预测建模的最终价值在于它与化学实践的无缝整合程度。在色谱分析中,部署涵盖三个互补层面:面向用户的工具、闭环自动化以及跨异构实验室设置的可扩展性。
6.1. From Prediction Models to User Interfaces
6.1. 从预测模型到用户界面
Interactive web applications have become a key vehicle for translating predictive models into practical scientific tools, as they lower technical barriers and promote accessibility for researchers without programming expertise. ${}^{43}$ To bring our TLC ${R}_{f}$ prediction model into routine laboratory use, we deploy it as an online application on Bohrium (available at https:// www.bohrium.com/apps/rf-prediction), providing a streamlined interface for experimental planning (Figure 6A).
交互式网络应用程序已成为将预测模型转化为实用科学工具的关键载体,因为它们降低了技术壁垒,使没有编程专业知识的研究人员也能更方便地使用。${}^{43}$ 为了将我们的TLC ${R}_{f}$ 预测模型应用于常规实验室,我们将其作为在线应用程序部署在Bohrium上(可在https://www.bohrium.com/apps/rf-prediction访问),提供了一个用于实验规划的简化界面(图6A)。
The single prediction module (Figure 6B) takes a SMILES input and outputs the predicted ${R}_{f}$ value under user-defined solvent compositions across supported eluent systems. The ${R}_{f}$ comparison module (Figure 6C) evaluates two molecules across multiple solvent systems, enabling rapid analysis of solvent-dependent ${R}_{f}$ trends for purification planning and structural differentiation.
单一预测模块(图6B)接受SMILES输入,并在用户定义的跨支持洗脱剂系统的溶剂组成下输出预测的 ${R}_{f}$ 值。${R}_{f}$ 比较模块(图6C)在多个溶剂系统中评估两个分子,能够快速分析溶剂依赖性 ${R}_{f}$ 趋势,以进行纯化规划和结构区分。
This deployment constitutes the initial release of our platform (TLC 1.0). While TLC 1.0 effectively covers the organic chemical space represented in our training data, highly polar molecules-such as amino acids, peptides, and sugars-fall outside this domain and are often better resolved by reverse-phase TLC rather than the normal-phase conditions modeled here. Accordingly, we are extending the framework toward TLC 2.0, incorporating reverse-phase TLC to expand coverage to highly polar and biorelevant species. Together, these modules provide an extensible foundation for AI-assisted chromatographic planning.
此次部署构成了我们平台的初始版本(TLC 1.0)。虽然TLC 1.0有效地覆盖了我们训练数据中所代表的有机化学空间,但高极性分子,如氨基酸、肽和糖,不在此范围内,通常通过反相TLC比这里建模的正相条件能得到更好的分离。因此,我们正在将框架扩展到TLC 2.0,纳入反相TLC以将覆盖范围扩展到高极性和生物相关物种。总之,这些模块为人工智能辅助的色谱分析规划提供了一个可扩展的基础。
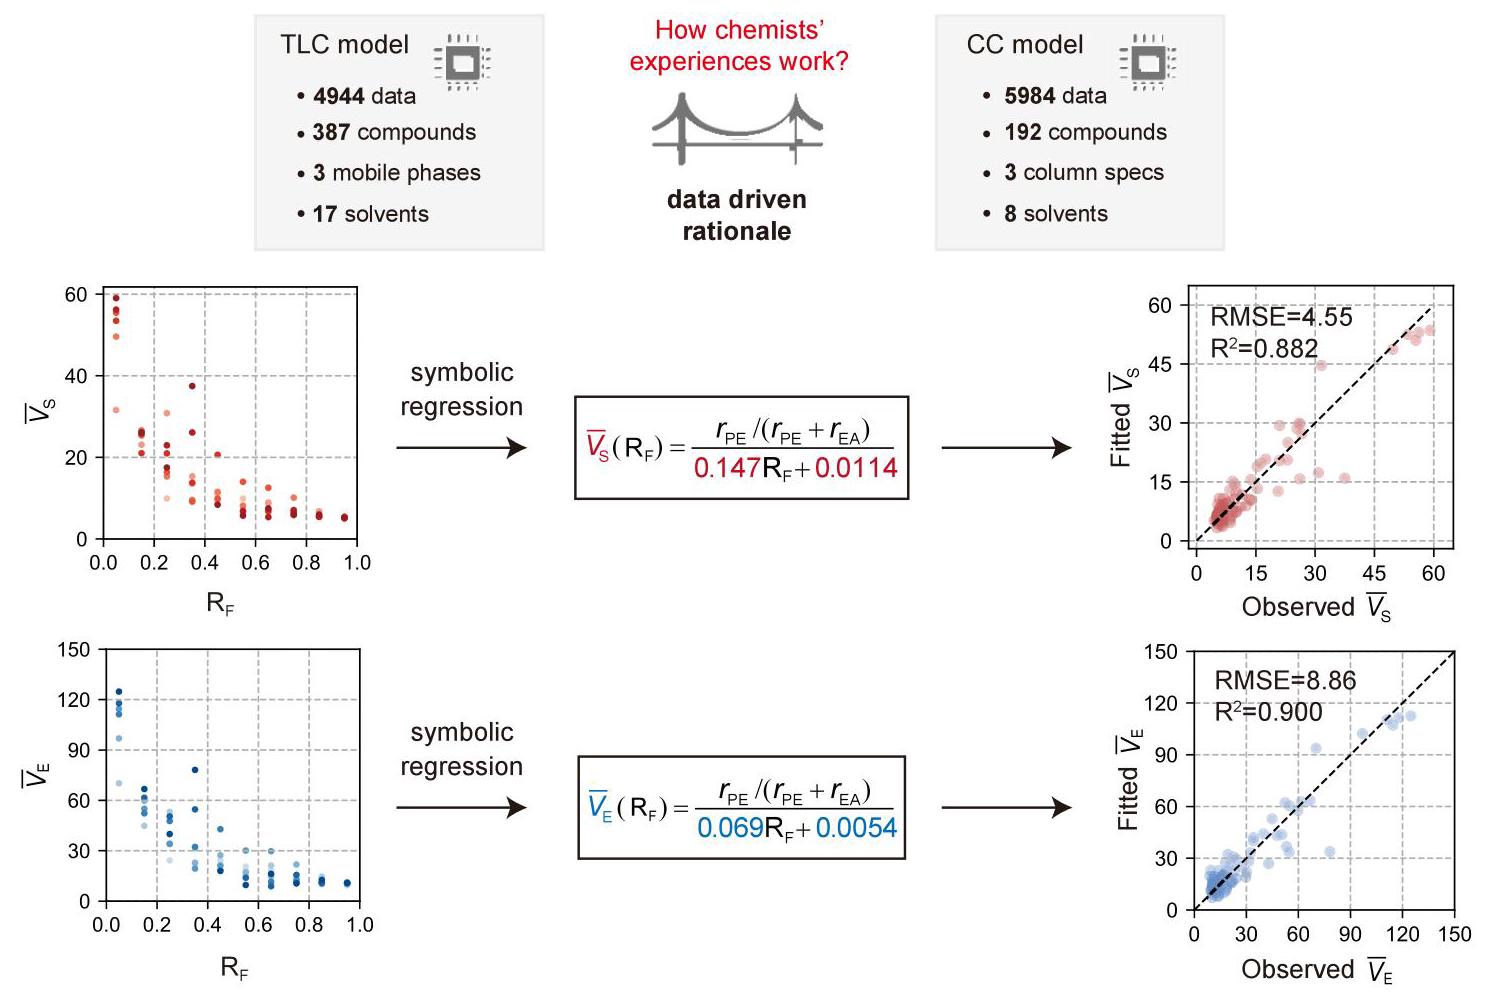
Figure 7. Formalizing the TLC-CC correspondence. Symbolic regression reveals explicit scaling laws between TLC mobility $\left( {R}_{f}\right)$ and CC elution volumes $\left( {{V}_{\mathrm{S}},{V}_{\mathrm{E}}}\right)$ , achieving ${R}^{2} = {0.882}$ and ${R}^{2} = {0.900}$ . These relations convert empirical heuristics into transferable equations linking analytical TLC to preparative CC.
图7. 形式化TLC-CC对应关系。符号回归揭示了TLC迁移率 $\left( {R}_{f}\right)$ 和CC洗脱体积 $\left( {{V}_{\mathrm{S}},{V}_{\mathrm{E}}}\right)$ 之间的明确缩放定律,实现了 ${R}^{2} = {0.882}$ 和 ${R}^{2} = {0.900}$ 。这些关系将经验启发式方法转化为将分析型TLC与制备型CC联系起来的可转移方程。
6.2. Practical Integration of Predictive Models
6.2. 预测模型的实际整合
Integrating predictive models with robotic platforms transforms them from passive predictors into active drivers of experimentation: TLC/CC systems use predictions to guide solvent selection, GC models prescreen temperature programs, and HPLC probabilities prioritize column-solvent combinations. Experimental outcomes are automatically fed back, closing the loop between computation and experiment.
将预测模型与机器人平台集成,可将它们从被动预测器转变为实验的主动驱动因素:薄层色谱/柱色谱系统利用预测来指导溶剂选择,气相色谱模型对温度程序进行预筛选,而高效液相色谱概率则对柱-溶剂组合进行优先级排序。实验结果会自动反馈,从而闭合计算与实验之间的循环。
Within the broader chromatographic ecosystem, a range of predictive approaches has been developed-spanning commercial QSRR (quantitative structure-retention relationship)-based software, open LC predictors such as OPERA-RT, ${}^{44}$ MS-assisted scoring frameworks such as MetFrag RT, ${}^{45}$ and method-transfer tools including PredRet ${}^{46}$ and retention projection. These methods have provided considerable value for modality-specific tasks such as reversed-phase LC retention estimation, GC method screening, and cross-instrument retention harmonization.
在更广泛的色谱生态系统中,已经开发了一系列预测方法,涵盖基于商业定量结构-保留关系(QSRR)的软件、诸如OPERA-RT之类的开放式液相色谱预测器、${}^{44}$ 诸如MetFrag RT之类的质谱辅助评分框架、${}^{45}$ 以及包括PredRet ${}^{46}$ 和保留投影在内的方法转移工具。这些方法为诸如反相液相色谱保留估计、气相色谱方法筛选以及跨仪器保留协调等特定模式任务提供了相当大的价值。
However, existing tools are generally tailored to specific chromatographic mechanisms (e.g., gradient LC or temperature-programmed GC) and are not designed to capture the adsorption-driven, solvent-ratio-dependent behavior characteristic of normal-phase TLC/CC, nor do they offer unified decision metrics that extend across multiple separation modes. In this context, our framework is formulated to be mode-general rather than mode-specific-providing a single structure-condition-retention formulation that supports prediction and condition ranking across TLC, CC, GC, and HPLC. Ultimately, the objective is not predictive accuracy alone, but the translation of those predictions into experimentally actionable decisions that accelerate chromatographic method development across diverse laboratory environments.
然而,现有工具通常是针对特定的色谱机制(例如梯度液相色谱或程序升温气相色谱)量身定制的,并非设计用于捕捉正相薄层色谱/柱色谱中吸附驱动、溶剂比例依赖的行为特征,它们也没有提供适用于多种分离模式的统一决策指标。在此背景下,我们构建的框架是模式通用而非特定模式的,提供单一的结构-条件-保留公式,支持对薄层色谱、柱色谱、气相色谱和高效液相色谱进行预测和条件排序。最终目标不仅是预测准确性,还在于将这些预测转化为可通过实验操作的决策,以加速在各种实验室环境中的色谱方法开发。
7. FROM EMPIRICAL HEURISTICS TO MECHANISTIC FOUNDATIONS
7. 从经验启发法到机理基础
7.1. From TLC-CC Experience to Mathematical Formalization
7.1. 从薄层色谱 - 柱色谱经验到数学形式化
Thin-layer chromatography (TLC) has long served as a heuristic guide for column chromatography (CC), where chemists estimate elution strength by observing ${R}_{f}$ values. Traditionally, this “TLC-CC correspondence” has been qualitative, resting on empirical experience rather than quantitative rules. By systematically analyzing paired data sets, we established explicit mathematical relations between TLC mobility and CC elution volumes $\left( {{V}_{\mathrm{S}},{V}_{\mathrm{E}}}\right)$ , thereby converting tacit knowledge into transferable eqs (Figure 7). ${}^{3}$
长期以来,薄层色谱(TLC)一直是柱色谱(CC)的启发式指南,化学家通过观察${R}_{f}$值来估计洗脱强度。传统上,这种“TLC - CC对应关系”一直是定性的,基于经验而非定量规则。通过系统地分析配对数据集,我们建立了TLC迁移率与CC洗脱体积$\left( {{V}_{\mathrm{S}},{V}_{\mathrm{E}}}\right)$之间的明确数学关系,从而将隐性知识转化为可转移的方程(图7)。${}^{3}$
Symbolic regression on 4,944 TLC measurements and 5,984 CC runs yielded linearized scaling laws that connect ${R}_{f}$ values with normalized elution volumes (eqs 2a and 2b)
对4944次TLC测量和5984次CC运行进行符号回归,得出了将${R}_{f}$值与归一化洗脱体积联系起来的线性化比例定律(方程2a和2b)
$$ {\bar{V}}_{\mathrm{S}}\left( {R}_{f}\right) = \frac{{r}_{\mathrm{{PE}}}}{{r}_{\mathrm{{PE}}} + {r}_{\mathrm{{EA}}}}\left( {{0.147}{R}_{f} + {0.0114}}\right) \tag{2a} $$$$ {\bar{V}}_{\mathrm{E}}\left( {R}_{f}\right) = \frac{{r}_{\mathrm{{PE}}}}{{r}_{\mathrm{{PE}}} + {r}_{\mathrm{{EA}}}}\left( {{0.069}{R}_{f} + {0.0054}}\right) \tag{2b} $$where ${r}_{\mathrm{{PE}}}$ and ${r}_{\mathrm{{EA}}}$ denote solvent composition ratios.
其中${r}_{\mathrm{{PE}}}$和${r}_{\mathrm{{EA}}}$表示溶剂组成比。
The fitted models achieve ${R}^{2} = {0.882}\left( {V}_{\mathrm{S}}\right)$ and ${R}^{2} = {0.900} \; \left( {V}_{\mathrm{E}}\right)$ , with RMSE values of 4.55 and 8.86, respectively, confirming that TLC mobility encodes sufficient physical information to predict preparative CC performance with quantitative accuracy. Chemically, the trends align with adsorption-desorption thermodynamics: solutes with higher ${R}_{f}$ exhibit weaker interactions with silica and thus elute at lower volumes, while strongly adsorbing solutes $\left( {{R}_{f} \rightarrow 0}\right)$ require larger solvent volumes to overcome surface retention. The difference between ${V}_{\mathrm{S}}$ and ${V}_{\mathrm{E}}$ further reflects the onset versus completion of elution, analogous to the spread between breakthrough and saturation in adsorption isotherms.
拟合模型实现了${R}^{2} = {0.882}\left( {V}_{\mathrm{S}}\right)$和${R}^{2} = {0.900} \; \left( {V}_{\mathrm{E}}\right)$,RMSE值分别为4.55和8.86,证实TLC迁移率编码了足够的物理信息,能够以定量精度预测制备型CC的性能。从化学角度来看,这些趋势与吸附 - 解吸热力学一致:具有较高${R}_{f}$的溶质与硅胶的相互作用较弱,因此在较低体积下洗脱,而强吸附溶质$\left( {{R}_{f} \rightarrow 0}\right)$需要更大的溶剂体积来克服表面保留。${V}_{\mathrm{S}}$和${V}_{\mathrm{E}}$之间的差异进一步反映了洗脱的开始与完成情况,类似于吸附等温线中突破与饱和之间的差距。
By formalizing the TLC-CC relationship into explicit equations, these results transform experiential heuristics into a data-driven rationale. This not only validates the empirical practice of “using TLC to guide CC” but also provides a generalizable framework for method transfer, where TLC measurements can be quantitatively translated into preparative-scale solvent and column conditions.
通过将TLC - CC关系形式化为明确的方程,这些结果将经验启发式方法转化为数据驱动的原理。这不仅验证了“使用TLC指导CC”的经验做法,还为方法转移提供了一个可推广的框架,其中TLC测量可以定量转化为制备规模的溶剂和柱条件。
7.2. Unified Thermodynamic-Kinetic Framework for Chromatographic Retention
7.2. 色谱保留的统一热力学 - 动力学框架
Although TLC, CC, GC, and chiral HPLC operate under distinct physicochemical regimes, all chromatographic processes can be framed within a unified abstraction: retention reflects the coupled influence of thermodynamic phase preference and transport-mediated peak development. Thermodynamics determines how molecular features-polarity, volatility, or stereochemistry-shape the Gibbs free-energy differences between coexisting phases, whether adsorption sites on silica, vapor-liquid equilibria in GC stationary films, or asymmetric binding pockets on chiral stationary phases. Transport phenomena-diffusion, mass-transfer resistance, and hydrodynamic flow-govern how these free-energy landscapes translate into observable retention coordinates.
尽管薄层色谱(TLC)、柱色谱(CC)、气相色谱(GC)和手性高效液相色谱(chiral HPLC)在不同的物理化学条件下运行,但所有色谱过程都可以在一个统一的抽象框架内进行描述:保留反映了热力学相偏好和传输介导的峰展宽的耦合影响。热力学决定了分子特征(极性、挥发性或立体化学)如何塑造共存相之间的吉布斯自由能差异,无论是硅胶上的吸附位点、气相色谱固定膜中的气液平衡,还是手性固定相上的不对称结合口袋。传输现象(扩散、传质阻力和流体动力流)则控制着这些自由能态势如何转化为可观测的保留坐标。
Within this framework, TLC and CC represent polarity-controlled adsorption equilibria, GC expresses temperature-dependent vapor-liquid partitioning under dynamic heating programs, and chiral HPLC encodes ${\Delta \Delta G}$ -scale differences in diastereomeric complexation. Despite their mechanistic differences, all modalities map molecular structure and operating conditions onto macroscopic retention through a shared thermodynamic-kinetic convolution. This abstraction provides a coherent foundation for cross-modal analysis and guides the design of machine-learning models that incorporate mode-specific descriptors while adhering to common chromatographic principles.
在此框架内,薄层色谱和柱色谱代表极性控制的吸附平衡,气相色谱在动态加热程序下表现出温度依赖性的气液分配,而手性高效液相色谱编码非对映体络合中${\Delta \Delta G}$尺度的差异。尽管它们的机理不同,但所有模式都通过共享的热力学 - 动力学卷积将分子结构和操作条件映射到宏观保留上。这种抽象为跨模式分析提供了一个连贯的基础,并指导机器学习模型的设计,这些模型在遵循共同色谱原理的同时纳入特定模式的描述符。
8. SUMMARY AND OUTLOOK
8. 总结与展望
This Account highlights how automation, mechanistically informed feature engineering, and tailored algorithms transform chromatography from an empirical practice into a predictive science. By integrating predictive models with robotic platforms, separations can be guided in real time and refined through experimental feedback, while transfer learning and condition embeddings ensure portability across laboratories.
本综述重点介绍了自动化、基于机理的特征工程和定制算法如何将色谱从一种经验性实践转变为一门预测性科学。通过将预测模型与机器人平台相结合,可以实时指导分离过程,并通过实验反馈进行优化,同时迁移学习和条件嵌入确保了跨实验室的可移植性。
Beyond the modalities examined in this Account, the same mechanistically informed principles may, in principle, be applicable to additional chromatographic systems. Reversed-phase liquid chromatography (RP-LC), for example, is driven by hydrophobicity- and solvation-related interactions under gradient elution, ${}^{{47},{48}}$ whereas supercritical fluid chromatography (SFC) involves pressure- and density-dependent transport phenomena. ${}^{{49},{50}}$ Extending the framework to such modes would require mode-specific descriptors and well-standardized conditions, and we view this as a promising direction for future methodological development.
除了本综述中研究的模式外,同样基于机理的原理原则上可能适用于其他色谱系统。例如,反相液相色谱(RP-LC)在梯度洗脱下由与疏水性和溶剂化相关的相互作用驱动,${}^{{47},{48}}$而超临界流体色谱(SFC)涉及与压力和密度相关的传输现象。${}^{{49},{50}}$将该框架扩展到这些模式需要特定模式的描述符和标准化良好的条件,我们认为这是未来方法学发展的一个有前景的方向。
Looking forward, advances in preparative automation, from prep-TLC to fully integrated column systems, promise end-to-end workflows with minimal manual intervention. Large language models (LLMs) further complement structured data sets by mining literature, extracting heuristics, and enhancing interpretability. ${}^{{51} - {55}}$ Together, these developments point toward a future in which chromatography is predictive, programmable, and universally reproducible, enabling self-optimizing workflows that accelerate discovery across chemical sciences.
展望未来,从制备薄层色谱到完全集成的柱系统,制备自动化的进展有望实现几乎无需人工干预的端到端工作流程。大语言模型(LLMs)通过挖掘文献、提取启发式方法和增强可解释性,进一步补充结构化数据集。${}^{{51} - {55}}$总之,这些发展指向一个色谱具有预测性、可编程性和普遍可重复性的未来,实现自我优化的工作流程,加速化学科学领域的发现。
AUTHOR INFORMATION
作者信息
Corresponding Author
通讯作者
Fanyang Mo - School of AI for Science, Peking University Shenzhen Graduate School, Shenzhen 518055, China; AI for Science (AI4S)-Preferred Program, School of Advanced Materials, and Guangdong Provincial Key Laboratory of Nano-Micro Materials Research, Peking University Shenzhen Graduate School, Shenzhen 518055, China; State Key Laboratory of Advanced Waterproof Materials, School of Materials Science and Engineering, Peking University, Beijing 100871, China; © orcid.org/0000-0002-4140-3020;
莫凡洋 - 北京大学深圳研究生院人工智能科学学院,中国深圳518055;北京大学深圳研究生院先进材料学院人工智能科学(AI4S)优选计划及广东省纳米微材料研究重点实验室,中国深圳518055;北京大学材料科学与工程学院先进防水材料国家重点实验室,中国北京100871;© orcid.org/0000-0002-4140-3020;
Author
作者
Chengchun Liu - School of AI for Science, Peking University Shenzhen Graduate School, Shenzhen 518055, China; AI for Science (AI4S)-Preferred Program, Peking University Shenzhen Graduate School, Shenzhen 518055, China; State Key Laboratory of Advanced Waterproof Materials, School of Materials Science and Engineering, Peking University, Beijing 100871, China; (C) orcid.org/0009-0002-5550-4145
刘丞军 - 中国北京大学深圳研究生院人工智能科学学院,深圳518055;中国北京大学深圳研究生院人工智能科学(AI4S)优先计划,深圳518055;中国北京大学材料科学与工程学院先进防水材料国家重点实验室,北京100871;(C) orcid.org/0009-0002-5550-4145
Complete contact information is available at:
完整的联系信息可在以下网址获取:
https://pubs.acs.org/10.1021/acs.accounts.5c00677
Author Contributions
作者贡献
F.M. and C.L. conceived the project, designed the method, and analyzed the results. C.L. organized and prepared structural data. F.M. and C.L. wrote the paper. F.M. supervised the project. CRediT: Chengchun Liu conceptualization, data curation, formal analysis, methodology, visualization, writing - original draft; Fanyang Mo conceptualization, data curation, formal analysis, funding acquisition, investigation, methodology, project administration, resources, software, supervision, validation, visualization, writing - original draft, writing - review & editing.
F.M.和C.L.构思了该项目,设计了方法,并分析了结果。C.L.整理并准备了结构数据。F.M.和C.L.撰写了论文。F.M.监督了该项目。CRediT:刘丞军概念化、数据管理、形式分析、方法学、可视化、撰写原始草案;莫凡洋概念化、数据管理、形式分析、资金获取、调查、方法学、项目管理、资源、软件、监督、验证、可视化、撰写原始草案、撰写评审和编辑。
Notes
注释
The authors declare no competing financial interest.
作者声明不存在相互冲突的财务利益。
Biographies
人物传记
Chengchun Liu received his B.Sc. degree in Chemistry from Nankai University and is currently a Ph.D. candidate in the School of Materials Science and Engineering, Peking University, under the supervision of Prof. Fanyang Mo. His research interests focus on AI-assisted spectroscopy, chromatographic separation, and computational methods for chemical informatics.
刘丞军于南开大学获得化学学士学位,目前是北京大学材料科学与工程学院的博士研究生,导师为莫凡洋教授。他的研究兴趣集中在人工智能辅助光谱学、色谱分离以及化学信息学的计算方法。
Fanyang Mo received his B.Sc. and M.S. degrees in Chemistry from Beijing Institute of Technology in 2004 and 2006, respectively, and his Ph.D. from Peking University under the supervision of Prof. Jianbo Wang. After postdoctoral research at the Scripps Research Institute and The University of Texas at Austin, he joined Peking University in 2015, where he is now an Associate Professor. His research interests focus on AI for Chemistry, chromatographic separation, laboratory automation, and computational methods for chemical informatics.
莫凡洋分别于2004年和2006年在北京理工大学获得化学学士和硕士学位,并在王剑波教授的指导下于北京大学获得博士学位。在斯克里普斯研究所和德克萨斯大学奥斯汀分校进行博士后研究后,他于2015年加入北京大学,现任副教授。他的研究兴趣集中在化学人工智能、色谱分离、实验室自动化以及化学信息学的计算方法。
ACKNOWLEDGMENTS
致谢
We thank Peking University Shenzhen Graduate School and Shenzhen Government for the start-up funding support. We thank the High-Performance Computing Platform of Peking University for machine learning model training.
我们感谢北京大学深圳研究生院和深圳市政府提供的启动资金支持。我们感谢北京大学高性能计算平台提供机器学习模型训练。
ABBREVIATIONS
缩写
AI, Artificial Intelligence; CC, Column Chromatography; CMRT, Chiral Molecular Retention Time; CSP, Chiral Stationary Phase; GC, Gas Chromatography; HPLC, High-Performance Liquid Chromatography; QGeoGNN, Quantile Geometry-enhanced Graph Neural Network; RT, Retention Time; SMILES, Simplified Molecular Input Line Entry System; TLC, Thin-Layer Chromatography; TPSA, Topological Polar Surface Area; QSRR, Quantitative Structure-Retention Relationship
人工智能;柱色谱法;手性分子保留时间;手性固定相;气相色谱法;高效液相色谱法;分位数几何增强图神经网络;保留时间;简化分子线性输入系统;薄层色谱法;拓扑极性表面积;定量结构-保留关系
R REFERENCES
R参考文献
(1) Xu, H.; Lin, J.; Liu, Q.; Chen, Y.; Zhang, J.; Yang, Y.; Young, M. C.; Xu, Y.; Zhang, D.; Mo, F. High-throughput discovery of chemical structure-polarity relationships combining automation and machine-learning techniques. Chem 2022, 8, 3202-3214.
(2) Wu, W.; Xu, H.; Xu, Y.; Luo, P.; Zeng, Q.; Chen, Y.; Xu, Y.; Zhang, D.; Mo, F. Intelligent column chromatography prediction model based on automation and machine learning. Chem 2025, 11, 102598.
(3) Xu, H.; Wu, W.; Chen, Y.; Zhang, D.; Mo, F. Explicit relation between thin film chromatography and column chromatography conditions from statistics and machine learning. Nat. Commun. 2025, 16, 832.
(4) Lin, J.; Song, L.; Chen, Y.; Liu, C.; Chen, S.; Mo, F. Multimodal learning in synthetic chemistry applications: gas chromatography retention time prediction and isomer separation optimization. Digit. Discovery 2025, 4, 2465-2477.
(5) Xu, H.; Lin, J.; Zhang, D.; Mo, F. Retention time prediction for chromatographic enantioseparation by quantile geometry-enhanced graph neural network. Nat. Commun. 2023, 14, 3095.
(6) Buszewski, B.; Bocian, S.; Felinger, A. Artifacts in Liquid-Phase Separations-System, Solvent, and Impurity Peaks. Chem. Rev. 2012, 112, 2629-2641.
(7) Zuvela, P.; Skoczylas, M.; Jay Liu, J.; Baczek, T.; Kaliszan, R.; Wong, M. W.; Buszewski, B. Column characterization and selection systems in reversed-phase high-performance liquid chromatography. Chem. Rev. 2019, 119, 3674-3729.
(8) Peluso, P.; Chankvetadze, B. Recognition in the domain of molecular chirality: from noncovalent interactions to separation of enantiomers. Chem. Rev. 2022, 122, 13235-13400.
(9) Abdulhussain, N.; Nawada, S.; Schoenmakers, P. Latest trends on the future of three-dimensional separations in chromatography. Chem. Rev. 2021, 121, 12016-12034.
(10) Lorenz, H.; Seidel-Morgenstern, A. Processes to separate enantiomers. Angew. Chem., Int. Ed. 2014, 53, 1218-1250.
(11) Kuehnbaum, N. L.; Britz-McKibbin, P. New advances in separation science for metabolomics: resolving chemical diversity in a post-genomic era. Chem. Rev. 2013, 113, 2437-2468.
(12) Thomas, S. N.; French, D.; Jannetto, P. J.; Rappold, B. A.; Clarke, W. A. Liquid chromatography-tandem mass spectrometry for clinical diagnostics. Nat. Rev. Methods Primers 2022, 2, 96.
(13) Striegel, A. M.; Brewer, A. K.; Zielke, C. Size-exclusion chromatography with multi-angle static light scattering. Nat. Rev. Methods Primers 2025, 5, 40.
(14) Zacate, S. B.; Dantas, J. A.; Lin, S.; Doyle, A. G.; Sigman, M. S. Considerations in Pursuing Reaction Scope Generality. Angew. Chem., Int. Ed. 2025, 64, No. e202511091.
(15) Ruos, M. E.; Romer, N. P.; Deichert, J. A.; Alabanza, L. M.; Gandhi, S. S.; Brown, G. Z.; Walroth, R. C.; Cruz, K.; Gosselin, F.; Hong, A. Y.; et al. Data Science-Guided Development of Deoxyfluori-nation Reagents with Enhanced Reactivity, Practicality, and Safety. J. Am. Chem. Soc. 2025, 147, 25815-25824.
(16) Souza, L. W.; Ricke, N. D.; Chaffin, B. C.; Fortunato, M. E.; Jiang, S.; Soylu, C.; Caya, T. C.; Lau, S. H.; Wieser, K. A.; Doyle, A. G.; et al. Applying Active Learning toward Building a Generalizable Model for Ni-Photoredox Cross-Electrophile Coupling of Aryl and Alkyl Bromides. J. Am. Chem. Soc. 2025, 147, 18747-18759.
(17) Gandhi, S. S.; Brown, G. Z.; Aikonen, S.; Compton, J. S.; Neves, P.; Martinez Alvarado, J. I.; Strambeanu, I. I.; Leonard, K. A.; Doyle, A. G. Data Science-Driven Discovery of Optimal Conditions and a Condition-Selection Model for the Chan-Lam Coupling of Primary Sulfonamides. ACS Catal. 2025, 15, 2292-2304.
(18) Wang, J. Y.; Stevens, J. M.; Kariofillis, S. K.; Tom, M.-J.; Golden, D. L.; Li, J.; Tabora, J. E.; Parasram, M.; Shields, B. J.; Primer, D. N.; et al. Identifying general reaction conditions by bandit optimization. Nature 2024, 626, 1025-1033.
(19) Raghavan, P.; Haas, B. C.; Ruos, M. E.; Schleinitz, J.; Doyle, A. G.; Reisman, S. E.; Sigman, M. S.; Coley, C. W. Dataset design for building models of chemical reactivity. ACS Cent. Sci. 2023, 9, 2196- 2204.
(20) Romer, N. P.; Min, D. S.; Wang, J. Y.; Walroth, R. C.; Mack, K. A.; Sirois, L. E.; Gosselin, F.; Zell, D.; Doyle, A. G.; Sigman, M. S. Data science guided multiobjective optimization of a stereoconvergent nickel-catalyzed reduction of enol tosylates to access trisubstituted alkenes. ACS Catal. 2024, 14, 4699-4708.
(21) Zuranski, A. M.; Gandhi, S. S.; Doyle, A. G. A machine learning approach to model interaction effects: Development and application to alcohol deoxyfluorination. J. Am. Chem. Soc. 2023, 145, 7898-7909.
(22) Kariofillis, S. K.; Jiang, S.; Zurański, A. M.; Gandhi, S. S.; Martinez Alvarado, J. I.; Doyle, A. G. Using data science to guide aryl bromide substrate scope analysis in a Ni/photoredox-catalyzed cross-coupling with acetals as alcohol-derived radical sources. J. Am. Chem. Soc. 2022, 144, 1045-1055.
(23) Liu, C.; Zou, R.; Mo, F. Infrared Spectra Prediction for Functional Group Region Utilizing a Machine Learning Approach with Structural Neighboring Mechanism. Anal. Chem. 2024, 96, 15550- 15562.
(24) Kearnes, S. M.; Maser, M. R.; Wleklinski, M.; Kast, A.; Doyle, A. G.; Dreher, S. D.; Hawkins, J. M.; Jensen, K. F.; Coley, C. W. The open reaction database. J. Am. Chem. Soc. 2021, 143, 18820-18826.
(25) Williams, W. L.; Zeng, L.; Gensch, T.; Sigman, M. S.; Doyle, A. G.; Anslyn, E. V. The evolution of data-driven modeling in organic chemistry. ACS Cent. Sci. 2021, 7, 1622-1637.
(26) Zuranski, A. M.; Martinez Alvarado, J. I.; Shields, B. J.; Doyle, A. G. Predicting reaction yields via supervised learning. Acc. Chem. Res. 2021, 54, 1856-1865.
(27) Shen, Y.; Borowski, J. E.; Hardy, M. A.; Sarpong, R.; Doyle, A. G.; Cernak, T. Automation and computer-assisted planning for chemical synthesis. Nat. Rev. Methods Primers 2021, 1, 23.
(28) Shields, B. J.; Stevens, J.; Li, J.; Parasram, M.; Damani, F.; Alvarado, J. I. M.; Janey, J. M.; Adams, R. P.; Doyle, A. G. Bayesian reaction optimization as a tool for chemical synthesis. Nature 2021, 590, 89-96.
(29) Ahneman, D. T.; Estrada, J. G.; Lin, S.; Dreher, S. D.; Doyle, A. G. Predicting reaction performance in $\mathrm{C} - \mathrm{N}$ cross-coupling using machine learning. Science 2018, 360, 186-190.
(30) Nielsen, M. K.; Ahneman, D. T.; Riera, O.; Doyle, A. G. Deoxyfluorination with sulfonyl fluorides: navigating reaction space with machine learning. J. Am. Chem. Soc. 2018, 140, 5004-5008.
(31) Wilbraham, L.; Mehr, S. H. M.; Cronin, L. Digitizing chemistry using the chemical processing unit: from synthesis to discovery. Acc. Chem. Res. 2021, 54, 253-262.
(32) Szymanski, J. K.; Abul-Haija, Y. M.; Cronin, L. Exploring strategies to bias sequence in natural and synthetic oligomers and polymers. Acc. Chem. Res. 2018, 51, 649-658.
(33) Sharma, A.; Czégel, D.; Lachmann, M.; Kempes, C. P.; Walker, S. I.; Cronin, L. Assembly theory explains and quantifies selection and evolution. Nature 2023, 622, 321-328.
(34) Granda, J. M.; Donina, L.; Dragone, V.; Long, D.-L.; Cronin, L. Controlling an organic synthesis robot with machine learning to search for new reactivity. Nature 2018, 559, 377-381.
(35) Rohrbach, S.; Siauciulis, M.; Chisholm, G.; Pirvan, P.-A.; Saleeb, M.; Mehr, S. H. M.; Trushina, E.; Leonov, A. I.; Keenan, G.; Khan, A.; et al. Digitization and validation of a chemical synthesis literature database in the ChemPU. Science 2022, 377, 172-180.
(36) Strieth-Kalthoff, F.; Hao, H.; Rathore, V.; Derasp, J.; Gaudin, T.; Angello, N. H.; Seifrid, M.; Trushina, E.; Guy, M.; Liu, J.; et al. Delocalized, asynchronous, closed-loop discovery of organic laser emitters. Science 2024, 384, No. eadk9227.
(37) Mehr, S. H. M.; Craven, M.; Leonov, A. I.; Keenan, G.; Cronin, L. A universal system for digitization and automatic execution of the chemical synthesis literature. Science 2020, 370, 101-108.
(38) Steiner, S.; Wolf, J.; Glatzel, S.; Andreou, A.; Granda, J. M.; Keenan, G.; Hinkley, T.; Aragon-Camarasa, G.; Kitson, P. J.; Angelone, D.; et al. Organic synthesis in a modular robotic system driven by a chemical programming language. Science 2019, 363, No. eaav2211.
(39) Kitson, P. J.; Marie, G.; Francoia, J.-P.; Zalesskiy, S. S.; Sigerson, R. C.; Mathieson, J. S.; Cronin, L. Digitization of multistep organic synthesis in reactionware for on-demand pharmaceuticals. Science 2018, 359, 314-319.
(40) Dai, T.; Vijayakrishnan, S.; Szczypiński, F. T.; Ayme, J.-F.; Simaei, E.; Fellowes, T.; Clowes, R.; Kotopanov, L.; Shields, C. E.; Zhou, Z.; et al. Autonomous mobile robots for exploratory synthetic chemistry. Nature 2024, 635, 890-897.
(41) Burger, B.; Maffettone, P. M.; Gusev, V. V.; Aitchison, C. M.; Bai, Y.; Wang, X.; Li, X.; Alston, B. M.; Li, B.; Clowes, R.; et al. A mobile robotic chemist. Nature 2020, 583, 237-241.
(42) Xu, H.; Zhang, D.; Mo, F. High-throughput automated platform for thin layer chromatography analysis. STAR Protoc 2022, 3, 101893.
(43) Torres, J. A. G.; Lau, S. H.; Anchuri, P.; Stevens, J. M.; Tabora, J. E.; Li, J.; Borovika, A.; Adams, R. P.; Doyle, A. G. A multi-objective active learning platform and web app for reaction optimization. J. Am. Chem. Soc. 2022, 144, 19999-20007.
(44) Mansouri, K.; Grulke, C. M.; Judson, R. S.; Williams, A. J. OPERA models for predicting physicochemical properties and environmental fate endpoints. J. Cheminform. 2018, 10, 10.
(45) Ruttkies, C.; Schymanski, E. L.; Wolf, S.; Hollender, J.; Neumann, S. MetFrag relaunched: incorporating strategies beyond in silico fragmentation. J. Cheminform. 2016, 8, 3.
(46) Stanstrup, J.; Neumann, S.; Vrhovsek, U. PredRet: prediction of retention time by direct mapping between multiple chromatographic systems. Anal. Chem. 2015, 87, 9421-9428.
(47) Stienstra, C. M.; Nazdrajic, E.; Hopkins, W. S. From Reverse Phase Chromatography to HILIC: Graph Transformers Power Method-Independent Machine Learning of Retention Times. Anal. Chem. 2025, 97, 4461-4472.
(48) Zhang, Y.; Liu, F.; Li, X. Q.; Gao, Y.; Li, K. C.; Zhang, Q. H. Retention time dataset for heterogeneous molecules in reversed-phase liquid chromatography. Sci. Data 2024, 11, 946.
(49) Plachka, K.; Pilarova, V.; Gazárková, T.; Svec, F.; Garrigues, J.-C.; Nováková, L. Advancing Fundamental Understanding of Retention Interactions in Supercritical Fluid Chromatography Using Artificial Neural Networks: Polar Stationary Phases with-OH Moieties. Anal. Chem. 2024, 96, 12748-12759.
CAS BIOFINDER DISCOVERY PLATFORM™
CAS生物发现者发现平台™
BRIDGE BIOLOGY AND CHEMISTRY FOR FASTER ANSWERS
打通生物学与化学,更快得出答案
Analyze target relationships, compound effects, and disease pathways
分析目标关系、化合物效应和疾病途径
Explore the platform
探索该平台
CAS
(50) Plachka, K.; Pilarova, V.; Gazárková, T.; Svec, F.; Garrigues, J.-C.; Nováková, L. AI-Enhanced Understanding of Retention Interactions in Supercritical Fluid Chromatography: Neural Network Insights into Retention on Selected Non-Polar Stationary Phases. Anal. Chem. 2025, 97, 2164-2175.
(51) MacKnight, R.; Boiko, D. A.; Regio, J. E.; Gallegos, L. C.; Neukomm, T. A.; Gomes, G. Rethinking chemical research in the age of large language models. Nat. Comput. Sci. 2025, 5, 715.
(52) Jablonka, K. M.; Schwaller, P.; Ortega-Guerrero, A.; Smit, B. Leveraging large language models for predictive chemistry. Nat. Mach. Intell. 2024, 6, 161-169.
(53) Bran, A. M.; Cox, S.; Schilter, O.; Baldassari, C.; White, A. D.; Schwaller, P. Augmenting large language models with chemistry tools. Nat. Mach. Intell. 2024, 6, 525-535.
(54) Boiko, D. A.; MacKnight, R.; Kline, B.; Gomes, G. Autonomous chemical research with large language models. Nature 2023, 624, 570- 578.
(55) Zheng, Z.; Rampal, N.; Inizan, T. J.; Borgs, C.; Chayes, J. T.; Yaghi, O. M. Large language models for reticular chemistry. Nat. Rev. Mater. 2025, 10, 369-381.