Infrared Spectra Prediction for Functional Group Region Utilizing a Machine Learning Approach with Structural Neighboring Mechanism
英文原文与中文译文逐段对照 · English original with Chinese translation
Chengchun Liu, Ruqiang Zou, and Fanyang Mo*
刘丞军、邹如强、莫凡洋*
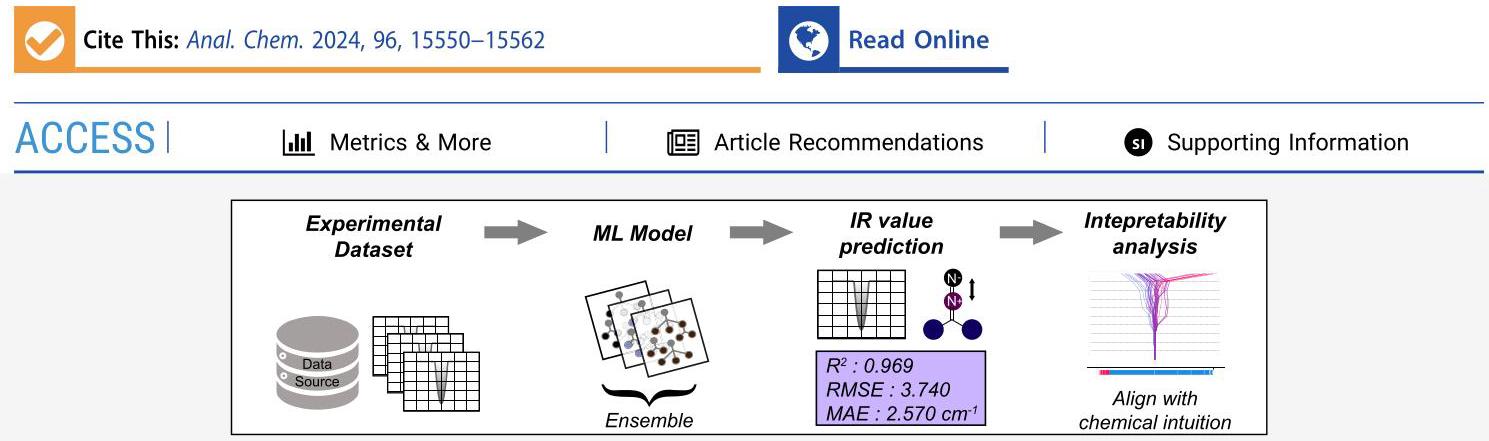
ABSTRACT: Infrared (IR) spectroscopy is a pivotal technique in chemical research for elucidating molecular structures and dynamics through vibrational and rotational transitions. However, the intricate molecular fingerprints characterized by unique vibrational and rotational patterns present substantial analytical challenges. Here, we present a machine learning approach employing a structural neighboring mechanism tailored to enhance the prediction and interpretation of infrared spectra. Our model distinguishes itself by honing in on chemical information proximal to functional groups, thereby significantly bolstering the accuracy, robustness, and interpretability of spectral predictions. This method not only demystifies the correlations between infrared spectral features and molecular structures but also offers a scalable and efficient paradigm for dissecting complex molecular interactions.
摘要:红外(IR)光谱是化学研究中的一项关键技术,可通过振动和转动跃迁来阐明分子结构和动力学。然而,由独特的振动和转动模式所表征的复杂分子指纹带来了巨大的分析挑战。在此,我们提出一种采用结构邻域机制的机器学习方法,旨在增强红外光谱的预测和解释。我们的模型通过聚焦于官能团附近的化学信息而脱颖而出,从而显著提高了光谱预测的准确性、稳健性和可解释性。该方法不仅揭示了红外光谱特征与分子结构之间的相关性,还为剖析复杂分子相互作用提供了一种可扩展且高效的范例。
I INTRODUCTION
I 引言
Infrared (IR) spectroscopy offers an expansive array of chemical insights, functioning akin to a molecular fingerprint, and provides substantial support for the elucidation of molecular properties. ${}^{1}$ Despite the foundational insights afforded by theoretical frameworks and empirical knowledge, the intricate process of structure identification requires the examination of tabular data and comparison with existing databases. ${}^{2,3}$ A notable advantage of machine learning (ML) algorithms is their ability to identify complex correlations hidden within large data sets, thus enabling the construction of models capable of predicting outcomes previously unknown ${}^{4}$ (Figure 1).
红外(IR)光谱提供了广泛的化学见解,其作用类似于分子指纹,并为阐明分子性质提供了重要支持。${}^{1}$ 尽管理论框架和经验知识提供了基础见解,但结构识别的复杂过程需要检查表格数据并与现有数据库进行比较。${}^{2,3}$ 机器学习(ML)算法的一个显著优势是它们能够识别隐藏在大数据集中的复杂相关性,从而能够构建能够预测以前未知结果的模型 ${}^{4}$(图1)。
The fusion of machine learning techniques with IR spectroscopy for the elucidation of structure-property relationships within molecules represents a critical area of research. Wang et al. introduced a neural network model capable of predicting IR spectra using Morgan fingerprints as input, utilizing earth mover’s distance (EMD) for metric and loss function purposes. ${}^{5}$ However, despite the computational efficiency of bit-vectors produced by Morgan fingerprints, their direct interpretation by human researchers is challenging, highlighting a gap in intuitive interpretability and the extraction of specific chemical information or structural insights.
将机器学习技术与红外光谱相结合以阐明分子内的结构 - 性质关系是一个关键的研究领域。Wang等人引入了一种神经网络模型,该模型能够使用摩根指纹作为输入来预测红外光谱,并将推土机距离(EMD)用于度量和损失函数。${}^{5}$ 然而,尽管摩根指纹产生的位向量具有计算效率,但人类研究人员对其进行直接解释具有挑战性,这突出了直观可解释性以及提取特定化学信息或结构见解方面的差距。
Molecular feature engineering is identified as a crucial approach for integrating existing chemical knowledge into descriptors, thereby enhancing the descriptive capability and facilitating pattern recognition within the data set. ${}^{6 - 8}$ Recent work by Marquetand et al. has considerably enhanced the accuracy and efficiency of molecular IR spectra predictions by merging ab initio molecular dynamics (AIMD) with neural network models. This integration shows promise for a wide range of molecules, particularly in simulating peptide dynamics, illustrating the potential of these techniques across diverse molecular systems. ${}^{9}$ Schütte et al. highlighted the potential of neural networks to accelerate IR spectrum predictions. SchNetPack 2.0, based on PyTorch, offers tools for molecular dynamics simulations, including infrared and Raman spectra calculations. It computes essential spectra such as the power spectrum, IR spectrum, and Raman spectrum by Fourier transforming the time autocorrelation functions of momentum, dipole moment, and polarizability data, respectively. Accessible through the md.data.spectra module, SchNetPack 2.0 enhances spectral prediction efficiency and accuracy, advancing neural networks’ role in computational spectroscopy. ${}^{10}$ FieldSchNet leverages learned radial interaction functions to improve atomic representation in simulations. ${}^{11}$ Concurrently, the field-induced recursively embedded atom neural network (FIREANN) exemplifies advancements in estimating IR spectra by calculating molecular potential energies and dipole moments. FIREANN introduces a field-dependent feature in the atomic environment description, allowing simultaneous prediction of energy variations and response properties under external fields. ${}^{12}$ Jiang et al. have developed a novel machine learning protocol for the rapid prediction of amide I IR spectra of proteins, achieving a high degree of alignment with experimental data and surpassing traditional quantum mechanical calculation methods. ${}^{13}$ Additionally, Jiang et al. have introduced a machine learning approach that accurately predicts IR and Raman vibrational spectra from molecular structures, significantly reducing computational costs compared to conventional methods. ${}^{14}$
分子特征工程被认为是将现有化学知识整合到描述符中的关键方法,从而增强描述能力并促进数据集中的模式识别。${}^{6 - 8}$ Marquetand等人最近的工作通过将从头算分子动力学(AIMD)与神经网络模型相结合,大大提高了分子红外光谱预测的准确性和效率。这种整合在广泛的分子中显示出前景,特别是在模拟肽动力学方面,说明了这些技术在不同分子系统中的潜力。${}^{9}$ Schütte等人强调了神经网络在加速红外光谱预测方面的潜力。基于PyTorch的SchNetPack 2.0提供了分子动力学模拟工具,包括红外和拉曼光谱计算。它分别通过对动量、偶极矩和极化率数据的时间自相关函数进行傅里叶变换来计算诸如功率谱、红外光谱和拉曼光谱等基本光谱。通过md.data.spectra模块可访问,SchNetPack 2.0提高了光谱预测效率和准确性,推动了神经网络在计算光谱学中的作用。${}^{10}$ FieldSchNet利用学习到的径向相互作用函数来改善模拟中的原子表示。${}^{11}$ 同时,场诱导递归嵌入原子神经网络(FIREANN)通过计算分子势能和偶极矩,例证了在估计红外光谱方面的进展。FIREANN在原子环境描述中引入了场依赖特征,允许同时预测外部场下的能量变化和响应特性。${}^{12}$ Jiang等人开发了一种用于快速预测蛋白质酰胺I红外光谱的新型机器学习协议,与实验数据实现了高度匹配,并超越了传统量子力学计算方法。${}^{13}$ 此外,Jiang等人引入了一种机器学习方法,该方法能够从分子结构准确预测红外和拉曼振动光谱,与传统方法相比显著降低了计算成本。${}^{14}$
Received: April 16, 2024
收到日期:2024年4月16日
Revised: September 3, 2024
修订日期:2024年9月3日
Accepted: September 8, 2024
接受日期:2024年9月8日
Published: September 19, 2024
发表日期:2024年9月19日
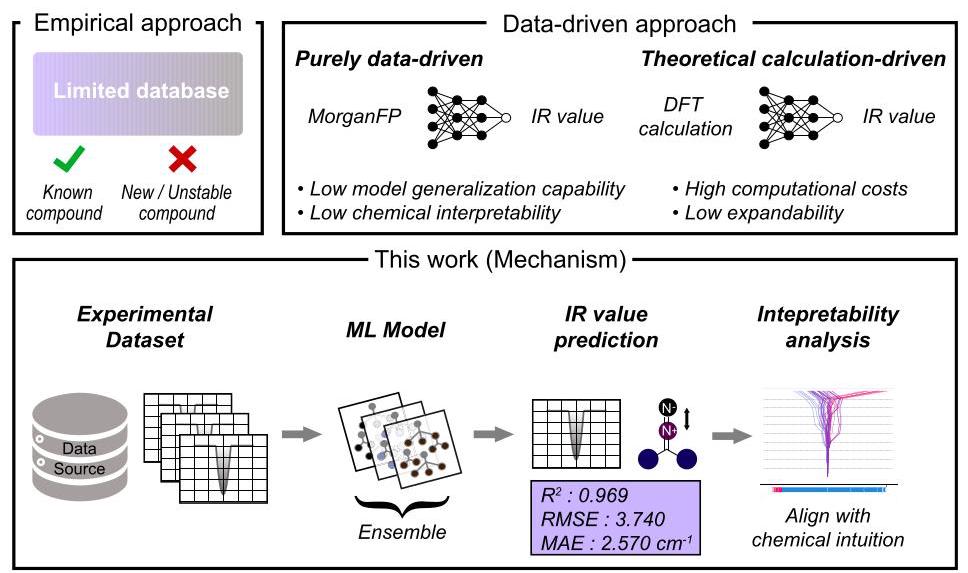
Figure 1. An overview of the study’s integrated approach to IR value prediction, contrasting empirical, purely data-driven, and theoretical methods.
图1. 该研究用于红外值预测的综合方法概述,对比了经验方法、纯数据驱动方法和理论方法。
Nevertheless, the scalability of models based on theoretically calculated molecular descriptors remains limited by their extensive computational requirements, ${}^{15}$ underscoring the need for the development of cost-effective, highly predictive, and transferable methodologies. Empirical evidence indicates that the IR absorption values of functional groups are predominantly influenced by adjacent atoms and bonds. ${}^{16}$ Here, we introduce a knowledge-embedding approach, termed the structural neighboring mechanism (SNM), applied to the functional group region of IR spectra. This method discerns key structural fragments that highlight chemical information proximate to the functional groups, quantified as types and numbers, forming the basis for structural neighboring mechanism-based descriptors (SNMD). The SNMD-equipped ML model demonstrates exceptional proficiency in predicting the IR characteristic absorption peaks of functional groups, closely aligning with experimental observations. Crucially, the model’s interpretability is aligned with chemical intuition, enabling predictions about IR signals of functional groups and elucidating the impact of molecular fine structure on these signals.
然而,基于理论计算分子描述符的模型的可扩展性仍然受到其广泛计算需求的限制,${}^{15}$ 这突出了开发具有成本效益、高度预测性和可转移性方法的必要性。经验证据表明,官能团的红外吸收值主要受相邻原子和键的影响。${}^{16}$ 在这里,我们引入一种知识嵌入方法,称为结构邻域机制(SNM),应用于红外光谱的官能团区域。该方法识别突出官能团附近化学信息的关键结构片段,以类型和数量进行量化,形成基于结构邻域机制的描述符(SNMD)的基础。配备SNMD的ML模型在预测官能团的红外特征吸收峰方面表现出卓越的能力,与实验观察结果紧密匹配。至关重要的是,该模型的可解释性与化学直觉一致,能够预测官能团的红外信号,并阐明分子精细结构对这些信号的影响。
METHOD SECTION
方法部分
Featurization of Molecular Structure by Structural Neighboring Mechanism. SMILES Parsing and Hydrogen
通过结构邻域机制对分子结构进行特征化处理。SMILES解析与氢原子添加
Addition. The SMILES string $S$ is parsed to generate the molecular structure $M$ , followed by hydrogen addition:
将SMILES字符串$S$解析以生成分子结构$M$,随后进行氢原子添加:
$$ M = \text{ Chem. MolFromSmiles }\left( S\right) \tag{1} $$$$ M = \text{ Chem. AddHs }\left( M\right) \tag{2} $$Functional Group Identification.
官能团识别。
Carbonyl Group: The target carbon ${C}_{\text{ target }}$ is identified by locating a carbon atom double-bonded to oxygen ${O}_{\text{ target }}$ :
羰基:通过定位与氧原子${O}_{\text{ target }}$双键相连的碳原子${C}_{\text{ target }}$来识别目标碳:
Diazo Group: The target nitrogen ${N}^{ + }$ is identified by locating a nitrogen with a formal positive charge:
重氮基:通过定位带有形式正电荷的氮原子来识别目标氮${N}^{ + }$:
Neighboring Atom Identification. Neighboring atoms of ${C}_{\text{ target }}$ are identified, excluding ${O}_{\text{ target }}$ or ${N}^{ + }$ , and sorted by atomic number and predefined priority order:
邻域原子识别。识别${C}_{\text{ target }}$的邻域原子,排除${O}_{\text{ target }}$或${N}^{ + }$,并按原子序数和预定义的优先级顺序排序:
$$ {N}_{{C}_{\text{ target }}} = \left\{ {N \in \text{ neighbors }\left( {C}_{\text{ target }}\right) \mid N \neq {O}_{\text{ target }}\text{ or }{N}^{ + }}\right\} \tag{7} $$$$ {N}_{\text{ sorted }} = \operatorname{sort}\left( {{N}_{{C}_{\text{ target }}},}\right. \text{ key } = \text{ atomic\_number, reverse } $$$$ = \text{ True) } \tag{8} $$$$ {N}_{\text{ priority\_sorted }} = \operatorname{sort}\left( {{N}_{\text{ sorted }},\text{ key } = \min \left( \text{ priority\_order }\right) }\right) $$(9)
$$ {R}_{1},{R}_{2} = {N}_{\text{ priority\_sorted }}\left\lbrack 0\right\rbrack ,{N}_{\text{ priority\_sorted }}\left\lbrack 1\right\rbrack \tag{10} $$Feature Extraction. Morgan Fingerprint. The Morgan fingerprint is computed to represent molecular features:
特征提取。摩根指纹。计算摩根指纹以表示分子特征:
$$ {FP} = \text{ AllChem.GetMorganFingerprintAsBitVect }(M\text{ , } $$$$ \text{ radius } = 2\text{ , nBits } = {2048}\text{ ) } \tag{11} $$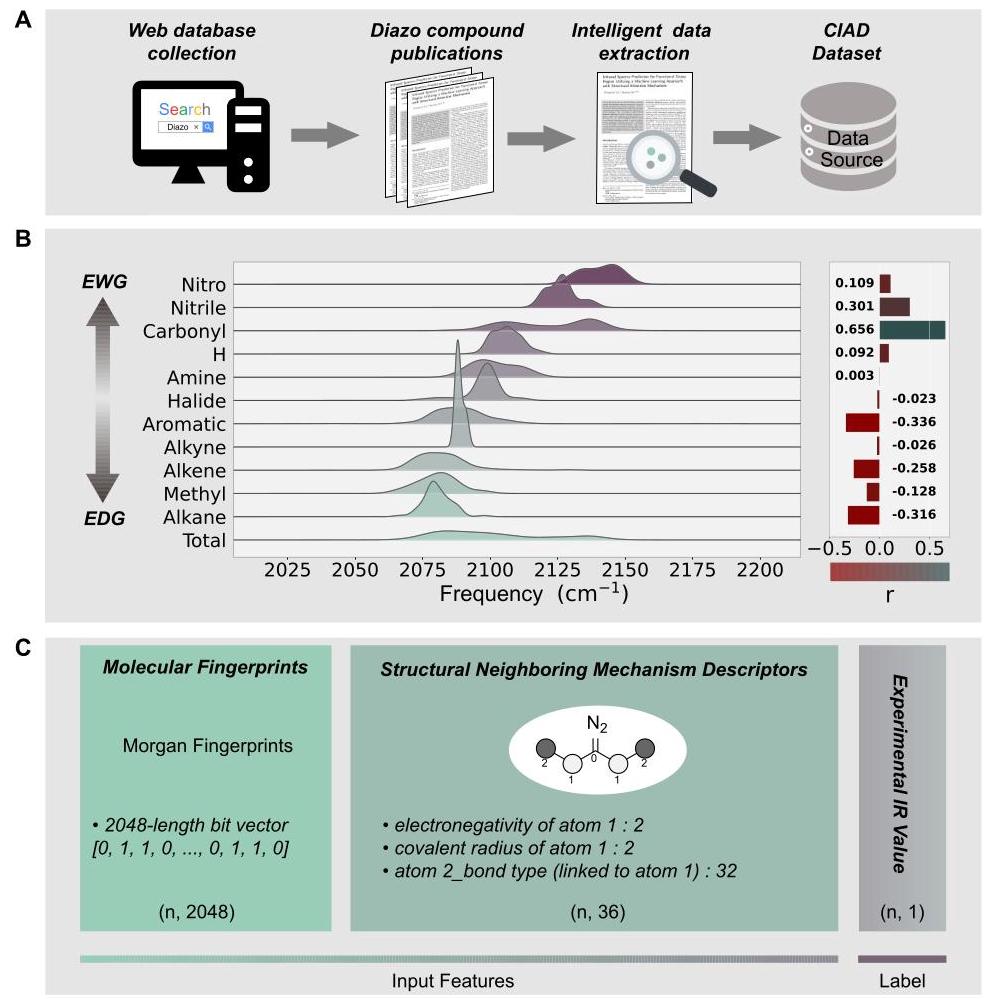
Figure 2. Data acquisition and analysis of diazo compounds. (A) Data retrieval flow from web search to CIAD data set formation using intelligent extraction. (B) CIAD data set spectral data display. (C) Machine learning input features: Morgan fingerprints and structural neighboring mechanism descriptors, with IR values as the target.
图2. 重氮化合物的数据采集与分析。(A) 从网络搜索到使用智能提取形成CIAD数据集的数据检索流程。(B) CIAD数据集光谱数据显示。(C) 机器学习输入特征:摩根指纹和结构邻域机制描述符,以红外值作为目标。
Feature Engineering. A feature dictionary is constructed and updated based on ${R}_{1}$ ’s and ${R}_{2}$ ’s connections. Additional features include electronegativity $\left( E\right)$ , covalent radius $\left( {R}_{c}\right)$ , and atomic numbers $\left( Z\right)$ :
特征工程。基于${R}_{1}$和${R}_{2}$的连接构建并更新特征字典。其他特征包括电负性$\left( E\right)$、共价半径$\left( {R}_{c}\right)$和原子序数$\left( Z\right)$:
$$ \text{ counts }\left\lbrack {f,\{ A{\} }_{{B}_{\text{ suffix }}}^{\prime }}\right\rbrack + = 1 \tag{12} $$$$ {Z}_{{R}_{1}} = \text{ atomic\_number\_dict }\left\lbrack {R}_{1}\right\rbrack \tag{13} $$$$ {Z}_{{R}_{2}} = \text{ atomic\_number\_dict }\left\lbrack {R}_{2}\right\rbrack \tag{14} $$$$ {E}_{{R}_{1}} = \text{ electronegativity\_dict }\left\lbrack {Z}_{{R}_{1}}\right\rbrack \tag{15} $$$$ {E}_{{R}_{2}} = \text{ electronegativity\_dict }\left\lbrack {Z}_{{R}_{2}}\right\rbrack \tag{16} $$$$ {R}_{{c}_{{R}_{1}}} = \text{ covalent\_radius\_dict }\left\lbrack {Z}_{{R}_{1}}\right\rbrack \tag{17} $$$$ {R}_{{c}_{{R}_{2}}} = \text{ covalent\_radius\_dict }\left\lbrack {Z}_{{R}_{2}}\right\rbrack \tag{18} $$This method systematically captures and quantifies molecular structural characteristics, facilitating subsequent analysis and machine learning applications.
该方法系统地捕获并量化分子结构特征,便于后续分析和机器学习应用。
Computational Chemistry Experiments. The second subsection details our computational chemistry experiments, which employ Density Functional Theory (DFT) and Gaussian simulations. The key elements of this section are
计算化学实验。第二小节详细介绍了我们的计算化学实验,这些实验采用密度泛函理论(DFT)和高斯模拟。本节的关键要素是
Optimization and frequency calculations performed using Gaussian software (Gaussian 16) to determine the most stable conformers and their corresponding energy states of diazo compounds.
使用高斯软件(高斯16)进行优化和频率计算,以确定重氮化合物最稳定的构象及其相应的能量状态.
The application of a vibrational frequency scaling factor of 0.951 , as determined from data in the CCCBDB, to adjust calculated frequencies for better agreement with experimental data.
应用根据CCCBDB中的数据确定的振动频率缩放因子0.951来调整计算频率,以使其与实验数据更好地吻合。
RESULTS AND DISCUSSION
结果与讨论
Data Set Construction and Feature Engineering. This research compiled a data set of 1,827 diazo compounds. The compounds were characterized by their molecular structures using Simplified Molecular Input Line Entry System (SMILES) notations and their infrared absorption spectra obtained from experimental measurements (Figure 2A). The methodology was based on experimental observation, avoiding the use of theoretical models in favor of direct empirical evidence. This data set was extracted from 297 scholarly articles using a regular expression-based method for intelligent text retrieval. The methodology is outlined in Figure S1, with a comprehensive overview of the CIAD data set provided in Figure S2.
数据集构建与特征工程。本研究汇编了一个包含1827种重氮化合物的数据集。这些化合物通过简化分子输入线性输入系统(SMILES)符号表征其分子结构,并通过实验测量获得其红外吸收光谱(图2A)。该方法基于实验观察,避免使用理论模型,而倾向于直接的经验证据。这个数据集是使用基于正则表达式的智能文本检索方法从297篇学术文章中提取的。该方法在图S1中概述,图S2提供了CIAD数据集的全面概述。
To ensure comprehensive data set representation, we included diazo groups with various chemical substituents. Electron-withdrawing groups (EWGs) significantly elevate the infrared frequency associated with the diazo groups, while electron-donating groups (EDGs) lower it. These shifts are quantitatively analyzed using Pearson correlation coefficients (r). Figure 2B illustrates the distribution of infrared absorption frequencies for diazo groups with different substituents. The right panel displays the Pearson correlation coefficients, highlighting the strength and direction of the relationship between the substituents’ electronic nature and the infrared frequency shifts. Positive $r$ values indicate that EWGs increase the frequency, while negative $r$ values show that EDGs decrease it. The electronic nature of substituent groups influences their electron-donating or electron-withdrawing capabilities relative to the diazo group. EWGs, such as nitro and nitrile, increase vibrational frequencies by withdrawing electrons. In contrast, EDGs, such as alkyl groups, decrease vibrational frequencies by donating electrons. The data set covers the absorption frequency of diazo groups in the infrared spectrum, ranging from 2000 to ${2200}{\mathrm{\;{cm}}}^{-1}$ . The analysis employed two types of descriptors: the Structural Neighboring Mechanism-based Descriptor (SNMD) and the 2048-bit Morgan Fingerprint (MorganFP), which is derived from the SMILES sequences of the molecules (Figure 2C). Here, the tensor shapes are indicated as $\left( {\mathrm{n},\mathrm{x}}\right)$ , where $\mathrm{n}$ denotes the total number of training data points. The label shape $\left( {\mathrm{n},1}\right)$ signifies that the model predicts the IR frequencies. The SNMD is divided into two components. The first component assesses the electronegativity and covalent radius of the atom directly bonded to the diazo group. The second component considers the atoms and various bond types bonded to this first atom, including nonmetallic and metalloid elements such as I, Br, Cl, S, P, Si, F, O, C, N, B, and H, and single, double, triple, and aromatic bonds. After eliminating combinations that were deemed implausible under valence bond theory, we identified a total of 36 viable combinations, which were numerically encoded for analysis. The statistical analysis of the SNMD is provided in Table S1. The final data set consisted of 2,084 descriptors, which were normalized before being used in model development.
为确保数据集的全面代表性,我们纳入了具有各种化学取代基的重氮基团。吸电子基团(EWG)显著提高与重氮基团相关的红外频率,而供电子基团(EDG)则降低该频率。使用皮尔逊相关系数(r)对这些位移进行定量分析。图2B说明了具有不同取代基的重氮基团的红外吸收频率分布。右图显示了皮尔逊相关系数,突出了取代基电子性质与红外频率位移之间关系的强度和方向。正的$r$值表明EWG增加频率,而负的$r$值表明EDG降低频率。取代基的电子性质影响其相对于重氮基团的供电子或吸电子能力。EWG,如硝基和腈基,通过吸电子增加振动频率。相比之下,EDG,如烷基,通过供电子降低振动频率。该数据集涵盖了红外光谱中重氮基团的吸收频率,范围从2000到${2200}{\mathrm{\;{cm}}}^{-1}$。分析采用了两种类型的描述符:基于结构邻域机制的描述符(SNMD)和2048位摩根指纹(MorganFP),它是从分子的SMILES序列派生而来的(图2C)。这里,张量形状表示为$\left( {\mathrm{n},\mathrm{x}}\right)$,其中$\mathrm{n}$表示训练数据点的总数。标签形状$\left( {\mathrm{n},1}\right)$表示模型预测红外频率。SNMD分为两个部分。第一部分评估直接与重氮基团键合的原子的电负性和共价半径。第二部分考虑与该第一个原子键合的原子和各种键类型,包括非金属和类金属元素,如I、Br、Cl、S、P、Si、F、O、C、N、B和H,以及单键、双键、三键和芳香键。在消除根据价键理论被认为不合理的组合后,我们总共确定了36种可行的组合,并对其进行数字编码以进行分析。SNMD的统计分析见表S1。最终数据集由2084个描述符组成,在用于模型开发之前进行了归一化处理。
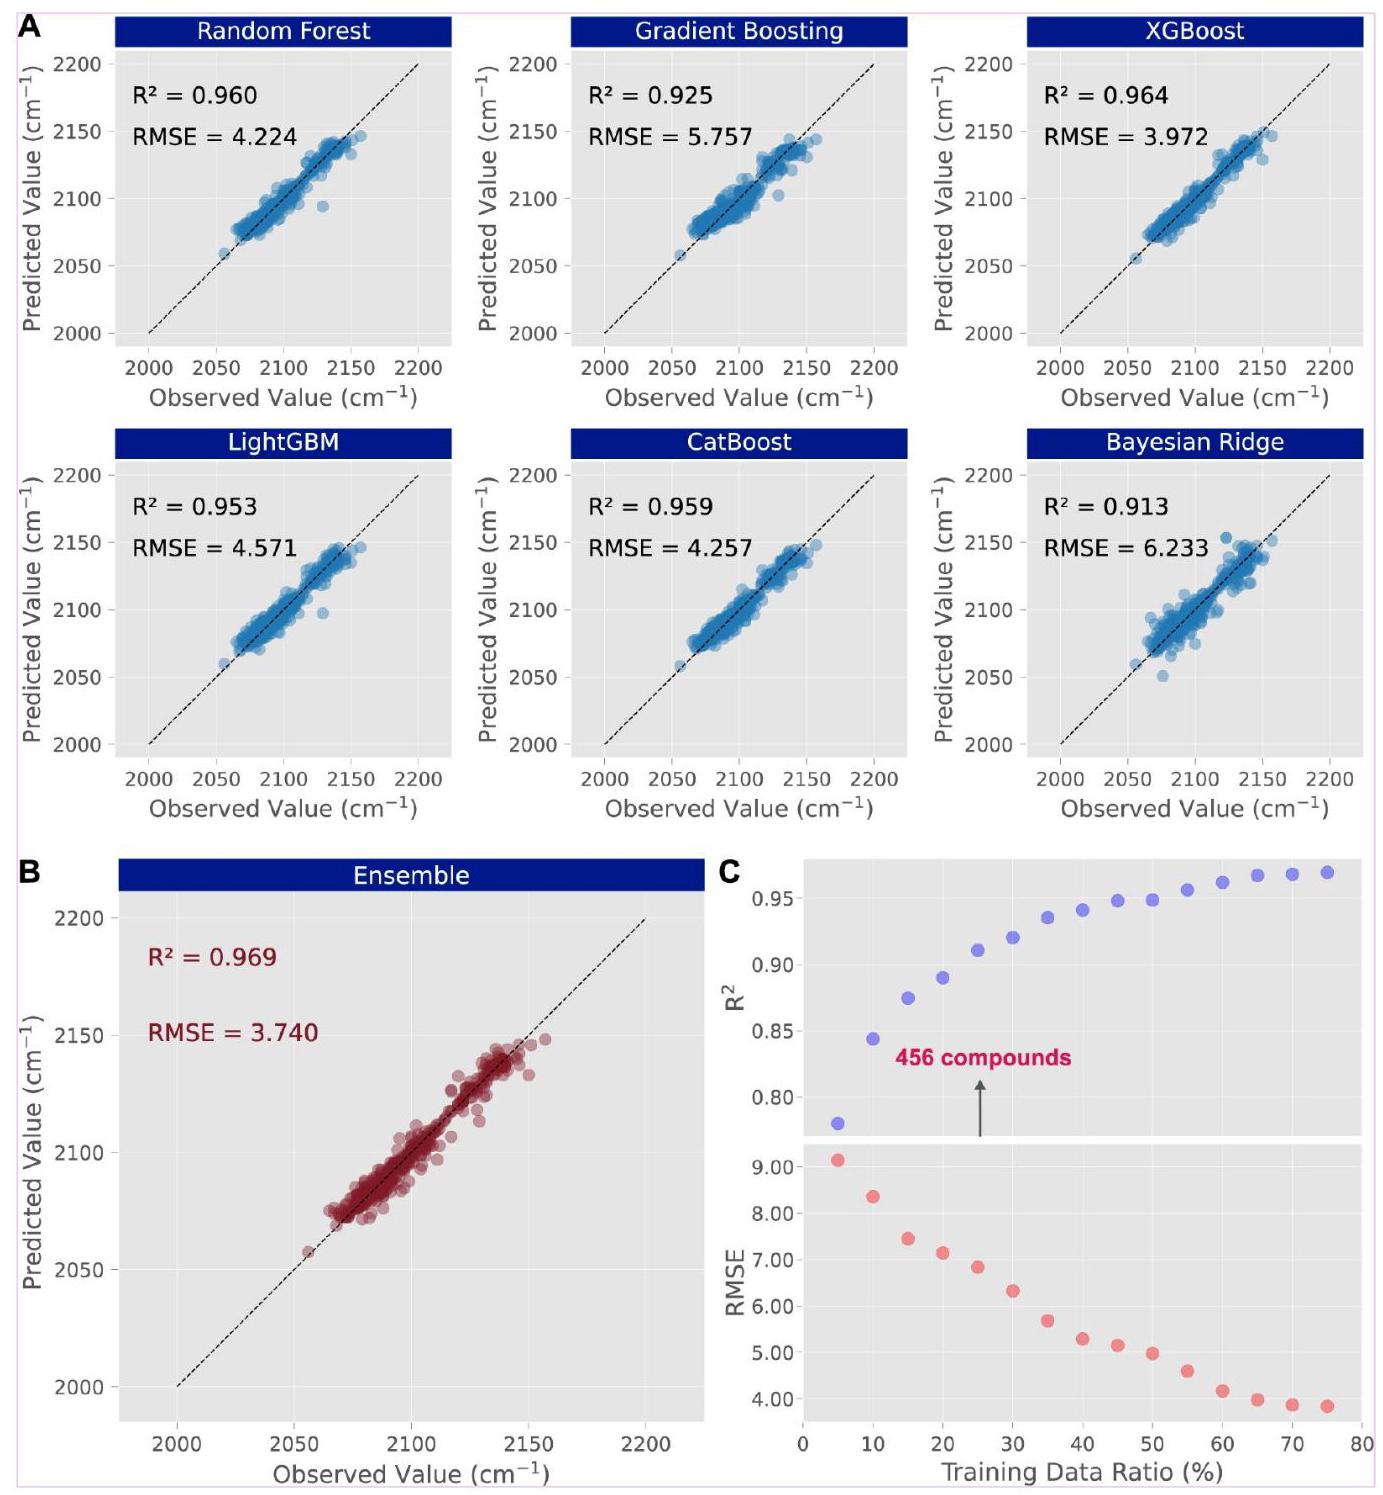
Figure 3. Quantitative assessment of predictive model performance. (A) A comparison of different machine learning algorithms. (B) Ensemble model that combines the strengths of different machine learning algorithms. (C) A learning curve that quantitatively details the evolution of the model’s coefficient of determination $\left( {R}^{2}\right)$ and root-mean-square error (RMSE) metrics, which depend on incremental expansion of the training. data set size.
图3.预测模型性能的定量评估。(A)不同机器学习算法的比较。(B)结合不同机器学习算法优势的集成模型。(C)一条学习曲线,定量详细说明了模型的决定系数$\left( {R}^{2}\right)$和均方根误差(RMSE)指标的演变,这取决于训练数据集大小的增量扩展。
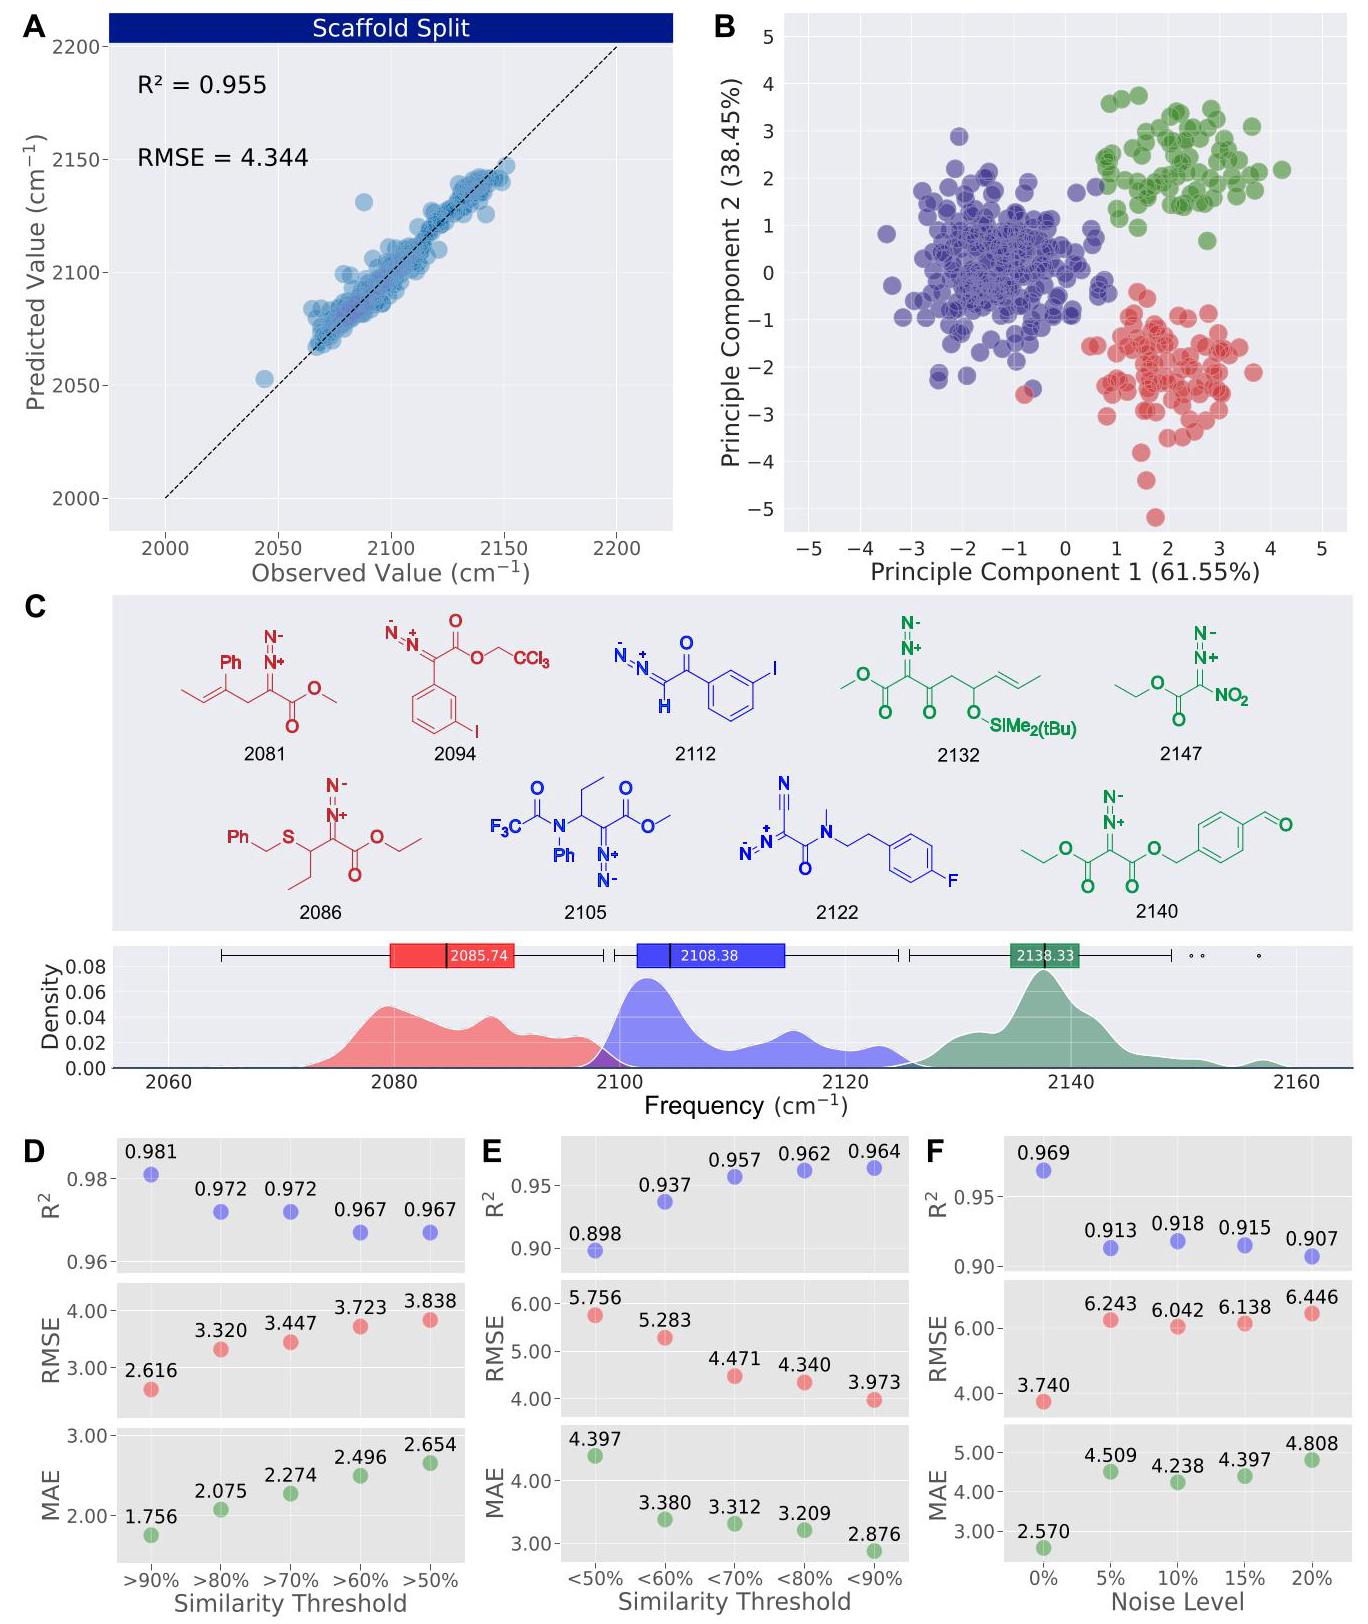
Figure 4. Assessing model robustness and generalization via structural clustering and IR spectroscopy. (A) Performance with scaffold-based data splitting. (B) DBSCAN clustering with $\epsilon = {0.001}$ and minPts $= {50}$ ; clusters visualized by PCA (green, blue, red). (C) Density distribution of IR absorption values categorized into high (green), medium (blue), and low (red) frequency regions, accompanied by random molecular examples for each frequency range. (D) Model performance across high similarity thresholds (>50% to >90%). (E) Model performance across lower similarity thresholds (<90% to <50%). (F) Sensitivity to artificial noise levels (0% to 20%).
图4.通过结构聚类和红外光谱评估模型的稳健性和泛化能力。(A)基于支架的数据分割的性能。(B)具有$\epsilon = {0.001}$和最小点数$= {50}$的DBSCAN聚类;通过主成分分析(PCA)可视化聚类(绿色、蓝色、红色)。(C)分为高(绿色)、中(蓝色)和低(红色)频率区域的红外吸收值的密度分布,以及每个频率范围的随机分子示例。(D)跨越高相似性阈值(>50%至>90%)的模型性能。(E)跨越较低相似性阈值(<90%至<50%)的模型性能。(F)对人工噪声水平(0%至20%)的敏感性。
Model Construction and Performance Evaluation. In this study, the Characteristic Infrared Absorption Frequency of the Diazo group (CLAD) data set was partitioned into a training set comprising 75% of the data and a test set comprising the remaining 25%, utilizing a random allocation method. The predictive performance of the models was rigorously evaluated through cross-validation, followed by evaluation on the test set. This study presents a comprehensive assessment of several leading machine learning algorithms, including Random Forest (RF), LightGBM (LGB), XGBoost (XGB), Bayesian Ridge Regression (BRR), Gradient Boosting (GB), and CatBoost (CB). Two key performance metrics, the coefficient of determination $\left( {R}^{2}\right)$ and the root-mean-square error (RMSE), are employed to assess the accuracy and efficiency of the derived models. These metrics provide a comprehensive evaluation of the models’ predictive accuracy and their capacity to generalize to unseen data. The quantitative mathematical formulas are as follows:
模型构建与性能评估。在本研究中,利用随机分配方法将重氮基团特征红外吸收频率(CLAD)数据集划分为一个包含75%数据的训练集和一个包含其余25%数据的测试集。通过交叉验证对模型的预测性能进行了严格评估,随后在测试集上进行评估。本研究对几种领先的机器学习算法进行了全面评估,包括随机森林(RF)、LightGBM(LGB)、XGBoost(XGB)、贝叶斯岭回归(BRR)、梯度提升(GB)和CatBoost(CB)。采用两个关键性能指标,即决定系数$\left( {R}^{2}\right)$和均方根误差(RMSE),来评估所推导模型的准确性和效率。这些指标对模型的预测准确性及其对未见数据的泛化能力进行了全面评估。定量数学公式如下:
$$ {R}^{2} = 1 - \frac{\mathop{\sum }\limits_{{i = 1}}^{n}{\left( {y}_{i} - {\widehat{y}}_{i}\right) }^{2}}{\mathop{\sum }\limits_{{i = 1}}^{n}{\left( {y}_{i} - \bar{y}\right) }^{2}} \tag{19} $$$$ \text{ RMSE } = \sqrt{\frac{1}{n}\mathop{\sum }\limits_{{i = 1}}^{n}{\left( {y}_{i} - {\widehat{y}}_{i}\right) }^{2}} \tag{20} $$where ${y}_{i}$ represents the observed values, ${\widehat{y}}_{i}$ denotes the predicted values, $\bar{y}$ is the mean of the observed values, and $n$ is the number of observations. The study found that decision tree-based algorithms, specifically RF, LGB, XGB, and CB, had superior predictive abilities with ${R}^{2}$ scores exceeding 0.95 (Figure 3A). Exclusively depending on Morgan fingerprints (MorganFP), derived from 2-dimensional structural data, led to a notable decline in predictive performance, as elaborated in Figure S3. These observations underscore the efficacy of the structure neighboring mechanism (SNM) in feature extraction, particularly in encapsulating essential chemical descriptors crucial for elucidating the spectral absorption characteristics of molecular moieties.
其中${y}_{i}$代表观测值,${\widehat{y}}_{i}$表示预测值,$\bar{y}$是观测值的均值,$n$是观测次数。研究发现,基于决策树的算法,特别是随机森林(RF)、轻量级梯度提升机(LGB)、极端梯度提升(XGB)和CatBoost(CB),具有卓越的预测能力,${R}^{2}$分数超过0.95(图3A)。如在图S3中所阐述的,仅依赖于从二维结构数据派生的摩根指纹(MorganFP)会导致预测性能显著下降。这些观察结果强调了结构邻域机制(SNM)在特征提取中的有效性,特别是在封装对于阐明分子部分的光谱吸收特性至关重要的基本化学描述符方面。
To enhance the predictive accuracy of our model, we employed ensemble learning methods, leading to the creation of a robust ensemble model. This model integrates the strengths of various machine learning algorithms through a superposition approach in ensemble learning. Specifically, we used multiple regression models-Random Forest (RF), Gradient Boosting (GB), CatBoost (CB), LightGBM (LGB), and XGBoost (XGB)-as the base models, and Bayesian Ridge regression as the meta-model. This approach mitigates overfitting through regularization, enhancing overall prediction accuracy and robustness. Figure S4 and Table S2 present an ablation study examining the influence of each base model on the ensemble model. The ensemble model achieved a high test ${R}^{2}$ score of 0.969 and an RMSE of 3.740 (Figure 3B). This marked performance improvement over individual models underscores the complex and nonlinear nature of the descriptors employed to predict peaks in the signature groups of the infrared spectrum.
为了提高我们模型的预测准确性,我们采用了集成学习方法,从而创建了一个强大的集成模型。该模型通过集成学习中的叠加方法整合了各种机器学习算法的优势。具体而言,我们使用多个回归模型——随机森林(RF)、梯度提升(GB)、CatBoost(CB)、LightGBM(LGB)和XGBoost(XGB)——作为基础模型,以及贝叶斯岭回归作为元模型。这种方法通过正则化减轻了过拟合,提高了整体预测准确性和鲁棒性。图S4和表S2展示了一项消融研究,考察了每个基础模型对集成模型的影响。集成模型实现了0.969的高测试${R}^{2}$分数和3.740的RMSE(图3B)。与单个模型相比,这种显著的性能提升强调了用于预测红外光谱特征基团中峰的描述符的复杂和非线性性质。
Further exploration into the interplay between model predictive capacity and input data involved using varying quantities of compounds for training while maintaining a constant test set. The learning curve of the ensemble model indicated a correlation between increased training data volume and improved performance (Figure 3C). Notably, with a data volume of 25% (456 diazo compounds), the ${R}^{2}$ score attained 0.90. This suggests a significant physical correlation between the compounds’ structures and properties and their infrared absorption characteristics. The proposed ensemble model, leveraging a structure neighboring mechanism (SNM), demonstrates its capacity to learn effectively with as few as 456 compounds, thereby predicting infrared characteristic absorption values with considerable accuracy.
对模型预测能力与输入数据之间相互作用的进一步探索涉及在保持测试集不变的情况下使用不同数量的化合物进行训练。集成模型的学习曲线表明训练数据量的增加与性能提升之间存在相关性(图3C)。值得注意的是,当数据量为25%(456种重氮化合物)时,${R}^{2}$分数达到0.90。这表明化合物的结构和性质与其红外吸收特征之间存在显著的物理相关性。所提出的集成模型利用结构邻域机制(SNM),展示了其能够使用低至456种化合物进行有效学习的能力,从而以相当高的准确性预测红外特征吸收值。
Model Robustness and Generalization Analysis. To assess the generalizability of our model, we employed scaffold-based data splitting using the Murcko method ${}^{17}$ implemented in RDKit. This approach involves grouping molecules with similar core structures together, while those with significant structural differences are placed in distinct groups. The method automatically identified 293 groups of molecular scaffolds, allocating 75% to the training set and 25% to the test set. Notably, the model demonstrated robust performance under these stringent conditions, maintaining an ${R}^{2}$ value above 0.955 (Figure 4A).
模型稳健性和泛化分析。为了评估我们模型的泛化能力,我们使用了RDKit中实现的基于Murcko方法${}^{17}$的基于支架的数据拆分。这种方法涉及将具有相似核心结构的分子分组在一起,而将具有显著结构差异的分子放置在不同的组中。该方法自动识别出293组分子支架,将75%分配给训练集,25%分配给测试集。值得注意的是,该模型在这些严格条件下表现出稳健的性能,${R}^{2}$值保持在0.955以上(图4A)。
To assess the efficacy of our proposed descriptors in differentiating molecular types, we employed unsupervised DBSCAN ${}^{18}$ (Density-Based Spatial Clustering of Applications with Noise) clustering analysis. DBSCAN identifies clusters by looking for regions of high point density. The core principle of DBSCAN can be quantitatively described as follows:
为了评估我们提出的描述符在区分分子类型方面的有效性,我们采用了无监督DBSCAN${}^{18}$(基于密度的空间聚类应用与噪声)聚类分析。DBSCAN通过寻找高密度点区域来识别聚类。DBSCAN的核心原理可以定量描述如下:
$$ \text{ DBSCAN }\left( {\epsilon ,\text{ minPts }}\right) $$$$ = \{ p \in D \mid \text{ density }\left( p\right) $$$$ \geq \operatorname{minPts}\} \cup \left\{ {q \in D\mid \exists p\text{ s.t. }q \in {N}_{\epsilon }\left( p\right) }\right\} \tag{21} $$where $\epsilon$ (eps) is the maximum distance between two points to be considered neighbors, and minPts $\left( \mathop{\min }\limits_{\text{ samples }}\right)$ is the minimum number of points required to form a dense region.
其中$\epsilon$(eps)是被视为邻居的两点之间的最大距离,而minPts$\left( \mathop{\min }\limits_{\text{ samples }}\right)$是形成密集区域所需的最小点数。
The data are segmented into three distinct categories (Figure 4B). The examination of the infrared (IR) spectra revealed distinct absorption values corresponding to high (mean ${2138.3}{\mathrm{\;{cm}}}^{-1}$ ), medium (mean ${2108.4}{\mathrm{\;{cm}}}^{-1}$ ), and low (mean ${2085.7}{\mathrm{\;{cm}}}^{-1}$ ) frequencies (Figure 4C). These classifications exhibit clear characteristics attributable to the unique structural features of different compounds that influence their IR absorption properties. High-frequency regions are typically associated with electron-withdrawing substituents, such as nitro or carbonyl groups. Conversely, medium and low frequencies correlate with electron-donating substituents, including conjugation groups or alkyl groups. As a result, our clustering analysis successfully delineated distinct groups based on their structural features and IR absorption characteristics observed postclustering. Furthermore, the descriptor SNMDs can effectively differentiate the influence of various structures on the infrared absorption of target groups.
数据被分为三个不同的类别(图4B)。对红外(IR)光谱的检查揭示了对应于高(平均${2138.3}{\mathrm{\;{cm}}}^{-1}$)、中(平均${2108.4}{\mathrm{\;{cm}}}^{-1}$)和低(平均${2085.7}{\mathrm{\;{cm}}}^{-1}$)频率的不同吸收值(图4C)。这些分类表现出明显的特征,这归因于不同化合物独特的结构特征对其红外吸收特性的影响。高频区域通常与吸电子取代基相关,如硝基或羰基。相反,中低频与供电子取代基相关,包括共轭基团或烷基。因此,我们的聚类分析基于聚类后观察到的结构特征和红外吸收特性成功地划分出了不同的组。此外,描述符SNMDs可以有效地区分各种结构对目标基团红外吸收的影响。
In the domain of predictive analytics, it is essential to verify the robustness of a model when subjected to varied operational conditions. Prior investigations, inclusive of our own scholarly contributions, have empirically demonstrated that the performance of machine learning (ML) models is primarily contingent upon the congruence between the data sets employed during their training set and those applied in their predictive applications. ${}^{19}$ This particular study concentrates on employing ML models to prognosticate the characteristic infrared absorption frequencies of diazo functional groups, taking into account the chemical configuration of neighboring groups. Remarkably, this methodology facilitates the forecasting of previously unrecorded infrared spectral data. Accordingly, we have assessed the generalization potential of this model across a spectrum of diazo compounds that display varying extents of structural homogeneity.
在预测分析领域,当模型处于不同的操作条件下时,验证其稳健性至关重要。先前的研究,包括我们自己的学术贡献,已经通过实证证明机器学习(ML)模型的性能主要取决于其训练集所使用的数据集与预测应用中所应用的数据集之间是否一致。${}^{19}$ 这项特定的研究专注于使用ML模型来预测重氮官能团的特征红外吸收频率,同时考虑相邻基团的化学构型。值得注意的是,这种方法有助于预测以前未记录的红外光谱数据。因此,我们评估了该模型在一系列结构同质性程度不同的重氮化合物中的泛化潜力。
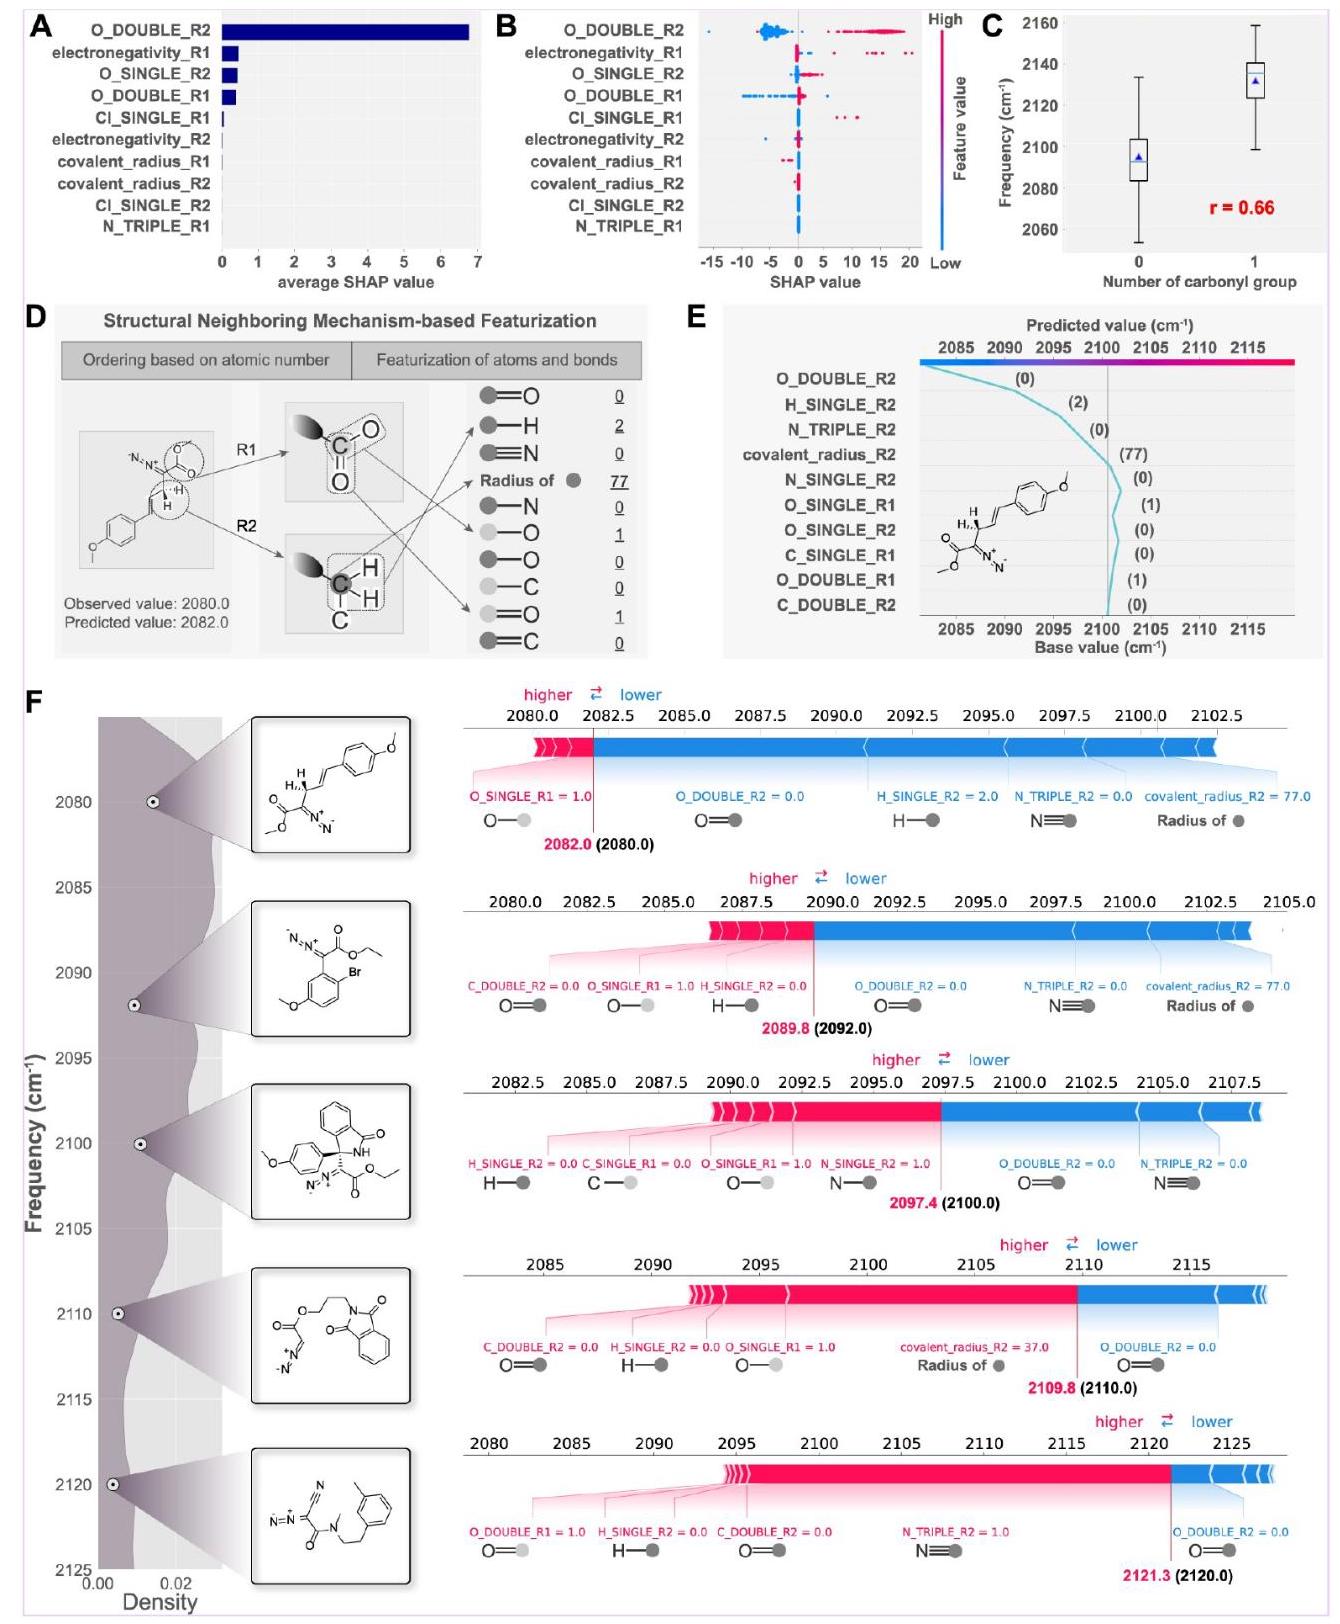
Figure 5. Comprehensive analysis of feature contributions and predictive mechanisms in infrared spectrum modeling of diazo compounds. (A) analysis of feature significance utilizing mean SHAP values. (B) distribution spectrum of characteristics as inferred from SHAP values. (C) boxplot showing the relationship between the number of carbonyl groups and infrared spectral data, indicating a strong Pearson correlation. coefficient of 0.66. (D) a comprehensive depiction of the feature extraction procedure leveraging the structural neighboring mechanism, which details the encoding of atomic and bond information for model input. (E) elaborate visualization of a decision framework, structured as a hierarchical analysis via SHAP values, sequentially unveiling the influence of individual features on projected infrared values. (F) display of molecular structures with their experimental and predicted infrared values, highlighting model efficacy with influences marked in red (higher) and blue (lower).
图5. 重氮化合物红外光谱建模中特征贡献和预测机制的综合分析。(A)利用平均SHAP值进行特征重要性分析。(B)从SHAP值推断出的特征分布光谱。(C)显示羰基数量与红外光谱数据之间关系的箱线图,表明皮尔逊相关系数为0.66。(D)利用结构相邻机制对特征提取过程的全面描述,详细说明了模型输入的原子和键信息的编码。(E)决策框架的详细可视化,通过SHAP值构建为层次分析,依次揭示各个特征对预测红外值的影响。(F)显示分子结构及其实验和预测的红外值,突出模型效果,影响用红色(较高)和蓝色(较低)标记。
Our methodology incorporates the use of the Tanimoto coefficient-a measure quantifying the likeness between two-dimensional molecular frameworks, ranging from 0% to 100%. The quantitative mathematical formula of the Tanimoto coefficient is as follows:
我们的方法采用了Tanimoto系数——一种量化二维分子框架之间相似性的度量,范围从0%到100%。Tanimoto系数的定量数学公式如下:
$$ T\left( {A, B}\right) = \frac{\left| A \cap B\right| }{\left| A\right| + \left| B\right| - \left| {A \cap B}\right| } \tag{22} $$where $\left| A\right|$ and $\left| B\right|$ represent the cardinality of sets $A$ and $B$ , respectively, and $\left| {A \cap B}\right|$ represents the cardinality of their intersection.
其中$\left| A\right|$和$\left| B\right|$分别表示集合$A$和$B$的基数,$\left| {A \cap B}\right|$表示它们交集的基数。
During cross-validation, this coefficient was calculated between each diazo compound in the test set and every compound in the training set. We established a series of similarity thresholds-90%, 80%, 70%, 60%, and 50%-to define varying levels of molecular resemblance. As a result, the data were stratified into five cohorts, each encompassing test set molecules that exhibited at least the defined threshold of similarity with one or more molecules in the training set. The cohorts were composed of the following sizes: ${n}_{90} = {178} \; \left( {{48.5}\% }\right) ,{n}_{80} = {206}\left( {{56.1}\% }\right) ,{n}_{70} = {277}\left( {{75.48}\% }\right) ,{n}_{60} = {318}$ (86.7%), and ${n}_{50} = {357}$ (97.3%), as detailed in Figure S5.
在交叉验证期间,计算了测试集中每个重氮化合物与训练集中每个化合物之间的该系数。我们建立了一系列相似性阈值——90%、80%、70%、60%和50%——来定义不同程度的分子相似性。结果,数据被分层为五个群组,每个群组包含与训练集中一个或多个分子表现出至少定义阈值相似性的测试集分子。这些群组的组成如下:${n}_{90} = {178} \; \left( {{48.5}\% }\right) ,{n}_{80} = {206}\left( {{56.1}\% }\right) ,{n}_{70} = {277}\left( {{75.48}\% }\right) ,{n}_{60} = {318}$(86.7%)和${n}_{50} = {357}$(97.3%),如图S5所示。
Interestingly, 13.3% of the diazo compounds demonstrated no greater than 60% resemblance to any molecule in the training set. Figure 4D presents the predicted ${R}^{2}$ , RMSE, and Mean Absolute Error (MAE) values for these groups, substantiating a pronounced correlation between molecular similarity and model generalization capability. The quantitative mathematical formula for the MAE is given by
有趣的是,13.3%的重氮化合物与训练集中的任何分子的相似性都不超过60%。图4D展示了这些组的预测${R}^{2}$、均方根误差(RMSE)和平均绝对误差(MAE)值,证实了分子相似性与模型泛化能力之间存在显著相关性。MAE的定量数学公式如下
$$ \mathrm{{MAE}} = \frac{1}{n}\mathop{\sum }\limits_{{i = 1}}^{n}\left| {{y}_{i} - {\widehat{y}}_{i}}\right| \tag{23} $$where $n$ is the number of observations, ${y}_{i}$ represents the actual values, and ${\widehat{y}}_{i}$ represents the predicted values. As molecular resemblance diminishes, there is a noticeable decline in predictive accuracy. For compounds with more than 90% similarity, the model exhibited exemplary performance, achieving an ${\mathrm{R}}^{2}$ of 0.981, an RMSE of 2.616, and an MAE of ${1.756}\left( {\mathrm{\;{cm}}}^{-1}\right)$ . Conversely, for those with over ${50}\%$ similarity, the corresponding values were ${0.967}\left( {\mathrm{R}}^{2}\right) ,{3.838}$ (RMSE), and 2.654 (MAE) ${\mathrm{{cm}}}^{-1}$ , respectively. Remarkably, the ${\mathrm{R}}^{2}$ for compounds with less than 50% similarity still attained 0.898, as depicted in Figure 4E. The Supporting Information provides detailed comparisons of the ten test molecules with the lowest molecular similarity to the training set, alongside their predicted errors relative to experimental values, as detailed in Figures S6 and S7.
其中$n$为观测值数量,${y}_{i}$代表实际值,${\widehat{y}}_{i}$代表预测值。随着分子相似性降低,预测准确性显著下降。对于相似度超过90%的化合物,该模型表现出优异性能,${\mathrm{R}}^{2}$达到了0.981,均方根误差(RMSE)为2.616,平均绝对误差(MAE)为${1.756}\left( {\mathrm{\;{cm}}}^{-1}\right)$。相反,对于相似度超过${50}\%$的化合物,相应的值分别为${0.967}\left( {\mathrm{R}}^{2}\right) ,{3.838}$(RMSE)和2.654(MAE)${\mathrm{{cm}}}^{-1}$。值得注意的是,如图4E所示,相似度低于50%的化合物的${\mathrm{R}}^{2}$仍达到0.898。支持信息提供了与训练集分子相似度最低的十个测试分子的详细比较,以及它们相对于实验值的预测误差,详见图S6和S7。
Moreover, the efficacy of the model is often conditional on the quality of the data, with noise being a significant determinant. Noise can originate from measurement discrepancies, data handling errors, or external environmental variations. To elucidate the predictive capabilities of our proposed ensemble model, we explored the impact of varying data volumes and noise levels. The performance was evaluated by introducing assorted degrees of random noise into the input data, spanning from 0% (no noise) to 20%, in 5% increments. For each level of noise, the model’s predictive ${\mathrm{R}}^{2}$ , RMSE, and MAE were computed, with multiple iterations conducted to ensure the reliability of results. As illustrated in Figure 4F, in a noise-free environment, the model demonstrated exceptional predictive accuracy $\left( {{\mathrm{R}}^{2} = {0.969}}\right)$ . With incrementing noise levels, a gradual decrease in ${\mathrm{R}}^{2}$ was observed. Notably, the model sustained an ${\mathrm{R}}^{2}$ above 0.91 for noise levels up to 15%, evidencing its robustness. Nonetheless, beyond a 10% noise threshold, performance deterioration became more pronounced, yet the model still maintained an ${\mathrm{R}}^{2}$ of 0.907 at 20% noise, underscoring its capability to handle inherent experimental inaccuracies in observational data sets.
此外,模型的有效性通常取决于数据质量,噪声是一个重要决定因素。噪声可能源于测量差异、数据处理错误或外部环境变化。为了阐明我们提出的集成模型的预测能力,我们探讨了不同数据量和噪声水平的影响。通过向输入数据中引入从0%(无噪声)到20%、以5%递增的各种程度的随机噪声来评估性能。对于每个噪声水平,计算模型的预测${\mathrm{R}}^{2}$、RMSE和MAE,并进行多次迭代以确保结果的可靠性。如图4F所示,在无噪声环境中,模型表现出卓越的预测准确性$\left( {{\mathrm{R}}^{2} = {0.969}}\right)$。随着噪声水平增加,观察到${\mathrm{R}}^{2}$逐渐下降。值得注意的是,对于高达15%的噪声水平,模型的${\mathrm{R}}^{2}$维持在0.91以上,证明了其稳健性。尽管如此,超过10%的噪声阈值后,性能下降变得更加明显,但在20%噪声水平下,模型的${\mathrm{R}}^{2}$仍保持在0.907,突出了其处理观测数据集中固有实验误差的能力。
Model Decision-Making Process and Interpretability Analysis. The imperative execution of model interpretability analysis serves as a cornerstone for demystifying the foundational logic governing model predictions. Such analysis is traditionally divided into two primary categories: ex-ante analysis and postevent analysis. In the pursuit of enhanced accuracy and minimal errors within the infrared spectrum model, the application of the SHapley Additive exPlanations (SHAP) methodology is paramount for ensuring comprehensibility. ${}^{20}$ As a post hoc interpretative instrument, SHAP distinctively quantifies the contribution of each feature to the model’s output, thus providing a comprehensive and nuanced understanding of the “black box” model at both macroscopic and microscopic levels. The SHAP value for a feature $i$ is calculated as follows:
模型决策过程与可解释性分析。模型可解释性分析的迫切执行是揭开模型预测基础逻辑神秘面纱的基石。这种分析传统上分为两大类:事前分析和事后分析。在追求提高红外光谱模型的准确性和最小化误差方面,应用SHapley加性解释(SHAP)方法对于确保可理解性至关重要。${}^{20}$作为一种事后解释工具,SHAP独特地量化了每个特征对模型输出的贡献,从而在宏观和微观层面上提供了对“黑箱”模型的全面而细致入微的理解。特征$i$的SHAP值计算如下:
$$ {\phi }_{i} = \mathop{\sum }\limits_{{S \subseteq N\smallsetminus \{ i\} }}\frac{\left| S\right| !\left( {\left| N\right| - \left| S\right| - 1}\right) !}{\left| N\right| !}\left\lbrack {v\left( {S\cup \{ i\} }\right) - v\left( S\right) }\right\rbrack $$(24)
where:
其中:
${\phi }_{i}$ is the SHAP value for feature $i$ .
${\phi }_{i}$是特征$i$的SHAP值。
$N$ is the set of all features.
$N$是所有特征的集合。
$S$ is a subset of features not including feature $i$ .
$S$是不包括特征$i$的特征子集。
$v\left( S\right)$ is the value function that maps subsets of features to the model prediction.
$v\left( S\right)$是将特征子集映射到模型预测的价值函数。
Feature importance analysis occupies a pivotal role at the intersection of data science theory and its practical implementations, significantly influencing the development of efficient and interpretable machine learning models. In this study, feature importance was determined based on SHAP values, with the carbonyl descriptor identified as the most significant due to its substantial average SHAP value of 6.8. This starkly contrasts with other descriptors, which all registered values below 1.0 (Figure 5A). An interesting correlation was observed between the number of carbonyl groups and their corresponding frequency; an increase in carbonyl groups (trending toward red) correlated with a higher frequency and vice versa (Figure 5B). Furthermore, the atom bonded to the diazo group exhibited significant influence, with its electronegativity being directly proportional to the frequency. This relationship is further substantiated by a Pearson correlation coefficient of 0.66 between the frequency and carbonyl groups, indicating a robust positive correlation (Figure 5C). Additionally, the tree-based ensemble learning method, specifically XGBoost, was employed for feature importance analysis. Notably, the top four features identified by XGBoost were consistent with those determined by SHAP, underscoring their critical role in model performance. Among the remaining features, seven ranked within the top ten by both methods, albeit in a different order of importance, as detailed in Figure S8. This partial consistency suggests that, while exact rankings may vary, these features collectively contribute significantly to the model’s predictive accuracy.
特征重要性分析在数据科学理论及其实际应用的交叉领域中起着关键作用,对高效且可解释的机器学习模型的发展产生重大影响。在本研究中,基于SHAP值确定特征重要性,羰基描述符因其6.8的显著平均SHAP值而被确定为最重要的特征。这与其他描述符形成鲜明对比,其他描述符的所有值均低于1.0(图5A)。观察到羰基数量与其相应频率之间存在有趣的相关性;羰基数量增加(趋向红色)与频率升高相关,反之亦然(图5B)。此外,与重氮基团相连的原子表现出显著影响,其电负性与频率成正比。频率与羰基之间的皮尔逊相关系数为0.66,进一步证实了这种关系,表明存在强正相关(图5C)。此外,基于树的集成学习方法,特别是XGBoost,被用于特征重要性分析。值得注意的是,XGBoost确定的前四个特征与SHAP确定的特征一致,强调了它们在模型性能中的关键作用。在其余特征中,有七个在两种方法中均排名前十,尽管重要性顺序不同,如图S8所示。这种部分一致性表明,虽然确切排名可能不同,但这些特征共同对模型的预测准确性做出了重大贡献。
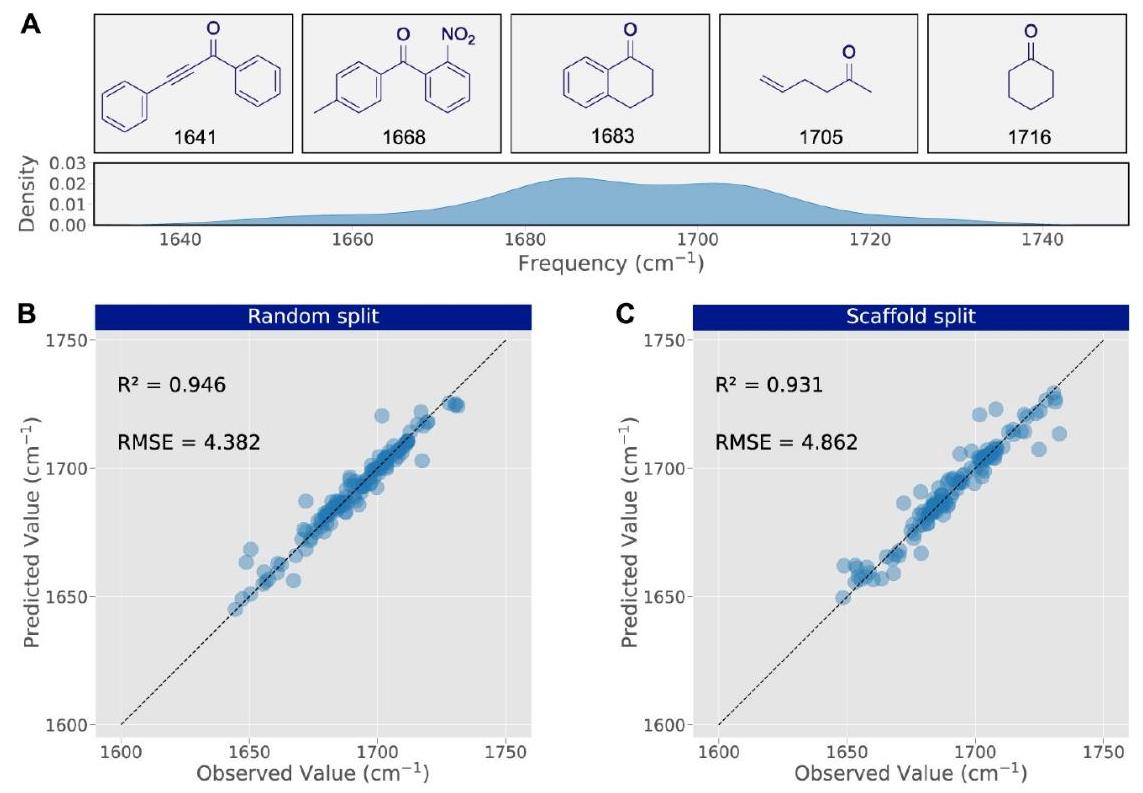
Figure 6. Predictive performance for ketone carbonyl groups. (A) Distribution of infrared absorption frequencies for ketone carbonyl groups and randomly selected molecules across each interval. (B) Performance of the model trained with a random split on the test set. (C) Performance of the model trained with a scaffold split on the test set.
图6. 酮羰基的预测性能。(A) 酮羰基和每个区间内随机选择的分子的红外吸收频率分布。(B) 在测试集上使用随机分割训练的模型的性能。(C) 在测试集上使用支架分割训练的模型的性能。
Further examination of specific compounds, such as methyl (E)-2-diazo-5-(4-methoxyphenyl)pent-4-enoate, revealed nuanced feature engineering based on the structural neighboring mechanism. This involved segmentation into two chemical space domains, R1 and R2, based on atomic number size, followed by quantitative characterization according to atom types and chemical bonds (Figure 5D). In the context of model decision-making, the central gray vertical line in the decision diagram represents the model’s baseline value, with colored lines depicting predictions and illustrating the influence of each feature in shifting the output value above or below the average prediction. Eigenvalues adjacent to the prediction line provide a reference. The cumulative impact of SHAP values from the base value to the final predicted wavenumber is depicted at the graph’s apex (Figure 5E), highlighting the top 10 most impactful features.
对特定化合物,如甲基 (E)-2-重氮-5-(4-甲氧基苯基)戊-4-烯酸酯的进一步研究,揭示了基于结构邻域机制的细微特征工程。这涉及根据原子序数大小将其分割为两个化学空间域R1和R2,然后根据原子类型和化学键进行定量表征(图5D)。在模型决策的背景下,决策图中的中央灰色垂直线代表模型的基线值,彩色线描绘预测,并说明每个特征在将输出值移至平均预测之上或之下的影响。与预测线相邻的特征值提供参考。从基值到最终预测波数的SHAP值的累积影响在图的顶部描绘(图5E),突出了最具影响力 的前10个特征。
The absence of a double-bonded oxygen fragment in the R2 domain (O_DOUBLE_R2 = 0) significantly influences model decision-making, decreasing the wavenumber from approximately 2092.1 to ${2082.0}{\mathrm{\;{cm}}}^{-1}$ . This effect is attributed to the electron-withdrawing capability of the carbon-oxygen double-bonded fragment impacting the diazo group. Conversely, the presence of a double-bonded oxygen fragment in the R1 domain (O_DOUBLE_R1 = 1) slightly elevates the wavenumber from the baseline. Moreover, the presence of two single-bond hydrogen fragments (H_SINGLE_R2 = 2) decreases the wavenumber from around 2096.6 to 2092.1 ${\mathrm{{cm}}}^{-1}$ , linked to the moderate electron-donating effect of the carbon-hydrogen single-bond fragment on the diazo group. The absence of a triple-bonded nitrogen fragment (N_TRIPLE R2 = 0) reduces the wavenumber from 2098.4 to 2096.6 ${\mathrm{{cm}}}^{-1}$ , attributed to the electron-withdrawing effect of the carbon-nitrogen triple-bonded fragment on the diazo group. Additionally, the covalent radius of the atom linked to the R2 domain and the diazo group (colvalent_radius_R2 = 77) plays a role; generally, a larger covalent radius indicates a greater electron-donating propensity, and vice versa.
R2域中不存在双键氧片段(O_DOUBLE_R2 = 0)对模型决策有显著影响,将波数从约2092.1降低到${2082.0}{\mathrm{\;{cm}}}^{-1}$ 。这种效应归因于碳氧双键片段的吸电子能力对重氮基团的影响。相反,R1域中存在双键氧片段(O_DOUBLE_R1 = 1)会使波数从基线略有升高。此外,存在两个单键氢片段(H_SINGLE_R2 = 2)会使波数从约2096.6降低到2092.1 ${\mathrm{{cm}}}^{-1}$ ,这与碳氢单键片段对重氮基团的适度供电子效应有关。不存在三键氮片段(N_TRIPLE_R2 = 0)会使波数从2098.4降低到2096.6 ${\mathrm{{cm}}}^{-1}$ ,这归因于碳氮三键片段对重氮基团的吸电子效应。此外,与R2域和重氮基团相连的原子的共价半径(colvalent_radius_R2 = 77)也起作用;一般来说,共价半径越大,供电子倾向越大,反之亦然。
Given the diverse kinds of atoms in the data set (e.g., $\mathrm{H} = {37} \; \mathrm{{pm}},\mathrm{\;B} = {82}\mathrm{{pm}}, N = {75}\mathrm{{pm}},\mathrm{O} = {73}\mathrm{{pm}},\mathrm{{Si}} = {111}\mathrm{{pm}}, p = {106}$ pm, $S = {102}\mathrm{{pm}}$ ), a covalent radius of ${77}\mathrm{{pm}}$ (representing carbon atoms) necessitates a reduction in wavenumber from around 2101.0 to ${2098.4}{\mathrm{\;{cm}}}^{-1}$ . Additionally, the presence of a single bonded oxygen in the R1 domain (O_SINGLE_R1 = 1) increases the wavenumber, whereas its absence in the R2 domain (O_SINGLE_R2 = 0) decreases it. This effect is attributed to the electron-withdrawing impact of the carbon-oxygen single bond on the diazo group. The influence of these features on model decisions is quantifiable through force plots (Figure 5F). This alignment with established chemical principles underscores the model’s reliance on chemical logic and rules. In summation, constructing models with heightened chemical interpretability is not only essential for validating their predictions but also acts as a conduit between machine learning and conventional chemistry. The integration of model insights with established chemical theories not only bolsters the reliability of computational predictions but also deepens the understanding of chemical concepts. This synergy of advanced data-driven methodologies with traditional scientific knowledge heralds a transformative era in chemical research and theoretical exploration.
鉴于数据集中存在多种原子(例如,$\mathrm{H} = {37} \; \mathrm{{pm}},\mathrm{\;B} = {82}\mathrm{{pm}}, N = {75}\mathrm{{pm}},\mathrm{O} = {73}\mathrm{{pm}},\mathrm{{Si}} = {111}\mathrm{{pm}}, p = {106}$皮米,$S = {102}\mathrm{{pm}}$),共价半径为${77}\mathrm{{pm}}$(代表碳原子)使得波数从约2101.0降低到${2098.4}{\mathrm{\;{cm}}}^{-1}$。此外,R1域中存在单键氧(O_SINGLE_R1 = 1)会增加波数,而R2域中不存在单键氧(O_SINGLE_R2 = 0)则会降低波数。这种效应归因于碳氧单键对重氮基团的吸电子影响。通过力场图(图5F)可以量化这些特征对模型决策的影响。这种与既定化学原理的一致性强调了模型对化学逻辑和规则的依赖。总之,构建具有更高化学可解释性的模型不仅对于验证其预测至关重要,而且还充当机器学习与传统化学之间的桥梁。将模型见解与既定化学理论相结合,不仅增强了计算预测的可靠性,还加深了对化学概念的理解。先进的数据驱动方法与传统科学知识的这种协同作用预示着化学研究和理论探索的变革性时代。
Versatility and Extension of the Structural Neighboring Mechanism. To validate the broader applicability of our Structural Neighboring Mechanism, we expanded our study to encompass ketone carbonyl groups. Infrared absorption data were acquired from 532 compounds featuring ketone carbonyl groups (Figure 6A), which were then partitioned into a 75% training set and a 25% test set. Employing an ensemble learning approach, we developed a predictive model for the infrared absorption of ketone carbonyl groups. The model exhibited strong performance, achieving an ${R}^{2}$ value of 0.946 and an RMSE of 4.382 on the test set (Figure 6B). Additionally, using the scaffold split method, the model retained an ${R}^{2}$ value of 0.931 and an RMSE of 4.862 (Figure 6C). These results underscore the adaptability and potential of our method beyond diazo functional groups, indicating its broader utility in predicting infrared absorption values for diverse functional groups.
结构邻域机制的通用性和扩展性。为了验证我们的结构邻域机制的更广泛适用性,我们将研究扩展到包括酮羰基。从532种具有酮羰基的化合物中获取红外吸收数据(图6A),然后将其分为75%的训练集和25%的测试集。采用集成学习方法,我们开发了一种用于酮羰基红外吸收的预测模型。该模型表现出强大的性能,在测试集上的${R}^{2}$值为0.946,RMSE为4.382(图6B)。此外,使用支架拆分方法,该模型的${R}^{2}$值为0.931,RMSE为4.862(图6C)。这些结果强调了我们的方法在重氮官能团之外的适应性和潜力,表明其在预测各种官能团的红外吸收值方面具有更广泛的用途。
To comprehensively evaluate the performance of the Structural Neighboring Mechanism (SNM) model, which is specifically designed to predict the infrared characteristic absorption values of functional groups, we conducted a comparative analysis with two established end-to-end models: Graphormer-IR, ${}^{21}$ trained on experimental spectral data, and DetaNet, ${}^{22}$ based on DFT-calculated data, both of which provide comprehensive infrared spectrum predictions. Using the same test set data, we replicated both models and analyzed key performance metrics, including root-mean-square error (RMSE) and inference time. As depicted in Figure 7, the SNM model consistently achieves lower RMSE values when predicting the infrared characteristic absorption of the diazo group and ketone carbonyl group, demonstrating superior predictive performance in these targeted predictions. In contrast, Graphormer-IR and DetaNet, while excelling in comprehensive spectral predictions, exhibit higher RMSE values for these specific functional groups. Moreover, the SNM model maintains a more favorable inference time, emphasizing its efficiency and practicality for high-throughput spectral predictions, particularly when focused on functional group analysis.
为了全面评估专门设计用于预测官能团红外特征吸收值的结构邻域机制(SNM)模型的性能,我们与两个既定的端到端模型进行了比较分析:Graphormer-IR,${}^{21}$在实验光谱数据上训练,以及DetaNet,${}^{22}$基于DFT计算数据,这两个模型都提供全面的红外光谱预测。使用相同的测试集数据,我们复制了这两个模型并分析了关键性能指标,包括均方根误差(RMSE)和推理时间。如图7所示,在预测重氮基团和酮羰基的红外特征吸收时,SNM模型始终实现较低的RMSE值,在这些目标预测中表现出卓越的预测性能。相比之下,Graphormer-IR和DetaNet虽然在全面光谱预测方面表现出色,但在这些特定官能团上表现出更高的RMSE值。此外,SNM模型保持了更有利的推理时间,强调了其在高通量光谱预测中的效率和实用性,特别是在专注于官能团分析时。
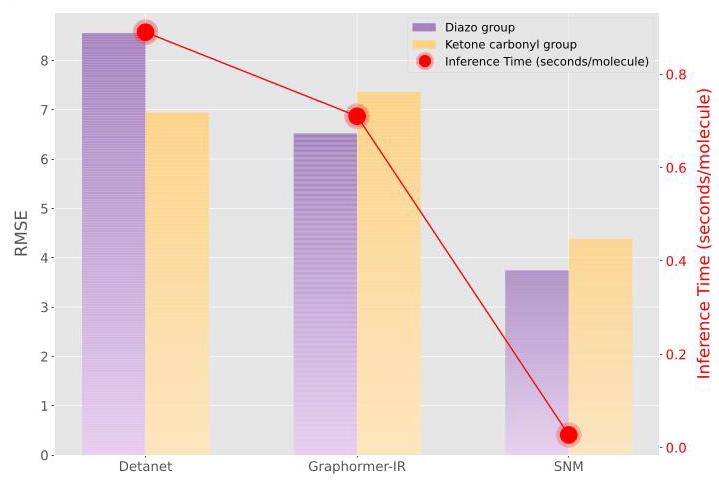
Figure 7. Comparative performance analysis of the SNM model, Graphormer-IR, and DetaNet. The bar chart displays the root-mean-square error (RMSE) for predicting the infrared characteristic absorption values of the diazo group (indigo) and ketone carbonyl group (orange) across each model. The line plot with red markers illustrates the averaged inference time (seconds/molecule), providing insight into the computational efficiency of each approach.
图7. SNM模型、Graphormer-IR和DetaNet的比较性能分析。柱状图显示了每个模型预测重氮基团(靛蓝色)和酮羰基(橙色)的红外特征吸收值的均方根误差(RMSE)。带有红色标记的线图说明了平均推理时间(秒/分子),提供了对每种方法计算效率的洞察。
Applicability of Prediction Models. The CIAD data set comprises a range of stable diazo compounds. Within this extensive chemical landscape, a significant fraction of cost-effective diazo compounds exhibit instability, presenting obstacles for direct experimental evaluation and molecular property elucidation. ${}^{{23},{24}}$ To assess the model’s ability to extrapolate, we predicted the infrared spectra of the very unstable yet versatile diazo compounds diazomethane, ${}^{{25} - {27}}$ diazoethane, ${}^{{25},{28},{29}}$ and 2-diazopropane. ${}^{{30} - {32}}$
预测模型的适用性。CIAD数据集包含一系列稳定的重氮化合物。在这个广阔的化学领域中,相当一部分具有成本效益的重氮化合物表现出不稳定性,这给直接实验评估和分子性质阐明带来了障碍。${}^{{23},{24}}$为了评估模型的外推能力,我们预测了极不稳定但用途广泛的重氮化合物重氮甲烷、${}^{{25} - {27}}$重氮乙烷、${}^{{25},{28},{29}}$和2-重氮丙烷的红外光谱。${}^{{30} - {32}}$
This assessment required a tripartite analysis, combining theoretical calculations, empirical measurements, and model-based predictions. The infrared spectra based on DFT calculations for the three diazo compounds are presented in Figure S9. Molecular similarity, defined by the highest molecular similarity score within the corresponding data set, ranged from 0.188 to 0.438 , indicating moderate to low structural similarity. As shown in Table 1, theoretical analysis of diazomethane yielded a spectral value of ${2090.2}{\mathrm{\;{cm}}}^{-1}$ , while a precision-guided experimental approach determined a value of 2091.0 ${\mathrm{{cm}}}^{-1}$ . The model, developed within a rigorous analytical framework, estimated the spectral value to be 2087.3 ${\mathrm{{cm}}}^{-1}$ . The proximity of the model’s estimations to values derived through empirical methodologies underscores its predictive accuracy and its capacity to mitigate the challenges associated with the direct analysis of unstable compounds. Furthermore, although the calculated DFT value is slightly closer to the experimental value, the error of our model decreases as molecular similarity improves. In addition, the experiment comparing model and DFT errors based on molecular similarity was conducted. As molecular similarity to the training set increased, the accuracy of the model’s predicted values improved, displaying a clear trend. Conversely, DFT calculations did not exhibit this trend, as detailed in Figure S10. As molecular complexity increases, the efficiency predicted by the model diverges significantly from theoretical calculations. This discrepancy ranges from 3,150 times for diazomethane to 12700 times for diazethane, and up to 26650 times for 2-diazopropane. The concordance observed between the predicted and experimental values underscores that the learning model, engineered through the incorporation of a structural neighboring mechanism, is adept at discerning the interrelations between molecular structure and properties, thereby exhibiting pronounced robustness and generalizability.
这项评估需要进行三方分析,结合理论计算、经验测量和基于模型的预测。三种重氮化合物基于DFT计算的红外光谱如图S9所示。由相应数据集中最高分子相似性得分定义的分子相似性范围为0.188至0.438,表明结构相似性为中等至低。如表1所示,重氮甲烷的理论分析得出光谱值为${2090.2}{\mathrm{\;{cm}}}^{-1}$,而精确引导的实验方法确定的值为2091.0${\mathrm{{cm}}}^{-1}$。在严格分析框架内开发的模型估计光谱值为2087.3${\mathrm{{cm}}}^{-1}$。模型估计值与通过经验方法得出的值接近,突出了其预测准确性以及减轻与不稳定化合物直接分析相关挑战的能力。此外,尽管计算出的DFT值略更接近实验值,但随着分子相似性提高,我们模型的误差会减小。此外,还进行了基于分子相似性比较模型和DFT误差的实验。随着与训练集的分子相似性增加,模型预测值的准确性提高,呈现出明显趋势。相反,如图S10所示,DFT计算未呈现此趋势。随着分子复杂性增加,模型预测的效率与理论计算有显著差异。这种差异从重氮甲烷的3150倍到重氮乙烷的高达12700倍,再到2-重氮丙烷的高达26650倍。预测值与实验值之间观察到的一致性突出表明,通过纳入结构邻域机制设计的学习模型善于辨别分子结构与性质之间的相互关系,从而表现出显著的稳健性和通用性。
The accurate prediction of infrared (IR) absorption spectra for multifunctional groups within complex cyclic structures is crucial in the research of natural products and drug molecules. We have developed an advanced system designed to predict the IR absorption spectra of such intricate structures. This system identifies functional groups and structural fragments in compounds, integrating this chemical information into specialized prediction models for functional group IR absorption. Our system, combined with pretrained prediction models for the IR absorption frequencies of diazo groups and ketone carbonyl groups, demonstrates its efficacy. Table 2 showcases the application of these models on two external compounds, 1-phenylpropane-1,2-dione (compound 2.1) and ethyl 2-diazo-3-(3-diazo-2-oxoindolin-1-yl)-3-oxopropanoate (compound 2.2), each containing two ketone carbonyl groups and diazo groups, respectively. Molecular similarity, defined by the highest molecular similarity score within the corresponding data set, ranged from 0.6 to 0.7 , indicating moderate structural similarity. For compound 2.1, the experimental IR absorption value ${}^{34}$ at ${1673.0}{\mathrm{\;{cm}}}^{-1}$ yielded a model prediction of 1672.7 ${\mathrm{{cm}}}^{-1}$ and a DFT-calculated value of ${1663.8}{\mathrm{\;{cm}}}^{-1}$ . The relative error of the model’s prediction, based on experimental values, is significantly lower compared to the DFT calculation, with a difference exceeding 30-fold. Similarly, for an experimental value of ${1709.0}{\mathrm{\;{cm}}}^{-1}$ , our model predicted ${1706.8}{\mathrm{\;{cm}}}^{-1}$ , while the DFT calculation was ${1714.1}{\mathrm{\;{cm}}}^{-1}$ , showing a more than 2- fold reduction in relative error. For compound 2.2, with an experimental value ${}^{35}$ of ${2105.0}{\mathrm{\;{cm}}}^{-1}$ , our model predicted ${2109.8}{\mathrm{\;{cm}}}^{-1}$ compared to a DFT calculation of ${2090.3}{\mathrm{\;{cm}}}^{-1}$ , reducing the relative error by more than 3-fold. At 2140.0 ${\mathrm{{cm}}}^{-1}$ , our model predicted 2138.1 ${\mathrm{{cm}}}^{-1}$ , while the DFT calculation was ${2193.4}{\mathrm{\;{cm}}}^{-1}$ , again showing an error reduction of over 30-fold. Additionally, the DFT calculation of complex molecular structures is costly and time-consuming. In contrast, our model requires only a fraction of a second to achieve high-precision IR absorption frequency predictions close to the experimental values, improving the DFT calculation efficiency by over 500,000 times.
准确预测复杂环状结构中多官能团的红外(IR)吸收光谱在天然产物和药物分子研究中至关重要。我们开发了一个先进的系统,旨在预测此类复杂结构的IR吸收光谱。该系统识别化合物中的官能团和结构片段,并将这些化学信息整合到用于官能团IR吸收的专门预测模型中。我们的系统与重氮基团和酮羰基IR吸收频率的预训练预测模型相结合,证明了其有效性。表2展示了这些模型在两种外部化合物上的应用,1-苯基丙烷-1,2-二酮(化合物2.1)和2-重氮基-3-(3-重氮基-2-氧代吲哚-1-基)-3-氧代丙酸乙酯(化合物2.2),它们分别含有两个酮羰基和重氮基团。由相应数据集中最高分子相似性得分定义的分子相似性范围为0.6至0.7,表明结构相似性中等。对于化合物2.1,在${1673.0}{\mathrm{\;{cm}}}^{-1}$处的实验IR吸收值${}^{34}$产生的模型预测值为1672.7${\mathrm{{cm}}}^{-1}$,DFT计算值为${1663.8}{\mathrm{\;{cm}}}^{-1}$。基于实验值,模型预测的相对误差与DFT计算相比显著更低,差异超过30倍。同样,对于${1709.0}{\mathrm{\;{cm}}}^{-1}$的实验值,我们的模型预测为${1706.8}{\mathrm{\;{cm}}}^{-1}$,而DFT计算为${1714.1}{\mathrm{\;{cm}}}^{-1}$,相对误差降低了两倍多。对于化合物2.2,在${2105.0}{\mathrm{\;{cm}}}^{-1}$处的实验值${}^{35}$,我们的模型预测为${2109.8}{\mathrm{\;{cm}}}^{-1}$,而DFT计算为${2090.3}{\mathrm{\;{cm}}}^{-1}$,相对误差降低了三倍多。在2140.0${\mathrm{{cm}}}^{-1}$处,我们的模型预测为2138.1${\mathrm{{cm}}}^{-1}$,而DFT计算为${2193.4}{\mathrm{\;{cm}}}^{-1}$,再次显示误差降低了30多倍。此外,复杂分子结构的DFT计算成本高且耗时。相比之下,我们的模型仅需几分之一秒就能实现接近实验值的高精度IR吸收频率预测,将DFT计算效率提高了50多万倍。
Table 1. Prediction of Infrared Characteristic Absorption Values of Unstable Diazo Compounds ${}^{a, b, c, d}$
表1. 不稳定重氮化合物${}^{a, b, c, d}$的红外特征吸收值预测
| Entry | Compound ${}^{\left\lbrack \mathrm{a}\right\rbrack }$ | Mol. Wt. [g/mol] | Boiling point [K] | Experimental value $\left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack$ | Model-predicted value $\left\lbrack \mathrm{b}\right\rbrack \left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack$ | DFT-calculated value ${}^{\left\lbrack \mathrm{c}\right\rbrack }\left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack$ | Similarity ${}^{\left\lbrack \mathrm{d}\right\rbrack }$ |
| 1 |  | 42.04 | 250.0 | 2091.0 | 2087.3 | 2090.2 | 0.263 |
| (760 Torr) | (0.02 s) | (63 s) | |||||
| 2 |  | 56.07 | 259.2 | 2063.0 | 2064.0 | 2062.2 | 0.438 |
| (100 Torr) | (0.03 s) | (381 s) | |||||
| 3 |  | 70.09 | 242.0 | 2036.0 | 2044.3 | 2037.6 | 0.188 |
| (14 Torr) | (0.02 s) | (533 s) |
${}^{a}$ Out of CIAD dataset. ${}^{b}$ The ensemble model. ${}^{c}$ The vibrational scaling factor is 0.951 based on B3LYP/def2-TZVP level. ${}^{33}{}^{d}$ The highest molecular similarity to the molecules in the CIAD dataset, where the molecular similarity is calculated by the Tanimoto coefficient.
${}^{a}$来自CIAD数据集。${}^{b}$集成模型。${}^{c}$基于B3LYP/def2-TZVP水平,振动缩放因子为0.951。${}^{33}{}^{d}$与CIAD数据集中分子的最高分子相似性,其中分子相似性通过Tanimoto系数计算。
Table 2. Prediction of Infrared Characteristic Absorption Values of Multi-Functional Groups in Complex Cyclic Structures ${}^{a, b,{cd}}$
表2. 复杂环状结构中多官能团的红外特征吸收值预测${}^{a, b,{cd}}$
| Entry | Compound[a] | Experimental value $\left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack$ | Model-predicted value ${\left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack }^{\left\lbrack \mathrm{b}\right\rbrack }$ | DFT-calculated value ${\left\lbrack {\mathrm{{cm}}}^{-1}\right\rbrack }^{\left\lbrack \mathrm{c}\right\rbrack }$ | Similarity ${}^{\left\lbrack \mathrm{d}\right\rbrack }$ |
| 1 |  | ① 1673.0 ② 1709.0 | ① ${1672.7}\left( {{0.02}\% }\right)$ ② ${1706.8}\left( {{0.13}\% }\right)$ $\left( {{0.02}\mathrm{\;s}}\right)$ | ① ${1663.8}\left( {{0.55}\% }\right)$ ② 1714.1 (0.30%) (4181 s) | 0.652 |
| 2 |  | ① 2105.0 ② 2140.0 | ① ${2109.8}\left( {{0.23}\% }\right)$ ② ${2138.8}\left( {{0.08}\% }\right)$ $\left( {{0.03}\mathrm{\;s}}\right)$ | ① 2090.3 (0.70%) ② 2193.4 (2.50%) (16243 s) | 0.673 |
${}^{a}$ Out of dataset. ${}^{b}$ The ensemble model. ${}^{c}$ The vibrational scaling factor is 0.951 based on B3LYP/def2-TZVP level. ${}^{33}{}^{d}$ The highest molecular similarity to the molecules in the corresponding dataset, where the molecular similarity is calculated by the Tanimoto coefficient.
${}^{a}$来自数据集。${}^{b}$集成模型。${}^{c}$基于B3LYP/def2-TZVP水平,振动缩放因子为0.951。${}^{33}{}^{d}$与相应数据集中分子 的最高分子相似性,其中分子相似性通过Tanimoto系数计算。
II CONCLUSIONS
II 结论
In summary, this study demonstrates the efficacy of a machine learning approach with a structural neighboring mechanism- (SNM) for predicting the infrared spectra of diazo groups and ketone carbonyl groups. This method addresses existing limitations in spectral analysis, offering improved accuracy and efficiency. The integration of the structural neighboring mechanism is particularly notable for its enhancement of prediction capabilities, underscoring the potential of machine learning in spectroscopic applications. These findings not only contribute significantly to the field of analytical chemistry but also open avenues for future research, including the model’s adaptation for other complex molecular structures. The broader implications of this research extend to advancing organic synthesis and deepening our understanding of molecular interactions in various chemical contexts.
总之,本研究证明了一种具有结构邻域机制(SNM)的机器学习方法在预测重氮基团和酮羰基红外光谱方面的有效性。该方法解决了光谱分析中现有的局限性,提高了准确性和效率。结构邻域机制的整合因其增强了预测能力而尤为显著,凸显了机器学习在光谱应用中的潜力。这些发现不仅对分析化学领域有重大贡献,也为未来的研究开辟了道路,包括将该模型应用于其他复杂分子结构。这项研究的更广泛意义在于推动有机合成以及加深我们对各种化学环境中分子相互作用的理解。
At present, this study has some limitations that require further refinement in the future. Expanding the model to encompass additional functional groups will necessitate the development of new models, a process that is both data-intensive and computationally demanding. For researchers with constrained resources or limited expertise, these challenges may pose significant barriers, potentially limiting the method’s broader adoption within the analytical chemistry community. Nonetheless, the framework we propose offers distinct advantages in terms of scalability and interpretability. These features not only enhance predictive accuracy but also facilitate more transparent and rapid predictions compared to traditional end-to-end models. As such, it has considerable potential to become a valuable tool in predictive chemistry. With the inclusion of more functional groups, ongoing model refinement, and the enhancement of data resources, we believe this approach could evolve into a critical resource for chemical prediction.
目前,本研究存在一些局限性,未来需要进一步完善。将模型扩展到涵盖更多官能团需要开发新模型,这一过程既数据密集又计算量大。对于资源有限或专业知识有限的研究人员来说,这些挑战可能构成重大障碍,可能会限制该方法在分析化学界的更广泛采用。尽管如此,我们提出的框架在可扩展性和可解释性方面具有明显优势。这些特性不仅提高了预测准确性,而且与传统的端到端模型相比,能促进更透明、快速的预测。因此,它有很大潜力成为预测化学中的一种有价值工具。随着纳入更多官能团、持续改进模型以及增强数据资源,我们相信这种方法可能会发展成为化学预测的关键资源。
BASSOCIATED CONTENT
相关内容
Data Availability Statement
数据可用性声明
The computational models and data sets reported in this work will be made available on GitHub. https://github.com/ ChengchunLiu/IR-DIAZO-KETONE.
本工作中报告的计算模型和数据集将在GitHub上提供。https://github.com/ ChengchunLiu/IR-DIAZO-KETONE。
(a) Supporting Information
(a) 支持信息
The Supporting Information is available free of charge at https://pubs.acs.org/doi/10.1021/acs.analchem.4c01972.
支持信息可在https://pubs.acs.org/doi/10.1021/acs.analchem.4c01972免费获取。
Details on the construction of the data set (including data extraction and data set composition), experimental settings and training procedures, and additional experimental details (PDF)
数据集构建细节(包括数据提取和数据集组成)、实验设置和训练程序以及其他实验细节(PDF)
AUTHOR INFORMATION
作者信息
Corresponding Author
通讯作者
Fanyang Mo - School of Materials Science and Engineering, Peking University, Beijing 100871, China; AI for Science (AI4S)-Preferred Program, School of Advanced Materials, and Guangdong Provincial Key Laboratory of Nano-Micro Materials Research, Peking University Shenzhen Graduate School, Shenzhen 518055, China; © orcid.org/0000-0002- 4140-3020;
莫凡洋 - 北京大学材料科学与工程学院,北京 100871,中国;北京大学深圳研究生院先进材料学院人工智能促进科学(AI4S)优先计划及广东省纳米微材料研究重点实验室,深圳 518055,中国;© orcid.org/0000-0002- 4140-3020;
Authors
作者
Chengchun Liu - School of Materials Science and Engineering, Peking University, Beijing 100871, China; © orcid.org/0009-0002-5550-4145
刘丞军 - 北京大学材料科学与工程学院,北京 100871,中国;© orcid.org/0009-0002-5550-4145
Ruqiang Zou - School of Materials Science and Engineering, Peking University, Beijing 100871, China; AI for Science (AI4S)-Preferred Program and School of Advanced Materials, Peking University Shenzhen Graduate School, Shenzhen 518055, China; (C) orcid.org/0000-0003-0456- 4615
邹如强 - 北京大学材料科学与工程学院,北京 100871,中国;北京大学深圳研究生院先进材料学院人工智能促进科学(AI4S)优先计划,深圳 518055,中国;(C) orcid.org/0000-0003-0456-4615
Complete contact information is available at: https://pubs.acs.org/10.1021/acs.analchem.4c01972
完整的联系信息可在:https://pubs.acs.org/10.1021/acs.analchem.4c01972 查看
Author Contributions
作者贡献
F.M. and C.L. conceived the project, designed the method, and analyzed the results. C.L. organized and prepared structural data. R.Z. participated in the discussion and gave important suggestions. F.M. and C.L. wrote the paper. F.M. supervised the project.
F.M.和C.L.构思了该项目,设计了方法并分析了结果。C.L.组织并准备了结构数据。R.Z.参与了讨论并提出了重要建议。F.M.和C.L.撰写了论文。F.M.指导了该项目。
Notes
注释
The authors declare no competing financial interest.
作者声明不存在相互竞争的财务利益。
ACKNOWLEDGMENTS
致谢
This work was financially supported by the National Natural Science Foundation of China (Grant Nos. 22071004, 21933001 and 22150013). We thank the High-Performance
本研究得到了国家自然科学基金(项目编号:22071004、21933001和22150013)的资助。我们感谢
Computing Platform of Peking University for machine learning model training.
北京大学高性能计算平台为机器学习模型训练提供支持。
R REFERENCES
R参考文献
(1) Baiz, C. R.; et al. Chem. Rev. 2020, 120, 7152-7218.
(2) Coates, J. Encyclopedia of Analytical Chemistry; John Wiley & Sons, Ltd, 2006.
(3) Bellamy, L. The infra-red spectra of complex molecules; Springer Science & Business Media, 2013.
(4) Han, R.; Ketkaew, R.; Luber, S. J. Phys. Chem. A 2022, 126, 801- 812.
(5) Kovács, P.; Zhu, X.; Carrete, J.; Madsen, G. K. H.; Wang, Z. ApJ 2020, 902, 100.
(6) Margraf, J. T. Angew. Chem., Int. Ed. 2023, 62 (26), No. e202219170.
(7) Zhang, S.-Q.; Xu, L.-C.; Li, S.-W.; Oliveira, J. C. A.; Li, X.; Ackermann, L.; Hong, X. Chem.-Eur. J. 2023, 29, No. e202202834.
(8) Lin, J.; Mo, F. Artif. Intell. Chem. 2024, 2, 100035.
(9) Gastegger, M.; Behler, J.; Marquetand, P. Chem. Sci. 2017, 8, 6924-6935.
(10) Schütt, K. T.; Kessel, P.; Gastegger, M.; Nicoli, K. A.; Tkatchenko, A.; Müller, K.-R. J. Chem. Theory Comput. 2019, 15, 448-455.
(11) Gastegger, M.; Schütt, K. T.; Müller, K.-R. Chem. Sci. 2021, 12, 11473-11483.
(12) Zhang, Y.; Jiang, B. Nat. Commun. 2023, 14 (1), 6424.
(13) Ye, S.; Zhong, K.; Zhang, J.; Hu, W.; Hirst, J. D.; Zhang, G.; Mukamel, S.; Jiang, J. J. Am. Chem. Soc. 2020, 142, 19071-19077.
(14) Ren, H.; Li, H.; Zhang, Q.; Liang, L.; Guo, W.; Huang, F.; Luo, Y.; Jiang, J. Fundam. Res. 2021, 1, 488-494.
(15) Ng, L. M.; Simmons, R. Anal. Chem 1999, 71, 343-350.
(16) Smith, B. C. Infrared spectral interpretation: A systematic approach; CRC press, 2018.
(17) Bemis, G. W.; Murcko, M. A. J. Med. Chem. 1996, 39, 2887- 2893.
(18) Wang, Y.; Gu, Y.; Shun, J. Theoretically-Efficient and Practical Parallel DBSCAN. Proceedings of the 2020 ACM SIGMOD International Conference on Management of Data; ACM Digital Library: New York, NY, USA, 2020 25552571.
(19) Xu, H.; Lin, J.; Zhang, D.; Mo, F. Nat. Commun. 2023, 14 (1), 3095.
(20) Lundberg, S. M.; Erion, G.; Chen, H.; DeGrave, A.; Prutkin, J. M.; Nair, B.; Katz, R.; Himmelfarb, J.; Bansal, N.; Lee, S.-I. Nat. Mach. Intell. 2020, 2, 56-67.
(21) Stienstra, C. M. K.; Hebert, L.; Thomas, P.; Haack, A.; Guo, J.; Hopkins, W. S. J. Chem. Inf. Model. 2024, 64, 4613-4629.
(22) Zou, Z.; Zhang, Y.; Liang, L.; Wei, M.; Leng, J.; Jiang, J.; Luo, Y.; Hu, W. Nat. Comput. Sci. 2023, 3, 957-964.
(23) Akter, M.; Rupa, K.; Anbarasan, P. Chem. Rev. 2022, 122, 13108-13205.
(24) Dallinger, D.; Gutmann, B.; Kappe, C. O. Acc. Chem. Res. 2020, 53, 1330-1341.
(25) Hodgson, D. M.; Le Strat, F.; Avery, T. D.; Donohue, A. C.; Brückl, T. J. Org. Chem. 2004, 69, 8796-8803.
(26) Dallinger, D.; Pinho, V. D.; Gutmann, B.; Kappe, C. O. J. Org. Chem. 2016, 81, 5814-5823.
(27) Hatakeyama, S.; Bandow, H.; Okuda, M.; Akimoto, H. J. Phys. Chem. 1981, 85, 2249-2254.
(28) Deem, M. W.; Newsam, J. M. J. Am. Chem. Soc. 1992, 114, 7189-7198.
(29) White, E. H.; Aufdermarsh, C. A. J. J. Am. Chem. Soc. 1961, 83, 1174-1178.
(30) Staudinger, H.; Gaule, A. Ber. Dtsch. Chem. Ges. 1916, 49, 1897-1918.
(31) Pezacki, J. P.; Wood, P. D.; Gadosy, T. A.; Lusztyk, J.; Warkentin, J. J. Am. Chem. Soc. 1998, 120, 8681-8691.
(32) Pezacki, J. P.; Wagner, B. D.; Lew, C. S. Q.; Warkentin, J.; Lusztyk, J. J. Am. Chem. Soc. 1997, 119, 1789-1790.
(33) Alecu, I. M.; Zheng, J.; Zhao, Y.; Truhlar, D. G. J. Chem. Theory Comput. 2010, 6, 2872-2887.
(34) Arava, S.; Santra, S. K.; Pathe, G. K.; Kapanaiah, R.; Szpilman, A. M. Angew. Chem., Int. Ed. 2020, 59, 15171-15175.
(35) Li, H.; Bonderoff, S. A.; Cheng, B.; Padwa, A. J. Org. Chem. 2014, 79, 392-400.
CAS BIOFINDER DISCOVERY PLATFORMTM
CAS生物发现者发现平台TM
STOP DIGGING THROUGH DATA -START MAKING DISCOVERIES
停止在数据中挖掘 - 开始进行发现
CAS BioFinder helps you find the right biological insights in seconds
CAS生物发现者可帮助您在数秒内找到正确的生物学见解
Start your search
开始搜索